Related Experiment Video
Updated: Sep 10, 2025
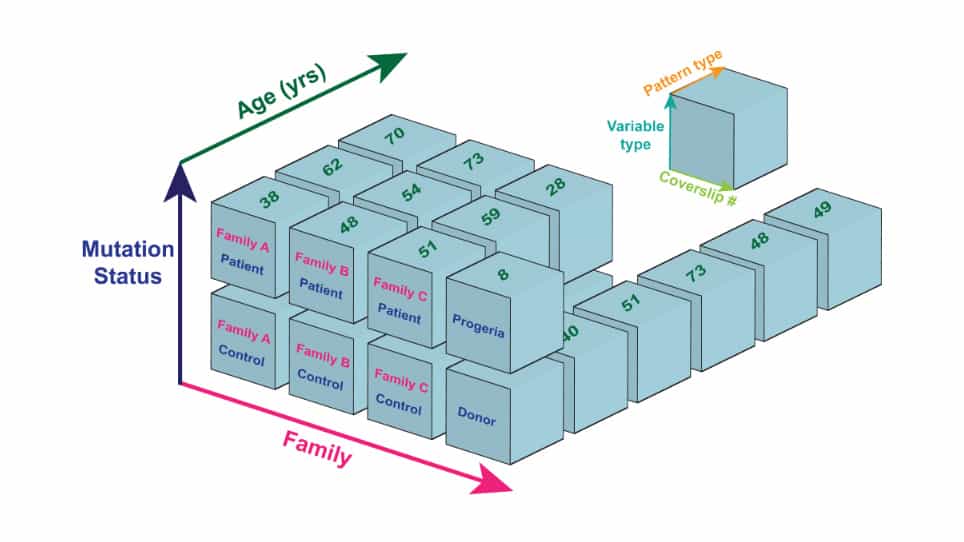

Databases to Efficiently Manage Medium Sized, Low Velocity, Multidimensional Data in Tissue Engineering
Published on: November 22, 2019
A scalable machine learning strategy for resource allocation in database
Fady Nashat Manhary1, Marghny H Mohamed2, Mamdouh Farouk1
1Department of Computer Science, Faculty of Computers and Information, Assiut University, Assiut, Egypt.

Abstract:
Modern cloud computing systems require intelligent resource allocation strategies that balance quality-of-service (QoS), operational costs, and energy sustainability. Existing deep Q-learning (DQN) methods suffer from sample inefficiency, centralization bottlenecks, and reactive decision-making during workload spikes. Transformer-based forecasting models such as Temporal Fusion Transformer (TFT) offer improved accuracy but introduce computational overhead, limiting real-time deployment. We propose LSTM-MARL-Ape-X, a novel framework integrating bidirectional Long Short-Term Memory (BiLSTM) for workload forecasting with Multi-Agent Reinforcement Learning (MARL) in a distributed Ape-X architecture. This approach enables proactive, decentralized, and scalable resource management through three innovations: high-accuracy forecasting using BiLSTM with feature-wise attention, variance-regularized credit assignment for stable multi-agent coordination, and faster convergence via adaptive prioritized replay. Experimental validation on real-world traces demonstrates 94.6% SLA compliance, 22% reduction in energy consumption, and linear scalability to over 5,000 nodes with sub-100 ms decision latency. The framework converges 3.2× faster than uniform sampling baselines and outperforms transformer-based models in both accuracy and inference speed. Unlike decoupled prediction-action frameworks, our method provides end-to-end optimization, enabling robust and sustainable cloud orchestration at scale.

Related Concept Videos
 01:29
Mechanistic Models: Compartment Models in Algorithms for Numerical Problem Solving
In individual population analyses, different algorithms are employed, such as Cauchy's method, which uses a...
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 01:12
Column Efficiency: Rate Theory
During elution, a solute molecule experiences numerous transitions between stationary and mobile phases, exhibiting irregular residence times in...
 01:12
Maximum Size of Aggregate