Related Experiment Video
Updated: Jan 16, 2026


Author Spotlight: Addressing Technical and Subjective Challenges in Measuring Classroom Attention
Published on: December 15, 2023
Consistency verification and interpretation of explainable AI for predicting annual home runs of professional
Shohei Shibata1, Yuto Kase2, Yusuke Yoshikawa2
1Global Equipment Product Department, Mizuno Corporation, Suminoe-ku, Osaka, 559-8510, Japan. shshibat@mizuno.co.jp.

Abstract:
This study aimed to verify and interpret a model for predicting the number of home runs per year using sensor data from professional baseball players during batting practice. A machine learning model was constructed using Random Forest from the bat kinematics and bat mass data of 41 professional baseball players collected by a bat-mounted sensor. Partial Dependence analysis and Feature Importance analysis by SHAP (SHapley Additive exPlanations) were used to explain the model's predictions. The predictive model showed that the bat speed, bat mass, and rotational acceleration are particularly important. The results indicated that a bat speed of 33.3 m/s and rotational acceleration exceeding 157 m/s2 exhibited a trend toward a rapid increase in the number of predicted home runs per year. The mass of the bat suggests that an optimum value exists at 0.91 kg. These results suggest that batters who are expected to hit a large number of home runs each year increase the acceleration at the beginning of their swing to produce high bat speed in a short period of time and achieve bat speeds of 33.3 m/s or more with a bat that is somewhat heavier.
Related Concept Videos
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:11
Residuals and Least-Squares Property
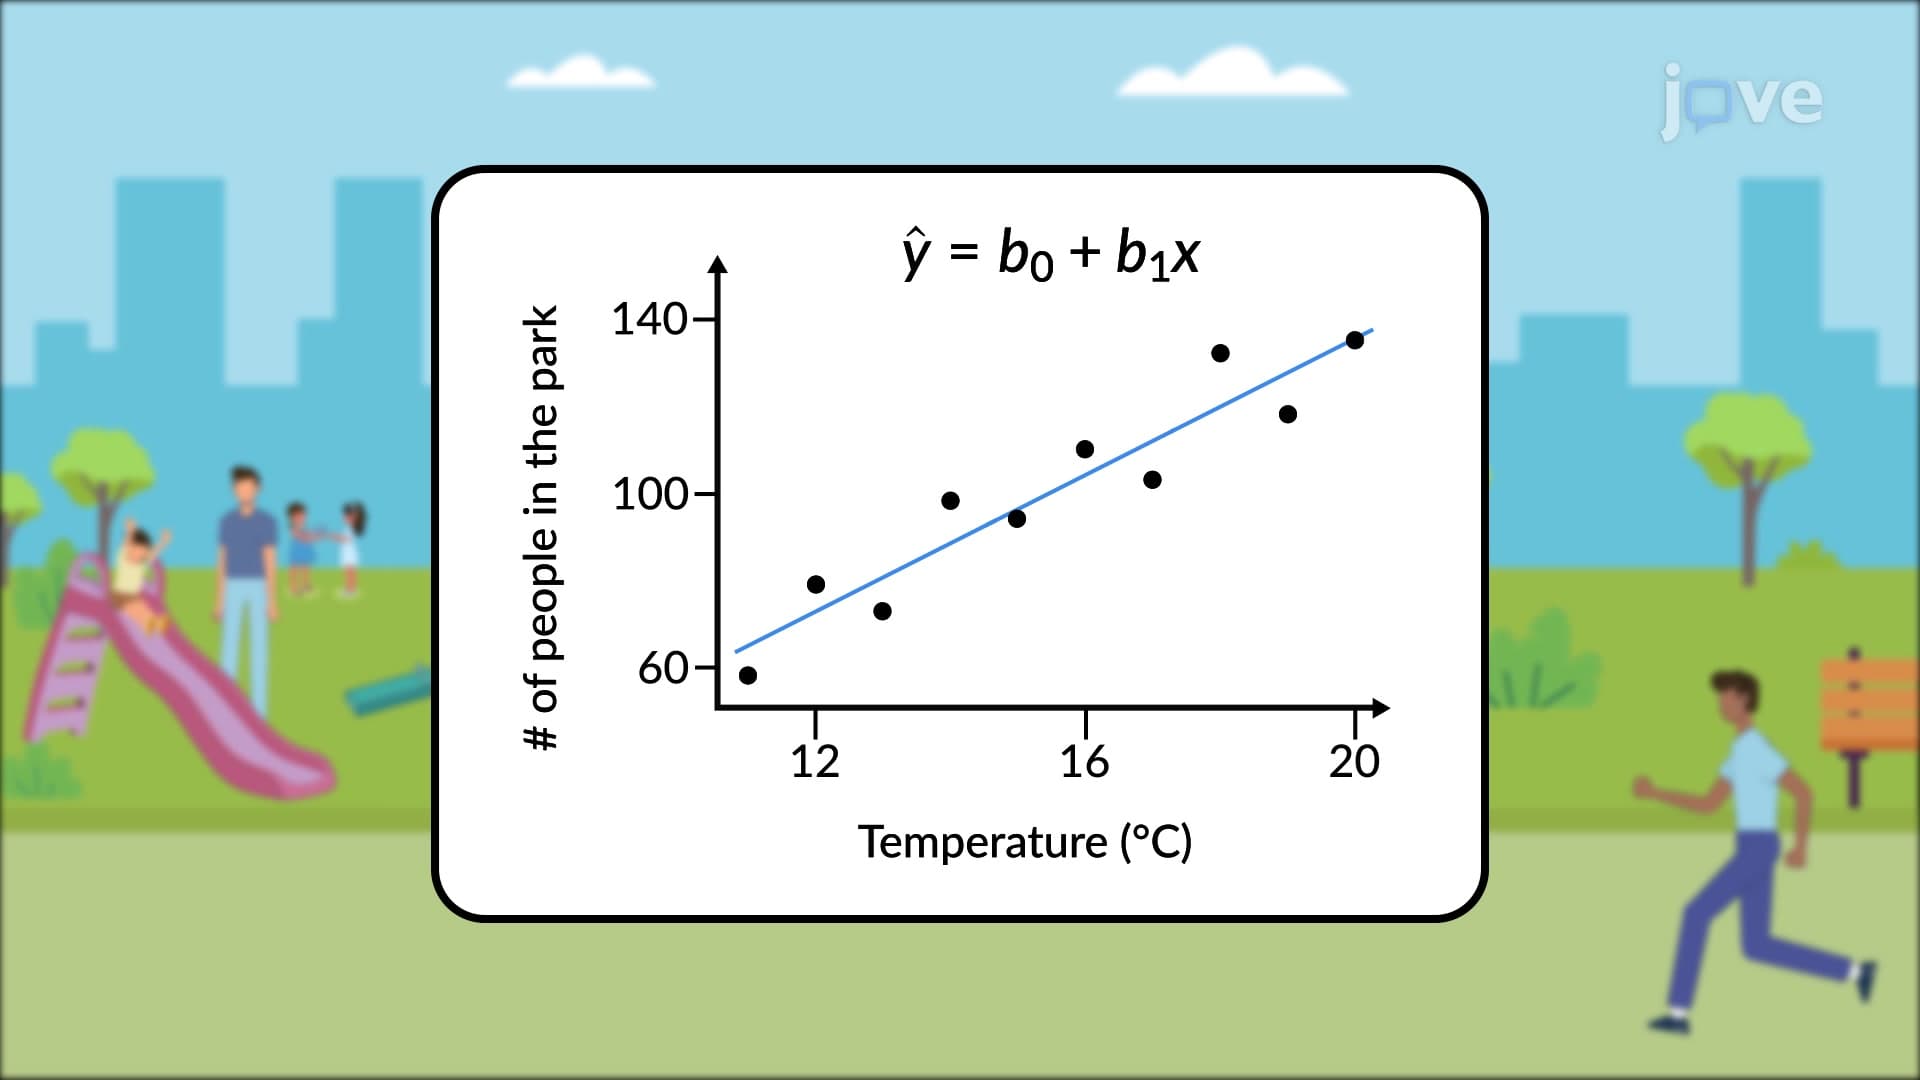
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:19
Variation
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...