Related Experiment Video
Updated: Jan 6, 2026

A Postoperative Evaluation Guideline for Computer-Assisted Reconstruction of the Mandible
Published on: January 28, 2020
Readability and performance of AI chatbot responses to frequently asked questions in maxillofacial prosthodontics
Soni Prasad1, Merve Koseoglu2, Stavroula Antonopoulou3
1Associate Professor, Adams School of Dentistry, University of North Carolina at Chapel Hill, Chapel Hill, NC.

Statement Of Problem:
Patients seeking information about maxillofacial prosthodontic care increasingly turn to artificial intelligence (AI)-driven chatbots for guidance. However, the readability, accuracy, and clarity of these AI-generated responses have not been adequately evaluated within the context of maxillofacial prosthodontics.
Purpose:
The purpose of this study was to assess and compare the readability and performance of chatbot-generated responses to frequently asked questions about intraoral and extraoral maxillofacial prosthodontics.
Material And Methods:
A total of 20 frequently asked intraoral and extraoral questions were collected from 7 maxillofacial prosthodontists. These questions were submitted to 4 AI chatbots: ChatGPT, Gemini, Copilot, and DeepSeek. A total of 80 responses were evaluated. Readability was assessed using the Flesch-Kincaid Grade Level (FKGL). Seven maxillofacial prosthodontists were calibrated to score the chatbot responses on 5 domains, relevance, clarity, depth, focus, and coherence, using a 5-point scale. The obtained data were analyzed using 2-way ANOVA with post hoc Tukey tests, Pearson correlation analyses, and intraclass correlation coefficients (ICCs) (α=.05).
Results:
FKGL scores differed significantly among chatbots (P=.002). DeepSeek had the lowest FKGL, indicating better readability, while ChatGPT had the highest. Word counts, relevance, clarity, content depth, focus, and coherence varied significantly among platforms (P<.005). ChatGPT, Gemini, and DeepSeek consistently scored higher, while Copilot had the lowest scores across all domains. For questions on intraoral prostheses, FKGL scores negatively correlated with word count (P=.013). For questions on extraoral prostheses, word count positively correlated with all qualitative metrics except for FKGL (P<.005).
Conclusions:
Significant differences were found in both readability and response quality among commonly used AI chatbots. Although the DeepSeek and ChatGPT platforms produced higher-quality content, none consistently met health literacy guidelines. Clinician oversight is essential when using AI-generated materials to answer frequently asked questions by patients requiring maxillofacial prosthodontic care.
More Related Videos
 05:49
Author Spotlight: Advancing CBCT and Digital Dental Image Integration with AI-Assisted Digitization
Published on: February 23, 2024
 05:54
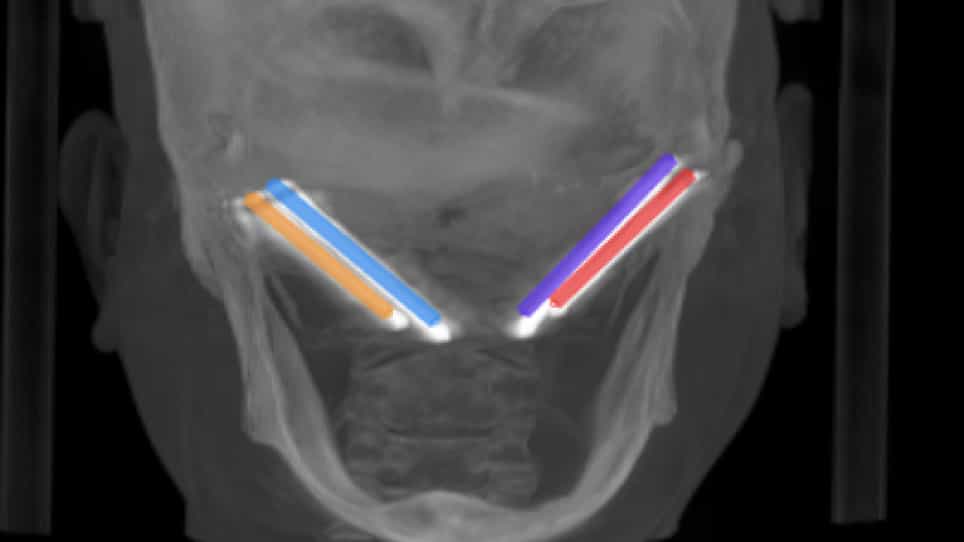
Real-Time Dynamic Navigation System for the Precise Quad-Zygomatic Implant Placement in a Patient with a Severely Atrophic Maxilla
Published on: October 18, 2021
