Related Experiment Video
Updated: Jan 16, 2026
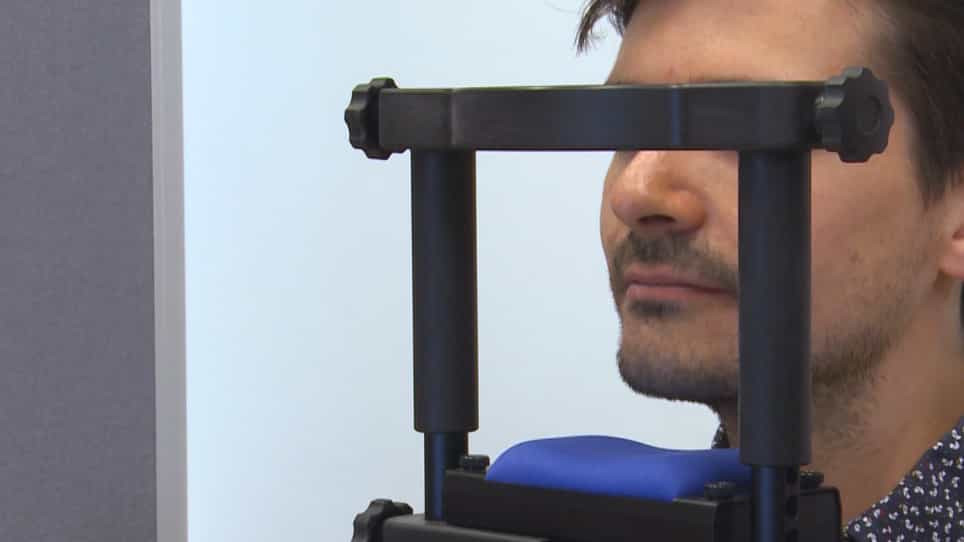

Eye Tracking During Visually Situated Language Comprehension: Flexibility and Limitations in Uncovering Visual Context Effects
Published on: November 30, 2018
Mutual contextual relation-guided dynamic graph networks for cross-modal image-text retrieval
G Sucharitha1, B J D Kalyani2, Akella S Narasimha Raju3
1Department of Computer Science and Engineering, Anurag University, Hyderabad, Telangana, India. sucharithasu@gmail.com.

Abstract:
With the rapid growth of multimodal data on the web, cross-modal retrieval has become increasingly important for applications such as multimedia search and content recommendation. It aims to align visual and textual features to retrieve semantically relevant content across modalities. However, this remains a challenging task due to the inherent heterogeneity and semantic gap between image and text representations. This paper proposes mutual contextual relation-guided dynamic graph network that integrates ViT, BERT and GCNN to construct a unified and interpretable multimodal representation space for image-text matching. The ViT and BERT features are structured into a dynamic cross-modal feature graph (DCMFG), where nodes represent image features and text features, and edges are dynamically updated based on mutual contextual relations that is neighboring relations extracted using KNN. The attention-guided mechanism refines graph connections, ensuring adaptive and context-aware alignment between modalities. The mutual contextual relation helps in identifying relevant neighborhood structures among image and text nodes, enabling the graph to capture both local and global associations. Meanwhile, the attention mechanism dynamically weights edges, enhancing the propagation of important cross-modal interactions. This emphasizes meaningful connections or edges among different modality nodes, improving the interpretability by revealing how image regions and text features interact. This approach overcome the limitations of existing models that rely on static feature alignment and insufficient modeling of contextual relationships. Experimental results on benchmark datasets MirFlickr-25K and NUS-WIDE are used to demonstrate significant performance improvements over state-of-the-art methods in precision and recall, validating its effectiveness for cross-modal retrieval.
More Related Videos
 05:47
Evidence-based Knowledge Synthesis and Hypothesis Validation: Navigating Biomedical Knowledge Bases via Explainable AI and Agentic Systems
Published on: June 13, 2025
 03:14
Augmenting Large Language Models via Vector Embeddings to Improve Domain-Specific Responsiveness
Published on: December 6, 2024
Related Concept Videos
 01:06
Collisions in Multiple Dimensions: Problem Solving
A small car of mass 1,200 kg traveling east at 60 km/h collides at an intersection with a truck of mass 3,000 kg traveling due north at 40 km/h. The two vehicles are locked together. What is the...
 01:45
ER Retrieval Pathway
The ER uses many checkpoints to prevent the entry of incorrectly folded or a resident protein as cargo onto a transport vesicle. These mechanisms...