Related Experiment Videos
Recommendation of deep reinforcement learning based on value function considering error reduction
JinLian Zhou1,2, DeRong Shen3, Ying Guo4
1School of Computer Science and Engineering, Northeastern University, Shenyang, 110819, China. 543518214@qq.com.

Abstract:
Deep reinforcement learning (DRL) algorithms have been widely applied in user cold-start recommender systems because they can gradually capture users' dynamic interest preferences. Deep Q-Networks (DQN) have become the most popular reinforcement learning (RL) method due to their simple update strategy and excellent performance. In many user cold-start scenarios, the action space is gradually reduced to avoid recommending duplicate items to users. However, current DQN-based RL recommender systems output the entire action space fixedly, inevitably leading to discrepancies with the gradually shrinking action space. This paper demonstrates that such discrepancies cause a decrement error in the action space corresponding to the temporal difference (TD) in the original RL, rendering standard DQN reinforcement learning methods inaccurate in Q-value estimation. Moreover, in long-term recommendation scenarios, the differences in the lengths of interactions recommended to different users are significant, making it difficult to ignore such errors, thereby challenging the applicability of these methods in scenarios where the action space gradually reduces. To address this issue, this paper introduces a new algorithm called Q-AD (Q-learning Action Decrease), which is based on DQN and aims to mitigate the reduction error in the action space by buffering the Q-value estimation error at each update. Q-AD augments the standard DQN with an error reduction term for TD updates. Through experiments, it was observed that the Q-AD algorithm significantly reduces value estimation errors and achieves better accuracy and efficiency compared to previous methods across different datasets.
Related Concept Videos
 01:23
Reinforcement
Positive reinforcement occurs when a behavior is followed by the presentation of a rewarding stimulus, increasing the frequency of that behavior. For example:
 01:09
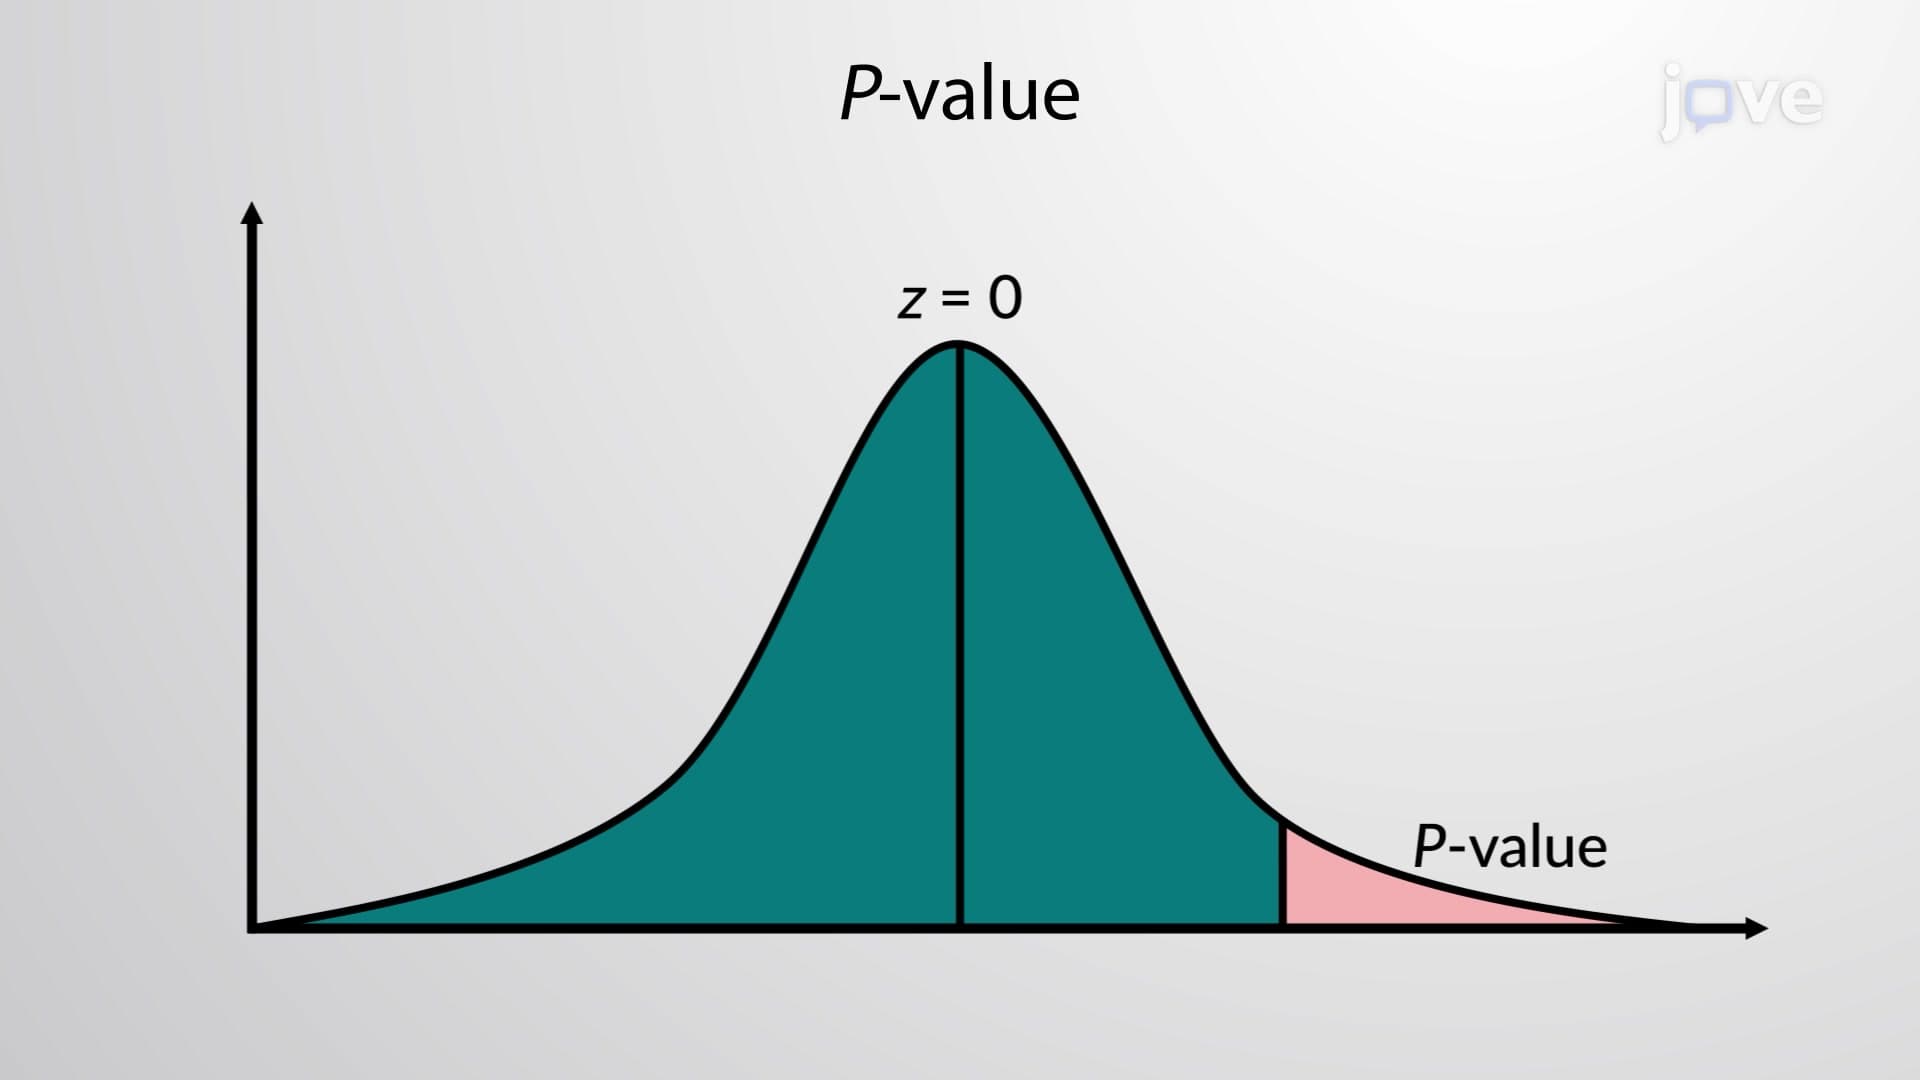
Decision Making: P-value Method
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
 01:14
Avoidance Learning and Learned Helplessness
Avoidance learning occurs when an organism learns that a specific behavior can prevent an unpleasant outcome. For example, a student who receives a bad grade may start studying harder to avoid future poor grades. This behavior persists even when the negative outcome is no longer present. Avoidance learning is powerful because it maintains behavior in the absence of the...
 01:12
Observational Learning
 01:18
Introduction to Learning
In contrast to learned behaviors, unlearned behaviors such as crying, sexual...
 01:24
Generalization, Discrimination, and Extinction
Generalization occurs when a behavior reinforced in one context is performed in similar situations. For instance, a student who studies diligently for calculus and receives excellent grades might apply the same study habits to psychology and history, expecting similar results. Generalization shows how learning in one setting can influence behavior in...