Related Experiment Video
Updated: Jul 18, 2026
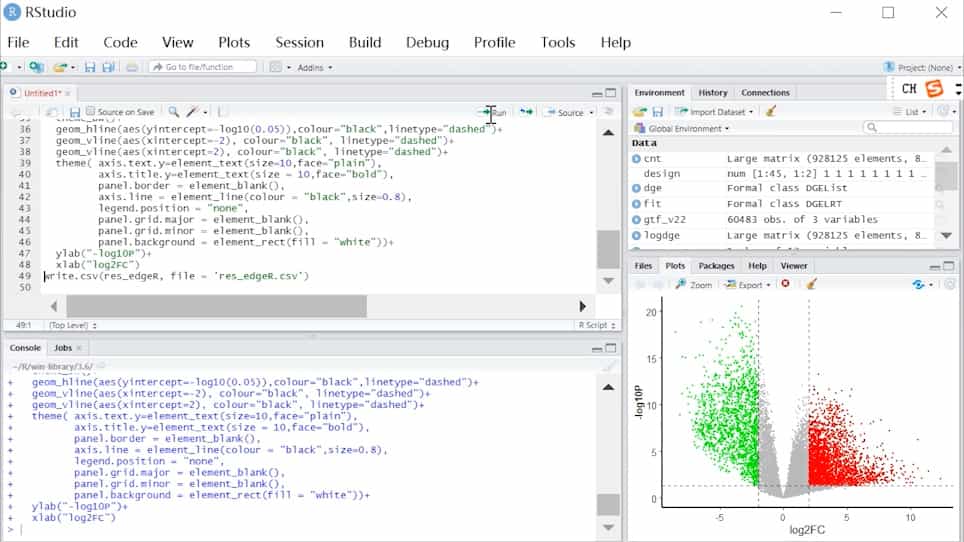

Three Differential Expression Analysis Methods for RNA Sequencing: limma, EdgeR, DESeq2
Published on: September 18, 2021
ClusterDE: A Statistical Software Package for Removing Double-Dipping Bias in Post-Clustering Differential Expression
Christy Lee1, Dongyuan Song2, Siqi Chen1
1Department of Statistics and Data Science, University of California, Los Angeles, California, USA.

Abstract:
Typical pipelines for single-cell and spatial transcriptomics involve clustering cells or spatial spots, followed by post-clustering differential expression (DE) analysis to identify marker genes for annotating clusters as cell types or spatial domains. However, using the same data for both clustering and DE analysis-a problem known as double-dipping-can lead to spurious detection of DE genes. In particular, over-clustering can produce artificial clusters that are incorrectly interpreted as distinct cell types or spatial domains. To address this issue, the ClusterDE R package implements a statistical method using a synthetic null dataset, which consists of a single homogeneous cell population or spatial domain but is constructed to match the real dataset in terms of gene means, variances, and gene-gene rank correlations. By serving as a parallel negative control, the synthetic null data allow users to identify and remove false-positive DE genes arising from double-dipping. This article introduces the ClusterDE R package and provides practical guidance on installation and usage for more reliable marker gene detection following clustering.