Related Experiment Video
Updated: Jan 15, 2026
Inverse Probability of Treatment Weighting Propensity Score using the Military Health System Data Repository and National Death Index
Published on: January 8, 2020
Should we synthesize more than we need: impact of synthetic data generation for high-dimensional cross-sectional
Lisa Pilgram1,2,3, Samer El Kababji2, Dan Liu1,2
1School of Epidemiology and Public Health, University of Ottawa, Ottawa, Ontario, K1H 8M5, Canada.

Objective:
In medical research and education, generative artificial intelligence/machine learning (AI/ML) models to synthesize artificial medical data can enable the sharing of high-quality data while preserving the privacy of patients. Given that such data is often high-dimensional, a relevant consideration is whether to synthesize the entire dataset when only a task-relevant subset is needed. This study evaluates how the number of variables in training impacts fidelity, utility, and privacy of the synthetic data (SD).
Material And Methods:
We used 12 cross-sectional medical datasets, defined a downstream task with corresponding core variables, and derived 6354 variants by adding adjunct variables to the core. SD was generated using 7 different generative models and evaluated for fidelity, downstream utility, and privacy. Mixed-effect models were used to assess the effect of adjunct variables on the respective evaluation metric, accounting for the medical dataset as a random component.
Results:
Fidelity was unaffected by the number of adjunct variables in 5/7 SDG models. Similarly, downstream utility remained stable in 6/7 (predictive task) and 5/7 (inferential task) SDG models. Where significant effects were observed, they were minimal, resulting, for example, in a 0.05 decrease in Area under the Receiver Operating Characteristic curve (AUROC) when adding 120 variables. Privacy was not impacted by the number of adjunct variables.
Discussion:
Our findings show that fidelity, utility, and privacy are preserved when generating a more comprehensive medical dataset than the task-relevant subset.
Conclusion:
Our findings support a cost-effective, utility, and privacy-preserving way of implementing SDG into medical research and education.
More Related Videos
 09:43
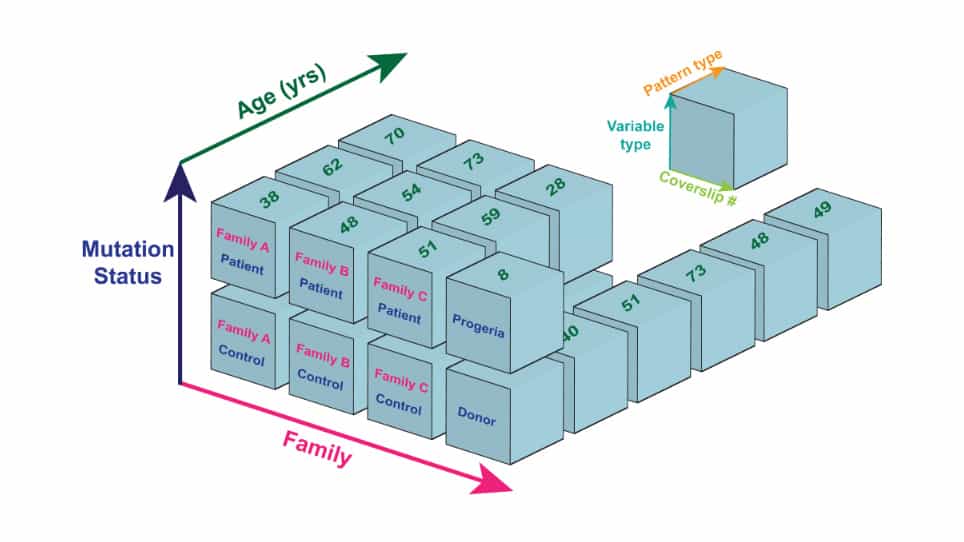
Databases to Efficiently Manage Medium Sized, Low Velocity, Multidimensional Data in Tissue Engineering
Published on: November 22, 2019
 08:51
Author Spotlight: Integrated Multi-Omics Analysis for Unveiling Multicellular Immune Signatures in Clinical Heart Attack Cohorts
Published on: September 20, 2024
Related Concept Videos
 01:25
Statistical Methods for Analyzing Epidemiological Data
 01:19
Data: Types and Distribution
Distributions in...
 01:12
Analysis of Population Pharmacokinetic Data
 01:11
Genome-wide Association Studies-GWAS
GWAS does not require the identification of the target gene involved in...
 01:20
Biostatistics: Overview
Discrete variables are...
 02:55
Synthetic Biology
Golden rice
Golden rice is a genetically modified...