
Statistical testing of agreement in overlap-based performance between an AI segmentation device and a multi-expert
Tingting Hu1, Berkman Sahiner1, Shuyue Guan1
1U.S. Food and Drug Administration, Silver Spring, Maryland, United States.

Purpose:
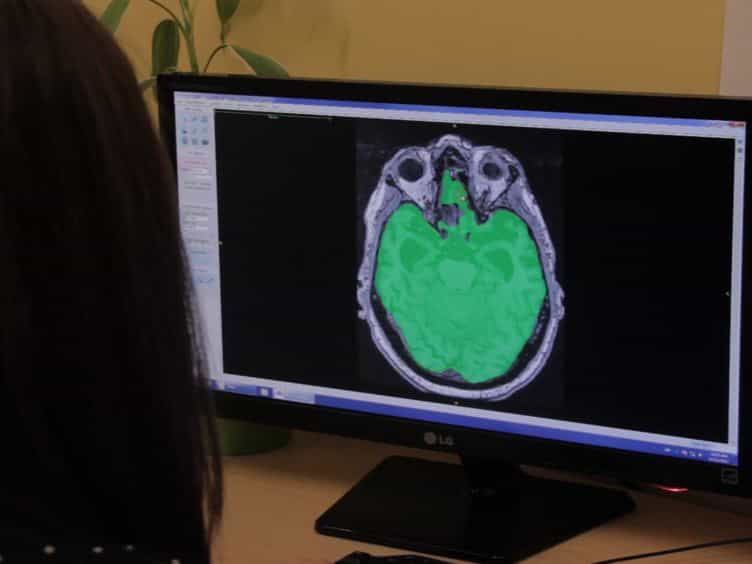
Artificial intelligence (AI)-based medical imaging devices often include lesion or organ segmentation capabilities. Existing methods for segmentation performance evaluation compare AI results with an aggregated reference standard using accuracy metrics such as the Dice coefficient or Hausdorff distance. However, these approaches are limited by lacking a gold standard and challenges in defining meaningful success criteria. To address this, we developed a statistical method to assess agreement between an AI device and multiple human experts without requiring a reference standard.
Approach:
We propose a paired-testing method to evaluate whether an AI device's segmentation performance significantly differs from that of multiple human experts. The method compares device-to-expert dissimilarity with expert-to-expert dissimilarity, avoiding the need for a reference standard. We validated the method through (1) statistical simulations where the Dice coefficient performance is either shared ("overlap agreeable") or not shared ("overlap disagreeable") between the device and experts; (2) image-based simulations using 2D contours with shared or nonshared transformation parameters (transformation agreeable or disagreeable). We also applied the method to compare an AI segmentation algorithm with four radiologists using data from the Lung Image Database Consortium.
Results:
Statistical simulations show the method controls type I error ( ) for overlap-agreeable and type II error ( ) for overlap-disagreeable scenarios. Image-based simulations show acceptable performance with a mean type I error of 0.07 (SD 0.03) for transformation-agreeable and a mean type II error of 0.07 (SD 0.18) for transformation-disagreeable cases.
Conclusions:
The paired-testing method offers a new tool for assessing the agreement between an AI segmentation device and multiple human expert panelists without requiring a reference standard.

Related Concept Videos
 01:13
Multiple Comparison Tests
It would be easy to compare two samples using a significance alpha level of 0.05. In other words, there is only one sample pair to be compared. However, it would be difficult to identify a significantly different sample if the number...
 01:28
Introduction to Nonparametric Statistics
One of...
 01:29
Measures of Intelligence
Validity refers to how well a test measures what it claims to measure. An intelligence test should accurately assess intelligence rather than another characteristic, like anxiety. Criterion validity is one way to evaluate this; it...