Related Experiment Video
Updated: May 2, 2026
Combining Eye-tracking Data with an Analysis of Video Content from Free-viewing a Video of a Walk in an Urban Park Environment
Published on: May 7, 2019
Reducing annotation burden in physical activity research using vision language models
Abram Schönfeldt1, Benjamin Maylor1, Xiaofang Chen2
1Department of Population Health, University of Oxford, Oxford, UK.

Abstract:
Data from wearable devices collected in free-living settings, and labelled with physical activity behaviours compatible with health research, are essential for both validating existing wearable-based measurement approaches and developing novel machine learning approaches. One common way of obtaining these labels relies on laborious human annotation of sequences of images captured by body-worn cameras. The aim of this study was to investigate whether open-source vision-language models could accurately annotate activity intensity classes in wearable camera-based validation studies, thereby reducing the annotation burden. We compared the performance of three vision language models and two discriminative models on two free-living validation studies with 161 and 111 participants, collected in Oxfordshire, United Kingdom and Sichuan, China, respectively, using the Autographer (OMG Life, defunct) wearable camera. We found that the best open-source vision-language model (VLM) and fine-tuned discriminative model (DM) achieved comparable performance when predicting sedentary behaviour from single images on unseen participants in the Oxfordshire study; median F1-scores: VLM = 0.89 (0.84, 0.92), DM = 0.91 (0.86, 0.95). Performance declined for light [VLM = 0.60 (0.56, 0.67), DM = 0.70 (0.63, 0.79)], and moderate-to-vigorous intensity physical activity [VLM = 0.66 (0.53, 0.85); DM = 0.72 (0.58, 0.84)]. When applied to the external Sichuan study, performance fell across all intensity categories, with median Cohen's κ scores falling from 0.54 (0.49, 0.64) to 0.26 (0.15, 0.37) for the VLM, and from 0.67 (0.60, 0.74) to 0.19 (0.10, 0.30) for the DM. Freely available computer vision models could help annotate sedentary behaviour, typically the most prevalent activity of daily living, from wearable camera images within similar populations to seen data, reducing the annotation burden when using cameras as the source of ground-truth.
Related Concept Videos
 01:27
Exercise and Muscle Performance
Endurance exercises
Endurance exercises involve running, swimming, or cycling, which require repetitive movements with low force output. When a person engages in endurance exercise, a few noticeable changes occur in their skeletal muscles. For instance, the number of capillaries...
 01:09
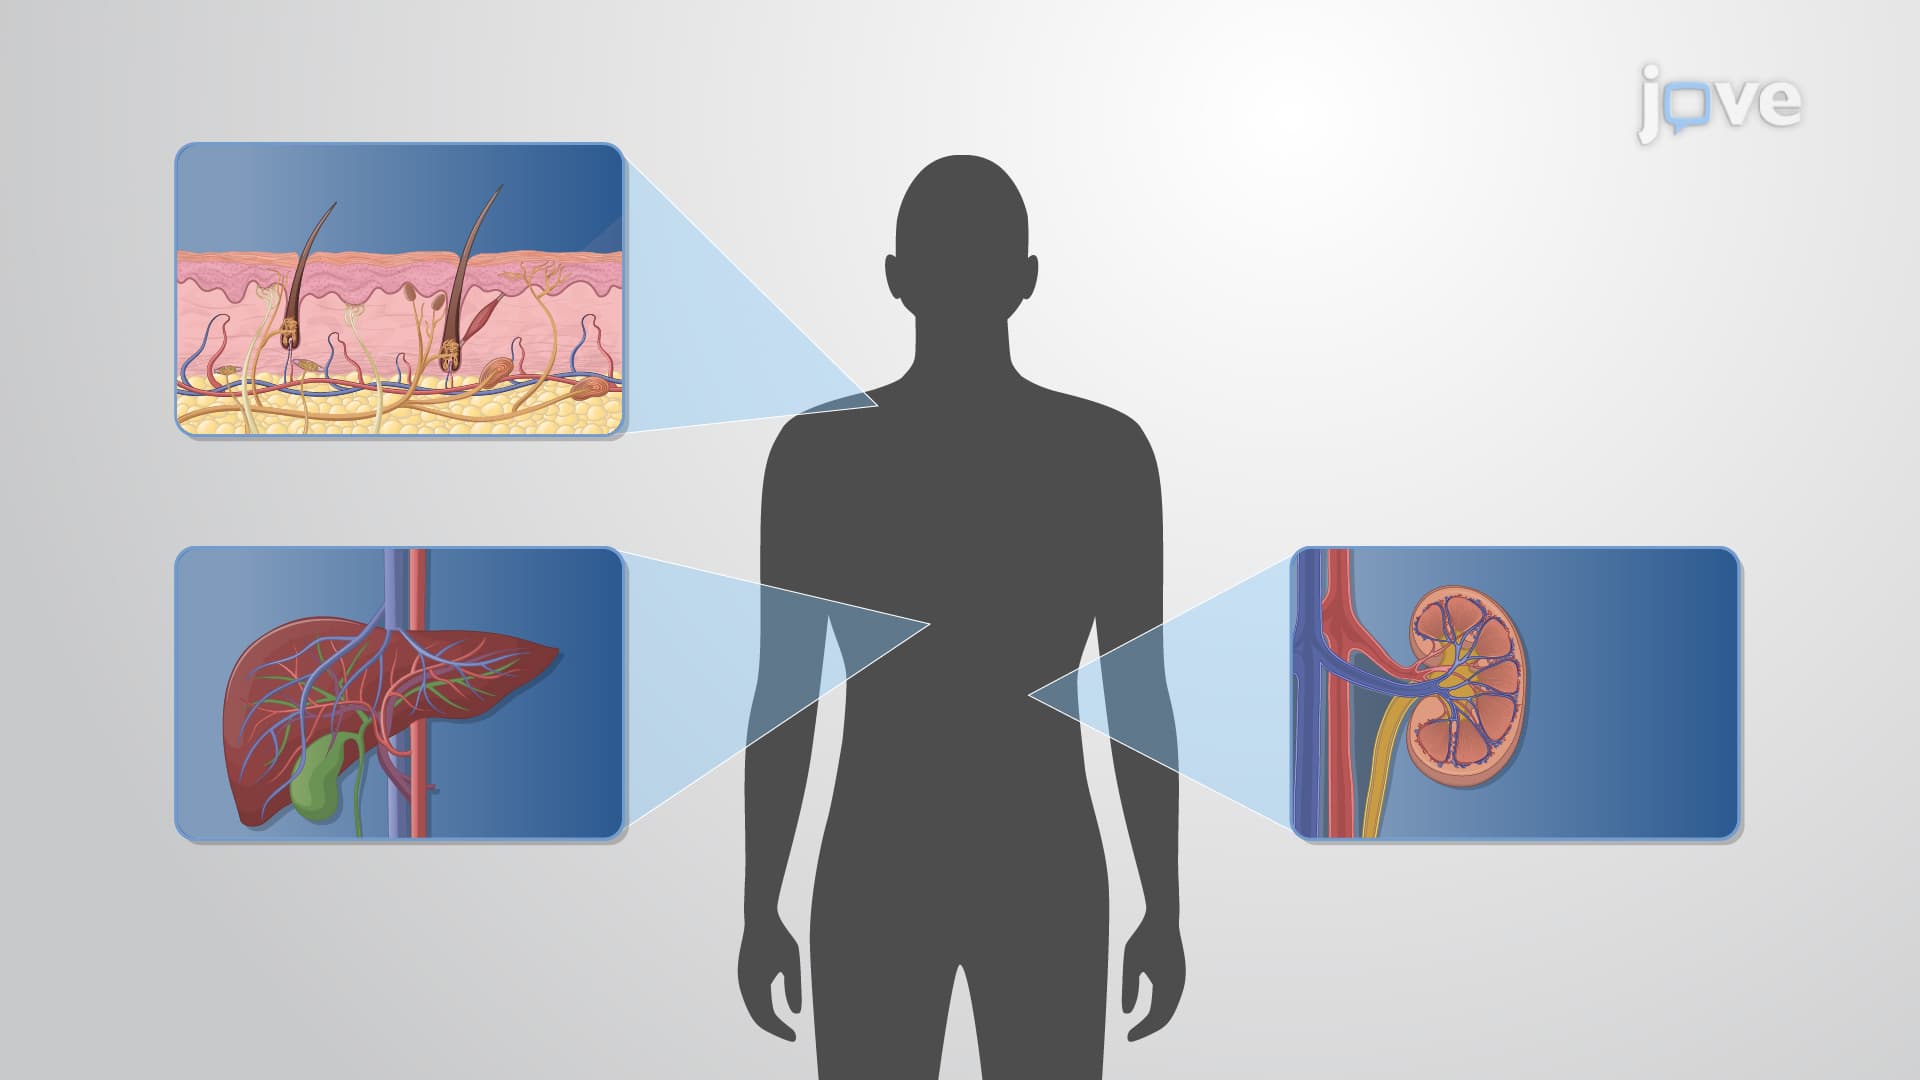
Clearance Models: Physiological Models
The organ's clearance rate depends on the blood flow to the organ and the extraction ratio (E). The extraction ratio describes the organ's...