Related Experiment Video
Updated: Jan 12, 2026


Augmenting Large Language Models via Vector Embeddings to Improve Domain-Specific Responsiveness
Published on: December 6, 2024
[Assessing the accuracy and comprehensiveness of large language models in responding to patient inquiries on placenta
1Department of Obstetrics and Gynecology, Guangdong Provincial Key Laboratory of Major Obstetric Diseases; Guangdong Provincial Clinical Research Center for Obstetrics and Gynecology; Guangdong-Hong Kong-Macao Greater Bay Area Higher Education Joint Laboratory of Maternal-Fetal Medicine; the Third Affiliated Hospital, Guangzhou Medical University, Guangzhou 510150, China.

Abstract:
Objective: To explore the accuracy and comprehensiveness of responses from four large language models [ChatGPT-3.5 (Model A), ChatGPT-4.0 (Model B), ChatGPT-4o (Model D) developed by OpenAI in the United States, and a domestically developed Obstetric artificial intelligence assistant robot (Model C)] to inquiries from patients with placenta accreta spectrum disorders and their families. Methods: A prospective study was conducted from June 2024 to March 2025, involving 25 pairs of patients and their families and 8 obstetric experts at the Third Affiliated Hospital of Guangzhou Medical University. Sixteen questions commonly asked by patients and their families regarding placenta accreta spectrum disorders were collected, covering six disease-related areas such as disease mechanism, risk factors, clinical symptoms, diagnosis, pregnancy management, and prognosis. A physician then input all the questions into the four different large language models to obtain their responses. The responses were randomized and independently evaluated by four maternal-fetal medicine physicians using a three-point Likert scale and a six-point Likert scale to assess the accuracy of the responses. The majority consensus method was used to determine the final rating for each model's response. For responses rated as "good" and scored 5 or above on the six-point Likert scale, a three-point Likert scale was further used to assess the comprehensiveness of the content. The accuracy and comprehensiveness of the 4 large language models was compared. Results: Significant differences in accuracy were observed among the four large language models (P=0.005). 25% (4/16) of Model A responses were rated as "good", which was lower than the 75% (12/16) for both Model B and Model D (both P<0.05). The comprehensiveness score for Model A was 1.8 (1.5, 2.0), for Model B was 2.0 (1.8, 2.0), for Model C was 2.3 (2.0, 2.3), and for Model D was 2.6 (2.3, 2.7). There were statistically significant differences in comprehensiveness scores among the four large language models (P<0.001). Pairwise comparisons showed that Model D was significantly more comprehensive than Model A (P=0.004) and Model B (P<0.001). Conclusions: Significant variations exist in both the accuracy and comprehensiveness of responses from the four large language models to questions in six areas related to placenta accreta spectrum disorders. Model D performs better in both aspects. Model C has a better performance in comprehensiveness, but its accuracy needs further improvement.
More Related Videos

Related Concept Videos
 01:28
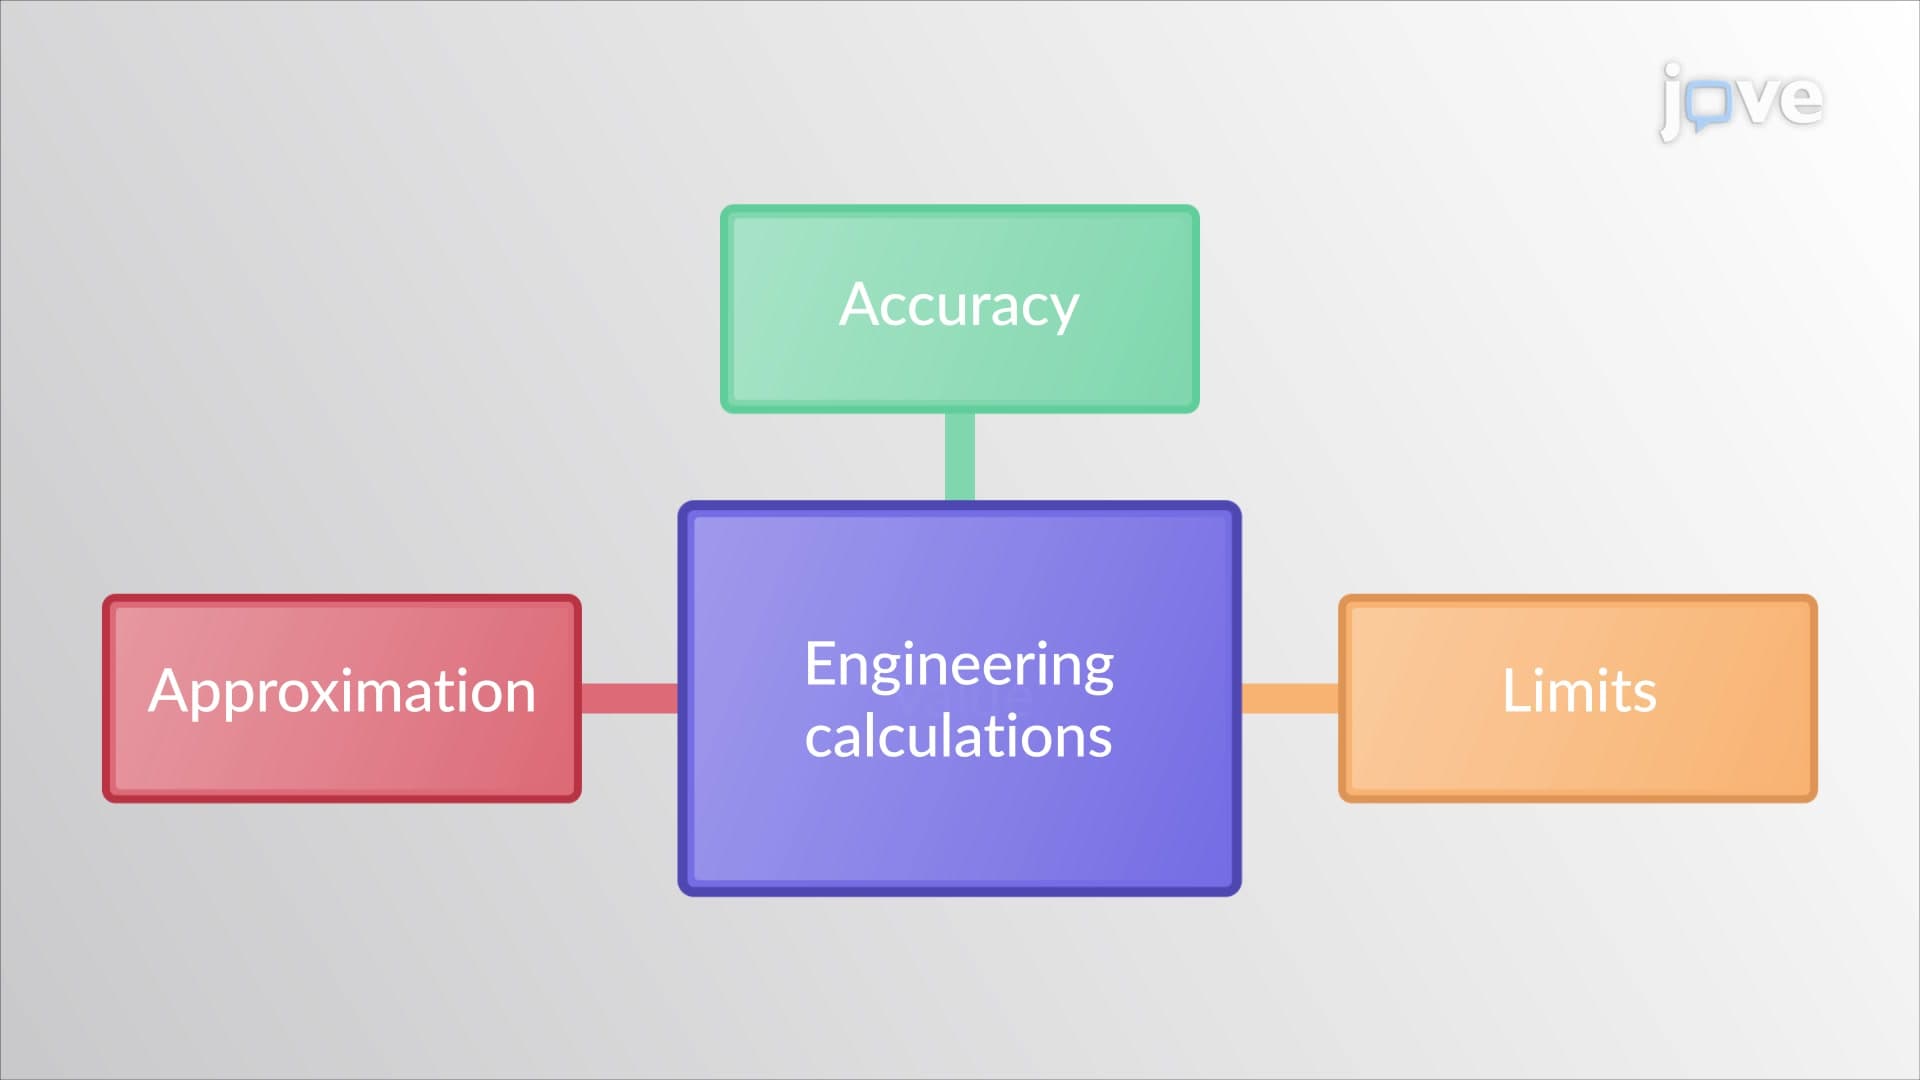
Accuracy, limits, and approximation
Accuracy is defined as the closeness of the measured value to the true or actual value. In engineering mechanics, repeated measurements are taken during theoretical or experimental analyses to ensure that the result is precise and accurate.
The accuracy of any solution is based on the...
 02:07
Improving Translational Accuracy
02:07Improving Translational Accuracy
 01:21
Health Literacy
 01:13
Sensitivity, Specificity, and Predicted Value
Sensitivity is the...
 01:21
Barriers to Effective Communication II
Cultural barriers:
Differences in values, beliefs, religion, knowledge, and tradition can significantly impact communication. Awareness of nonverbal cues is critical, especially when conversing with a patient from a different culture. What appears appropriate in one culture may be inappropriate in another.
Semantic barriers:
As a result of their tendency to use...