Related Experiment Video
Updated: Jan 11, 2026

The Innovation Arena: A Method for Comparing Innovative Problem-Solving Across Groups
Published on: May 13, 2022
Comprehensive dataset of global innovation index panel data (2013-2022): Clustering with K-means and principal
Edilvando Eufrazio1,2, Helder Costa2
1Instituto Nacional de Tecnologia, Av. Venezuela, 82, Rio de Janeiro, 20081-312, RJ, Brazil.

Abstract:
Over the last decade, innovation has become a focal point for policymakers, business leaders, and researchers worldwide. In that context, this dataset draws on the annual Global Innovation Index (GII), compiled by the World Intellectual Property Organization (WIPO) and available on the World Bank's Prosperity Data360 portal, to offer a refreshed view of national innovation landscapes. It covers 118 economies with complete data from 2013 through 2022, organized into seven core pillars: Institutions, Human Capital and Research, Infrastructure, Market Sophistication, Business Sophistication, Knowledge and Technology Outputs, and Creative Outputs. Although the dataset also includes overall GII scores and Innovation Input/Output Sub-Indices for each year, those aggregated measures were not used in clustering or Principal Component Analysis (PCA) to preserve the detail of the seven pillars. To identify economies with similar innovation characteristics, we used the K-means algorithm, and the Elbow Method showed that five clusters worked best. We then applied this five-cluster framework in four different ways: focusing on input pillars only, focusing on output pillars only, combining all pillars, and using a version enhanced by Principal Component Analysis (PCA). PCA was introduced to reduce dimensionality and sharpen the divisions between clusters, which led to additional cluster labels for each scenario. Because it offers both breadth and depth in its indicators, this dataset can be especially helpful for those examining how different nations innovate, gauging where they stand in comparison to peers, or investigating longer-term trends. This dataset is particularly helpful for researcher, policymaker, or professional seeking solid data on innovation; the information here can inform strategic thinking and support evidence-based decision-making.
More Related Videos
 07:50
Global and Current Research Trends of Single-Cell Sequencing in Cancer: A Bibliometric and Visualization Study
Published on: April 18, 2025
 09:01
A Method for Investigating Age-related Differences in the Functional Connectivity of Cognitive Control Networks Associated with Dimensional Change Card Sort Performance
Published on: May 7, 2014
Related Concept Videos
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 01:08
Outliers and Influential Points
 01:11
Variability: Analysis
The range is a simple measure of variability, indicating the difference between the highest and...
 01:10
Central Tendency: Analysis
The mean is one such measure, calculated by totaling all values in a dataset and dividing by the number of values. For instance, the mean blood pressure reading (120, 130, 140, 150) would be 135. However, the mean can be affected by extreme values or outliers.
The median, another measure,...
 02:01
Factorial Design
 01:10
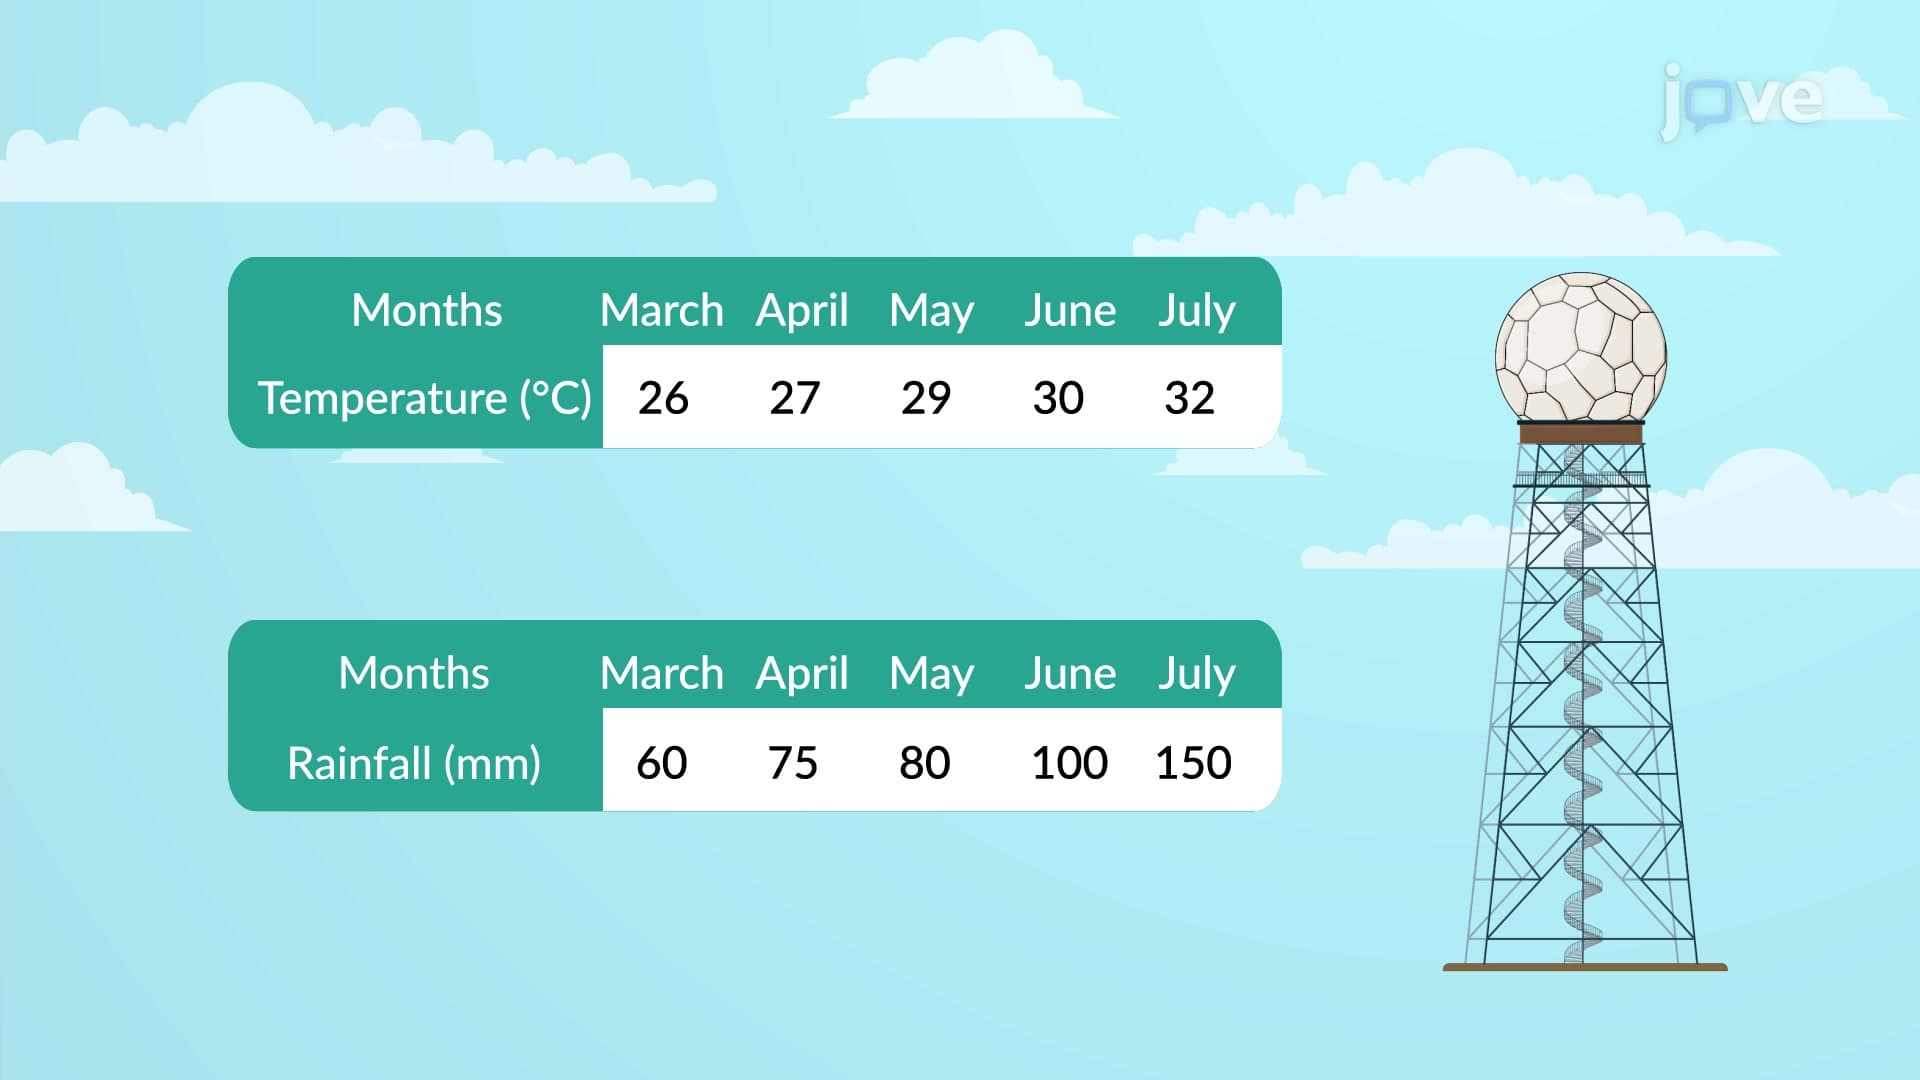
Coefficient of Variation
The coefficient of variation is a practical statistical tool in finance. It allows investors to assess the volatility or...