Using machine learning to predict future foster care admission
Ari Ne'eman1, Alex Brooks2, Kellie Hans-Green2
1Department of Health Policy and Management, Harvard T.H. Chan School of Public Health, Boston, MA 02115, United States.

Insights
Machine learning models using social determinants of health (SDOH) data can predict children at risk of foster care admission, enabling early intervention. This approach significantly improves prediction accuracy compared to models without SDOH factors.
Area of Science:
- Public Health
- Health Informatics
- Social Science
Background:
- Foster care admissions are a significant source of trauma for children and families, leading to adverse outcomes.
- Identifying at-risk children early is crucial for implementing preventative measures and diversion strategies.
Purpose of the Study:
- To assess the effectiveness of machine learning (ML) methods in predicting children at high risk for future foster care admission.
- To evaluate the impact of social determinants of health (SDOH) data on prediction accuracy.
Main Methods:
- Utilized claims data from children and linked adults in an Ohio Medicaid health plan.
- Incorporated individual and geographic social determinants of health (SDOH) factors.
- Compared a gradient-boosted tree ML algorithm against logistic regression for predictive performance.
Main Results:
- The ML model identified 2408 children (1.32%) at risk, with 1599 entering foster care within a year (PPV 66.4%).
- Models incorporating SDOH data demonstrated substantially higher accuracy (PPV 84.72%) compared to those without (PPV 27.44%).
- The gradient-boosted tree model outperformed logistic regression in predicting foster care admissions.
Conclusions:
- Social determinants of health (SDOH) are critical factors in predicting foster care admission.
- Machine learning holds significant potential for facilitating early interventions to prevent unnecessary foster care placements.
- Integrating ML and SDOH data can enhance child welfare services and support family stability.
Introduction:
Foster care admissions are highly traumatic for children and their families, often causing serious adverse outcomes. We seek to assess the viability of machine learning methods to identify children at risk of future foster care admission to facilitate diversion.
Methods:
We use claims data for children enrolled in a Medicaid health plan in Ohio as well as for linked adults, along with data on individual and geographic social determinants of health (SDOH) factors. We test the performance of a gradient-boosted tree machine learning algorithm as compared to logistic regression. Of the children, 85% have SDOH data available.
Results:
Using a gradient-boosted tree machine learning algorithm, we built a model that identifies 2408 children (1.32%) as at risk of foster care admission in a sample of 181 841, of whom 1599 entered foster care within 1 year, resulting in a positive predictive value (PPV) of 66.4% (F 1 = 55.5%, specificity = 99.5%, sensitivity = 47.67%), outperforming logistic regression. Accuracy was substantially better when using SDOH data (PPV of 84.72% with SDOH data compared to 27.44% without).
Conclusions:
These results highlight the importance of SDOH factors in predicting foster care admission. They also point to the potential of machine learning for facilitating early intervention to prevent foster care admissions.
Related Concept Videos
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
 01:07
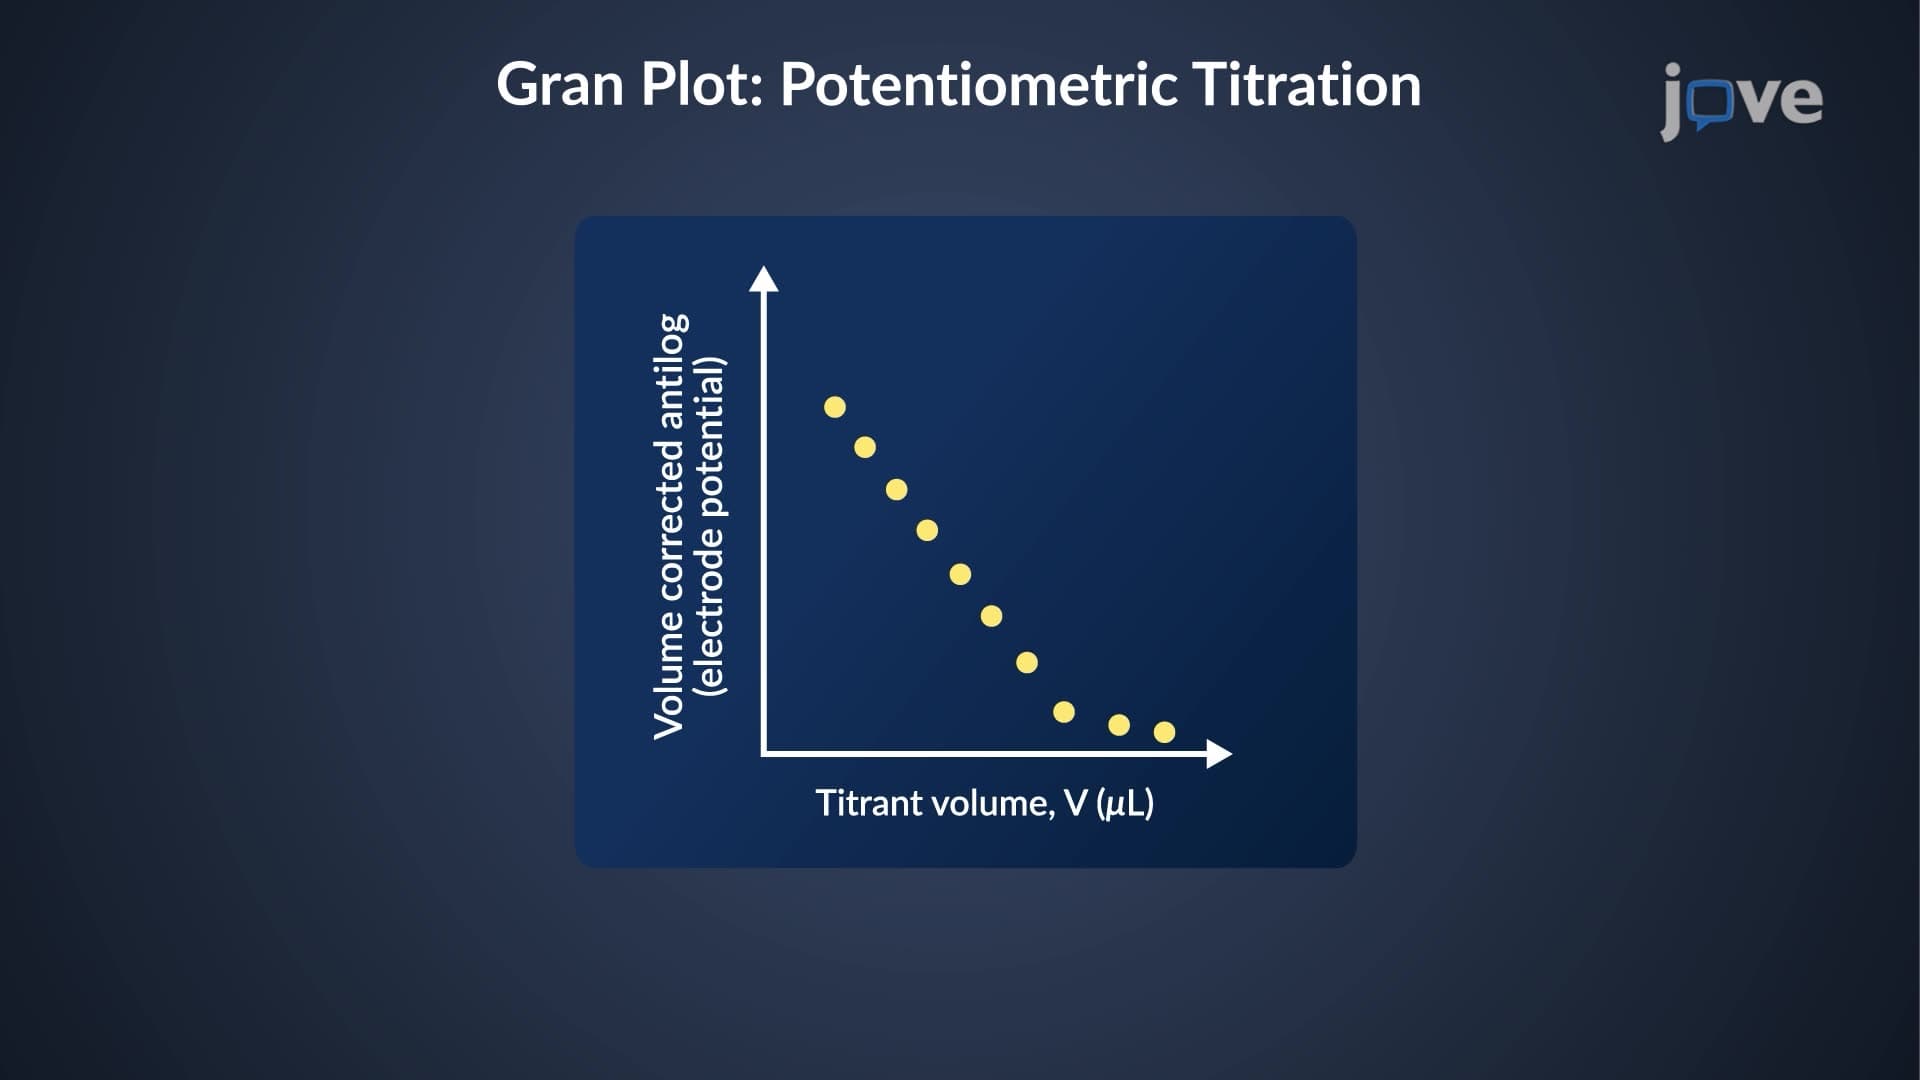
End Point Prediction: Gran Plot
For potentiometric titration, the Gran plot is created by plotting...
 02:24
Predicting Reaction Outcomes
 01:18
Steps in Outbreak Investigation
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:11
Regression Analysis
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as: