Related Experiment Video
Updated: Jan 10, 2026

Proton Transfer and Protein Conformation Dynamics in Photosensitive Proteins by Time-resolved Step-scan Fourier-transform Infrared Spectroscopy
Published on: June 27, 2014
SVE-Former: A fast fourier transformer via singular vector embedding
Xiang-Jun Shen1, Wenxiu Tian1, Yang Yang1
1School of Computer Science and Communication Engineering, Jiangsu University, Jiangsu University Campus, Zhenjiang, 212013, Jiangsu, China.

Abstract:
Self-attention is the cornerstone of transformers, yet its quadratic time and space complexity with respect to the input sequence length leads to high training costs. To mitigate this issue, various linear self-attention methods have been proposed. However, most of these methods overlook the fundamental linear relationships among tokens, limiting the model's ability to fully leverage self-attention for understanding inter-token dependencies. To address this limitation, we propose SVE-Former, a transformer variant that employs singular vector embedding to comprehensively capture dependencies among tokens. Specifically, we first perform singular value decomposition (SVD) on tokens to extract the underlying data subspace within the feature space. This allows us to compress the conventional attention mechanism into a more compact representation based on the token subspace, thereby significantly enhancing both the model's expressive power and computational efficiency. Furthermore, recognizing the high computational cost of singular value decomposition, we introduce a Fourier-domain singular value decomposition method. In this approach, Fourier singular vectors are obtained by selecting a stable subset from a large predefined bank of Fourier bases. Additionally, we estimate the stability of the selected Fourier subspace using Kullback-Leibler divergence, ensuring a robust representation of data distribution over time. By analyzing this stability, our method substantially reduces the required sample size for training, effectively minimizing redundant computations. In summary, our proposed approach enhances self-attention's capability for expressive feature extraction and critical information retention, thereby improving model performance and efficiency in processing long-range dependencies. Experimental results on several benchmark datasets, including QQP, SST-2, and IMDB, demonstrate that our method outperforms state-of-the-art linear attention mechanisms such as Cosformer and Linformer, achieving over a 10 % reduction in training time.
Related Concept Videos
 01:10
Fast Fourier Transform
The computational efficiency of the FFT becomes...
 01:07
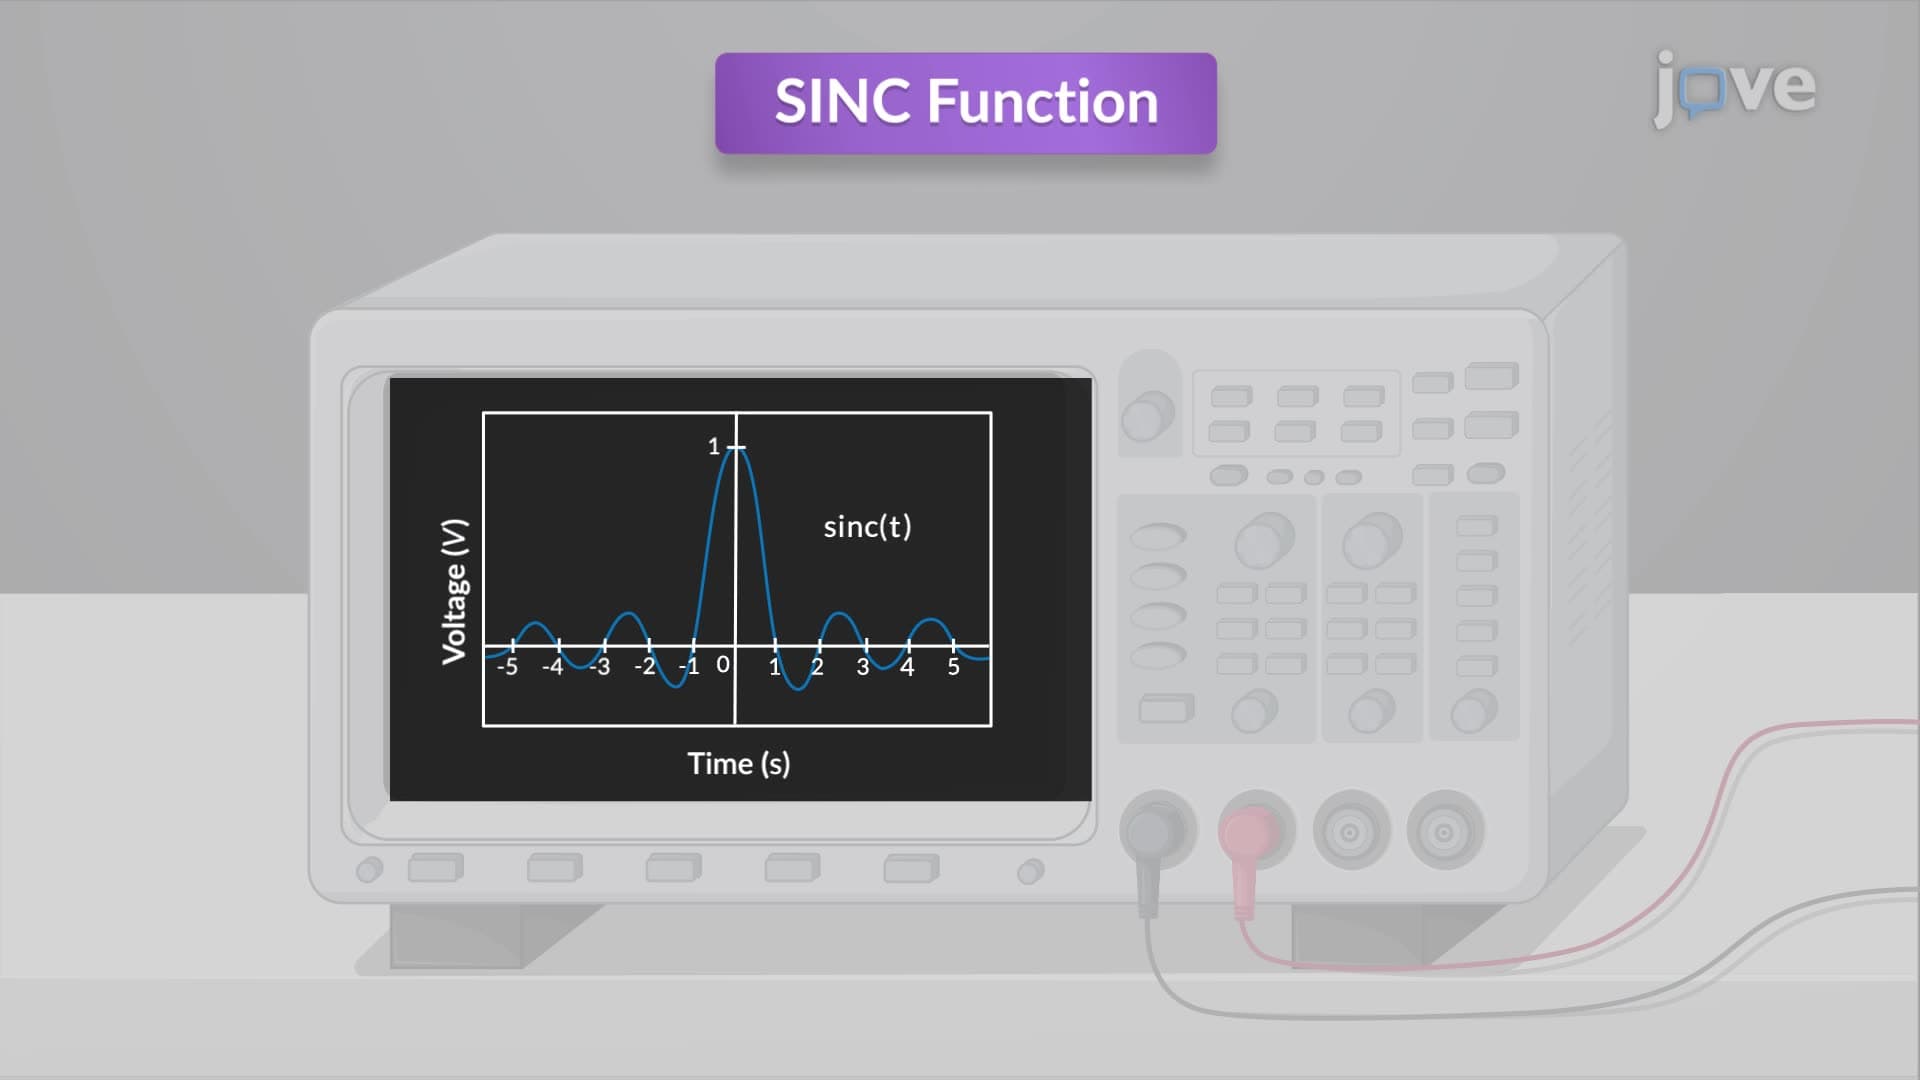
Basic signals of Fourier Transform
The sinc function, defined as sinc(x) = sin(πx)/(πx), is particularly notable for its symmetry and behavior at...
 01:26
Cartesian Form for Vector Formulation
 01:08
Vector Algebra: Method of Components
In many applications, the magnitudes and directions of...
 01:15
Discrete Fourier Transform
 01:15
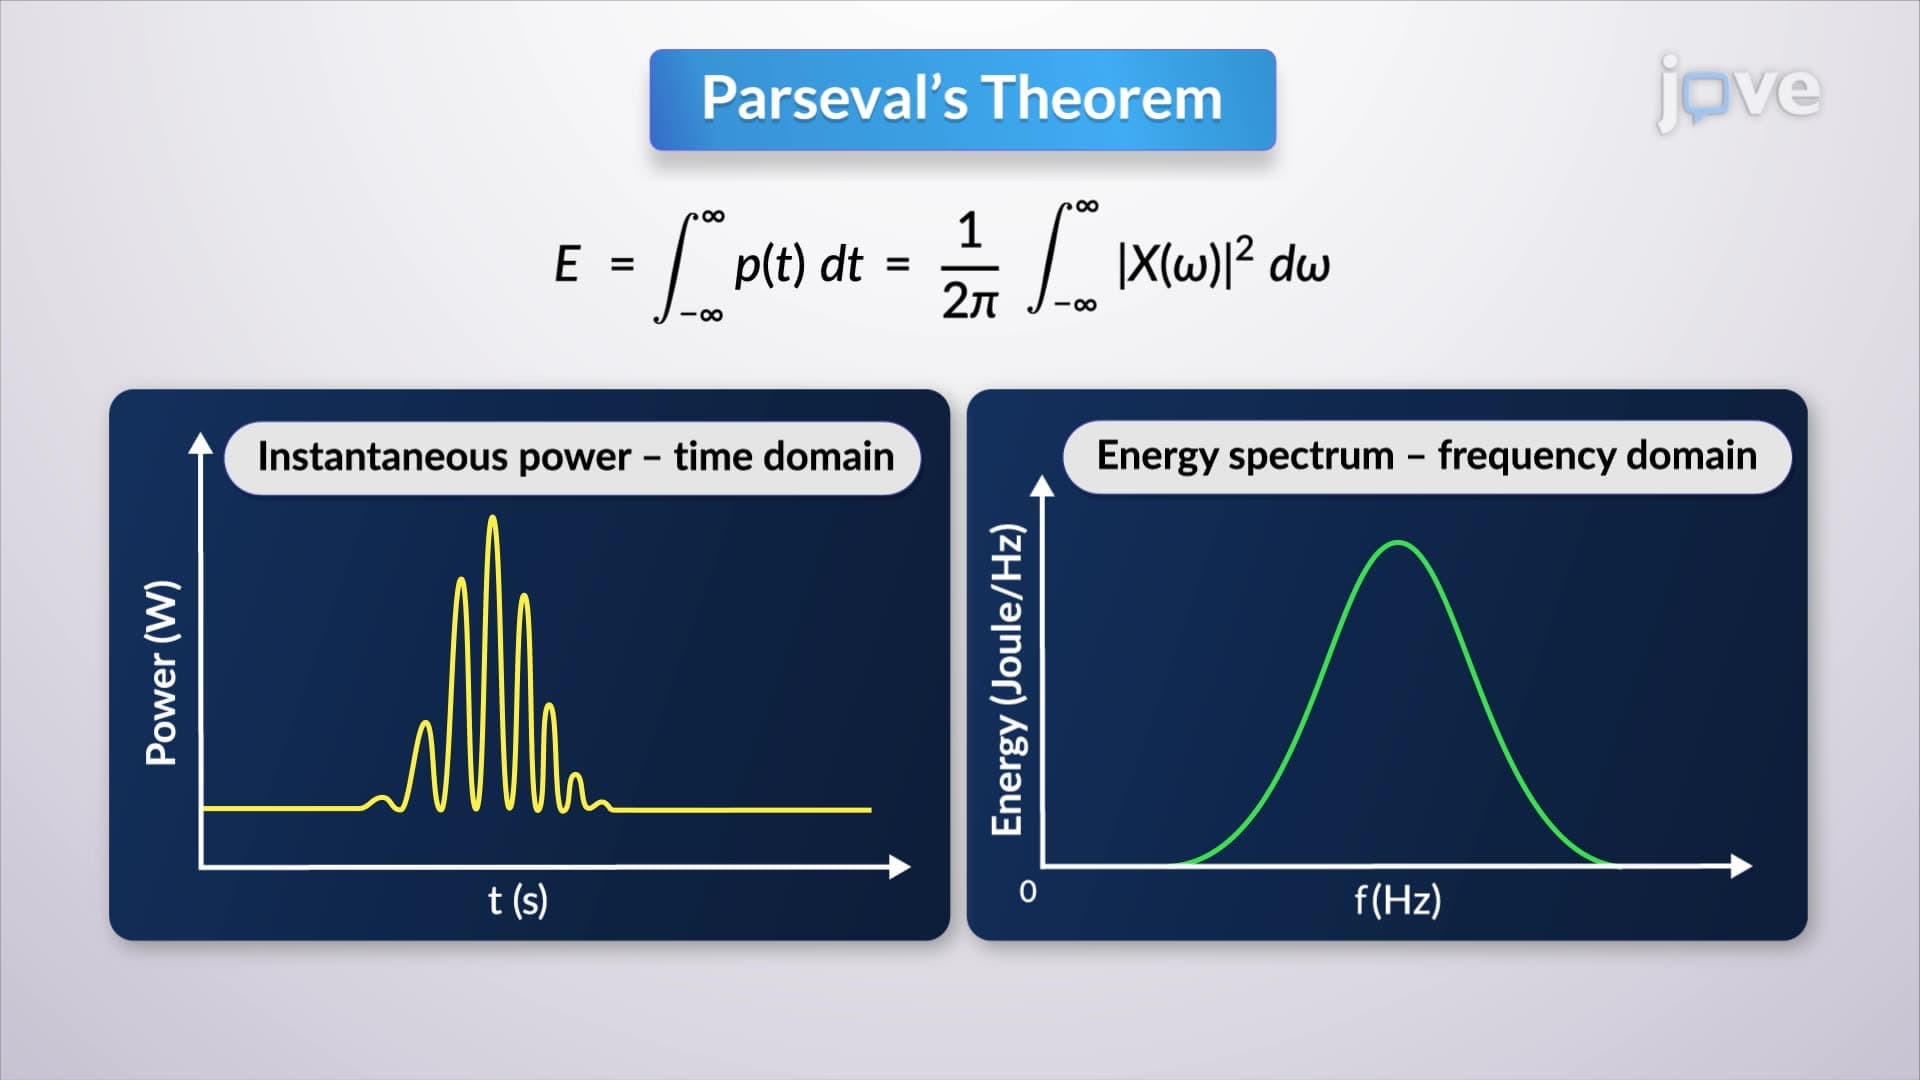
Parseval's Theorem for Fourier transform
To understand Parseval's theorem, it is essential to first comprehend how signal energy is typically calculated. When considering a...