Related Experiment Video
Updated: Jan 7, 2026
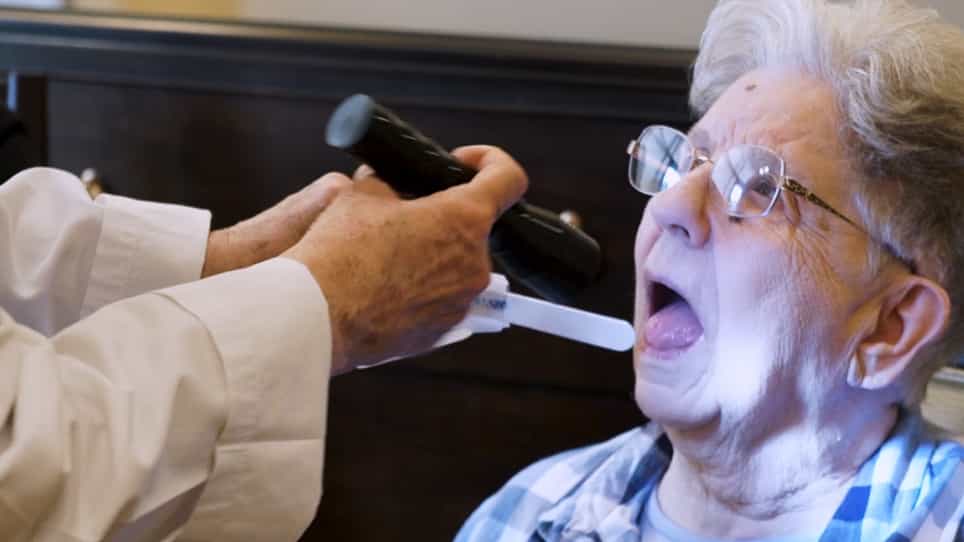

Oral Health Assessment by Lay Personnel for Older Adults
Published on: February 2, 2020
Performance of large language models in reporting oral health concerns and side effects in head and neck cancer: a
Jonas Rast1, Susanne Wiegand1, Jana Biermann2
1Department of Otorhinolaryngology, Head and Neck Surgery, University Hospital Schleswig-Holstein, Arnold-Heller-Straße 3, 24105, Kiel, Germany.

Purpose:
With increasing reliance on large language models (LLMs) for health information, this study evaluated reliability and quality, understandability, actionability, readability and misinformation risk of responses from LLMs to oral health concerns and oral side effects in head and neck cancer (HNC) patients.
Methods:
Frequently asked questions on oral health and HNC therapy side effects were identified via ChatGPT-GPT-4-turbo and Gemini-2.5 Flash, then submitted to eight LLMs (ChatGPT-GPT-4-turbo, Gemini-2.5 Flash, Microsoft Copilot, Perplexity, Chatsonic, Mistral, Meta AI-Llama 4, DeepSeek-R1). Responses were assessed using DISCERN and modified DISCERN instruments (reliability and quality), Patient Education Materials Assessment Tool (PEMAT [understandability and actionability]), Flesch-Reading-Ease-Score (FRES [readability]), misinformation score, citations, and wordcounts. Statistical analysis was done by Scheirer-Ray-Hare-test followed by Dunn's post-hoc-tests and Bonferroni-Holm correction (p < 0.05).
Results:
A total of 40 questions belonging to 12 oral health-related categories were identified. Statistically significant differences between LLMs were found for DISCERN, modified DISCERN, PEMAT-understandability, PEMAT-actionability, FRES, and word counts (p < 0.001). Median DISCERN and modified DISCERN scores amounted from 47.0 (ChatGPT-GPT-4-turbo) to 59.0 (Perplexity, Chatsonic) and from 2.0 (Gemini-2.5 Flash, Mistral) to 5.0 (Perplexity) indicating good to fair reliability. LLMs were understandable (median PEMAT-understandability scores ≥ 75.0), but provided limited specific guidance (median PEMAT-actionability scores ≤ 40) and used complex language (median FRES ≤ 40.2). Misinformation risk was generally low and not statistically significant among LLMs (p = 0.768).
Conclusion:
Despite a low overall misinformation risk, deficits in actionability highlight the need for cautious integration of LLMs into HNC patient education.
Related Concept Videos
 02:43
Mouse Models of Cancer Study
The development of transgenic, knockout, and knock-in mice has led to an exponential increase in their use as model organisms in research,...
 01:21
Cancer Survival Analysis