Related Experiment Video
Updated: Jan 13, 2026


Augmenting Large Language Models via Vector Embeddings to Improve Domain-Specific Responsiveness
Published on: December 6, 2024
Drug-drug interaction identification using large language models
Kaitlin Blotske1, Xingmeng Zhao1, Kelli Henry1
1University of Colorado School of Medicine, Department of Biomedical Informatics.

Background:
Drug-drug interactions (DDIs) are a significant source of morbidity and adverse drug events (ADEs), particularly in situations of polypharmacy and complex medication regimens. While rules-based software integrated in electronic health records (EHRs) has demonstrated proficiency in identifying DDIs present in medication regimens, large language model (LLM) based identification requires thorough benchmarking and performance evaluation using high-quality datasets for safe use. The purpose of this study was to develop a series of performance benchmarking experiments specifically for LLM performance in identification and management of DDIs using a specifically curated clinician-annotated dataset of clinically-relevant DDIs.
Methods:
We evaluated three LLMs (GPT-4o-mini, MedGemma-27B, LLaMA3-70B) using a clinician-annotated benchmark dataset of 750 DDI scenarios spanning three levels of diagnostic complexity. Tasks were aligned with flexible judgment formats: (1) a pointwise two-drug classification task, (2) a pairwise three-drug discrimination task, and (3) a listwise 4-6 drug selection task. Standardized zero-shot prompting with task-specific instructions was applied for all models. Performance was assessed using precision, recall, F1 score, and accuracy. Reliability was quantified using self-consistency across repeated runs and confidence-aligned metrics to capture stability in model reasoning.
Results:
Across the three experiments, model performance varied by task structure and interaction severity. LLaMA3-70B demonstrated the highest recall and F1 score in the pointwise task, whereas GPT-4o-mini achieved superior accuracy and consistency in the pairwise and listwise tasks. MedGemma-27B showed competitive performance in identifying Category D interactions. Self-consistency decreased as task complexity increased, highlighting reduced stability in multi-drug reasoning. No model exhibited uniformly high reliability across all judgment formats.
Conclusions:
Current LLMs show promising but uneven capabilities in identifying DDIs across clinically relevant task structures. Performance degrades as the reasoning space expands, and stability across repeated queries remains limited. These findings emphasize the need for multi-format evaluation frameworks and reliability-aware assessment when considering LLMs for medication-safety applications.
More Related Videos
 07:40
A Data Integration Workflow to Identify Drug Combinations Targeting Synthetic Lethal Interactions
Published on: May 27, 2021
 05:47
Evidence-based Knowledge Synthesis and Hypothesis Validation: Navigating Biomedical Knowledge Bases via Explainable AI and Agentic Systems
Published on: June 13, 2025
Related Concept Videos
 01:28
Drug-Receptor Interaction: Antagonist
Antagonists can be classified as competitive or noncompetitive based on their...
 01:29
Drug-Receptor Interactions
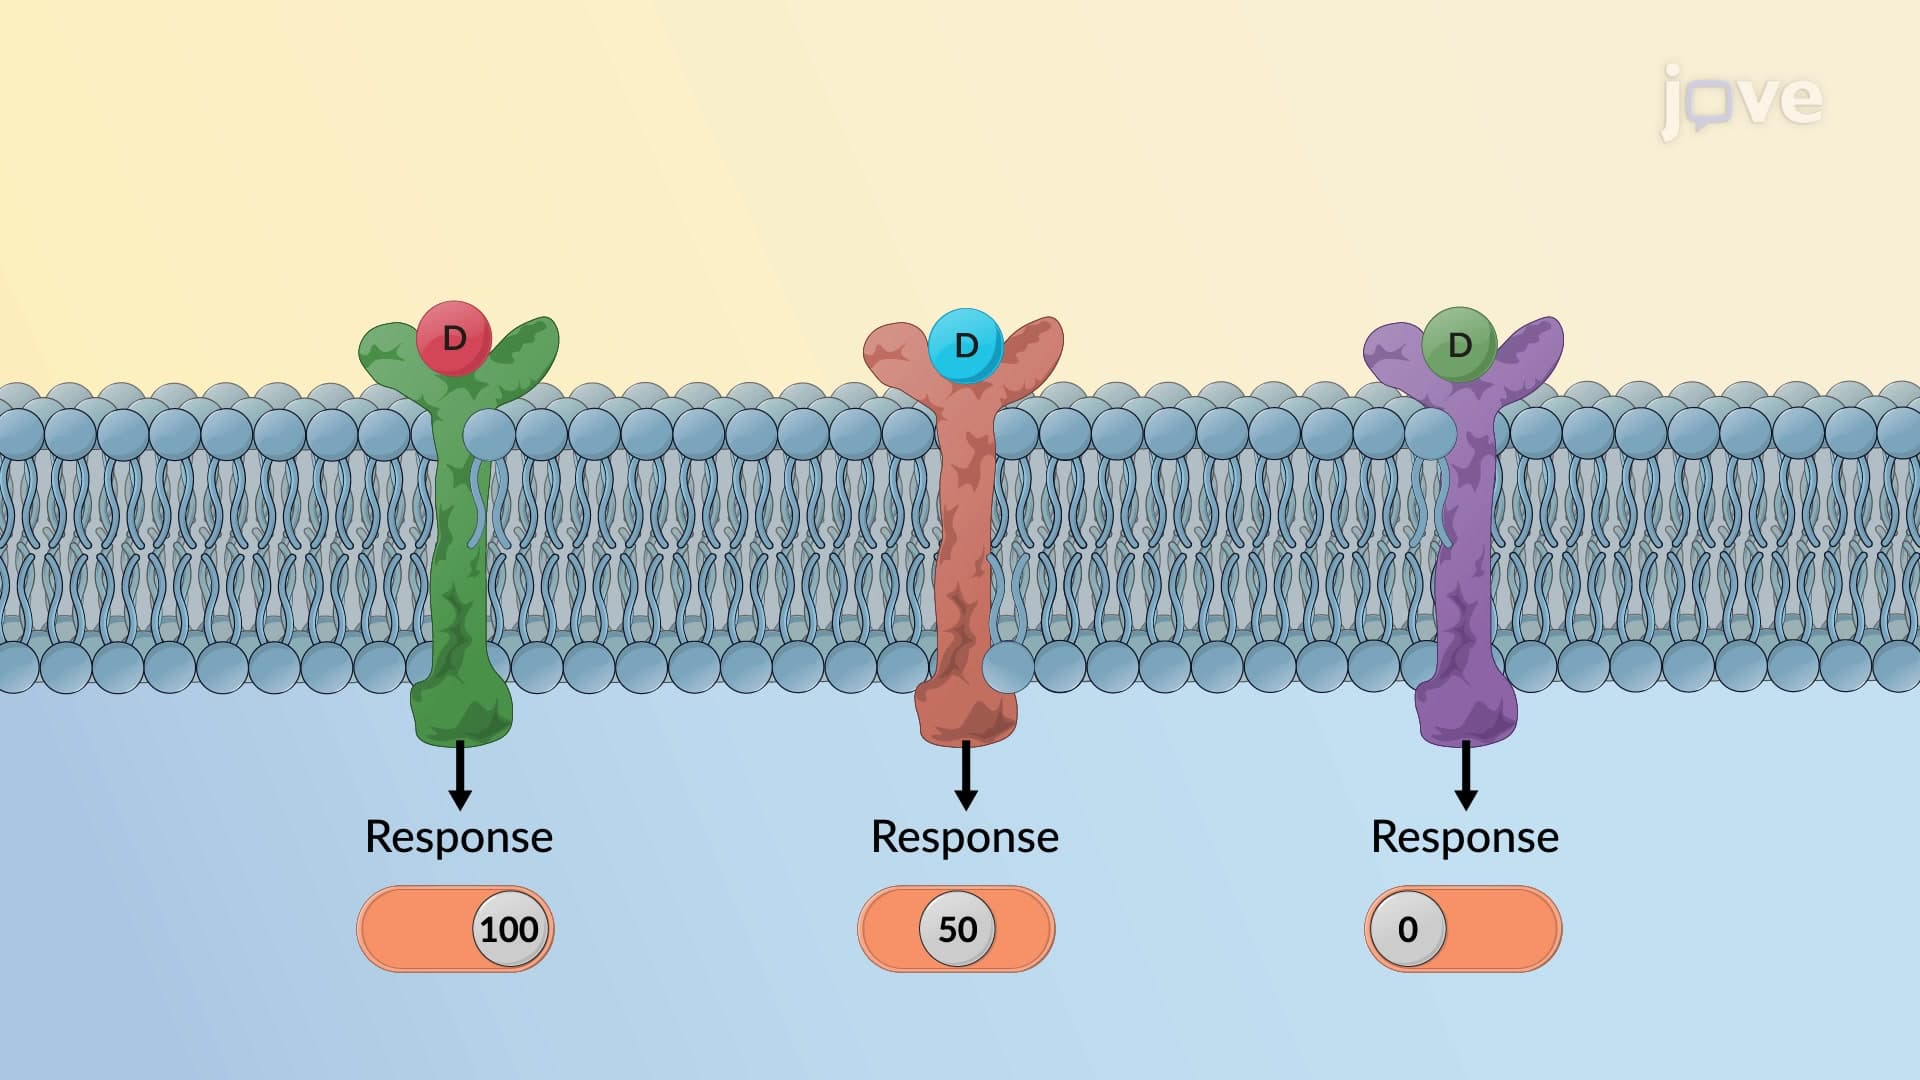
Several parameters, such as the drug's affinity for its receptor and its efficacy, which is its ability to activate the receptor, determine the drug's effect on the tissue....
 01:26
Drug Discovery: Overview
 01:25
Drug-Receptor Interaction: Agonist
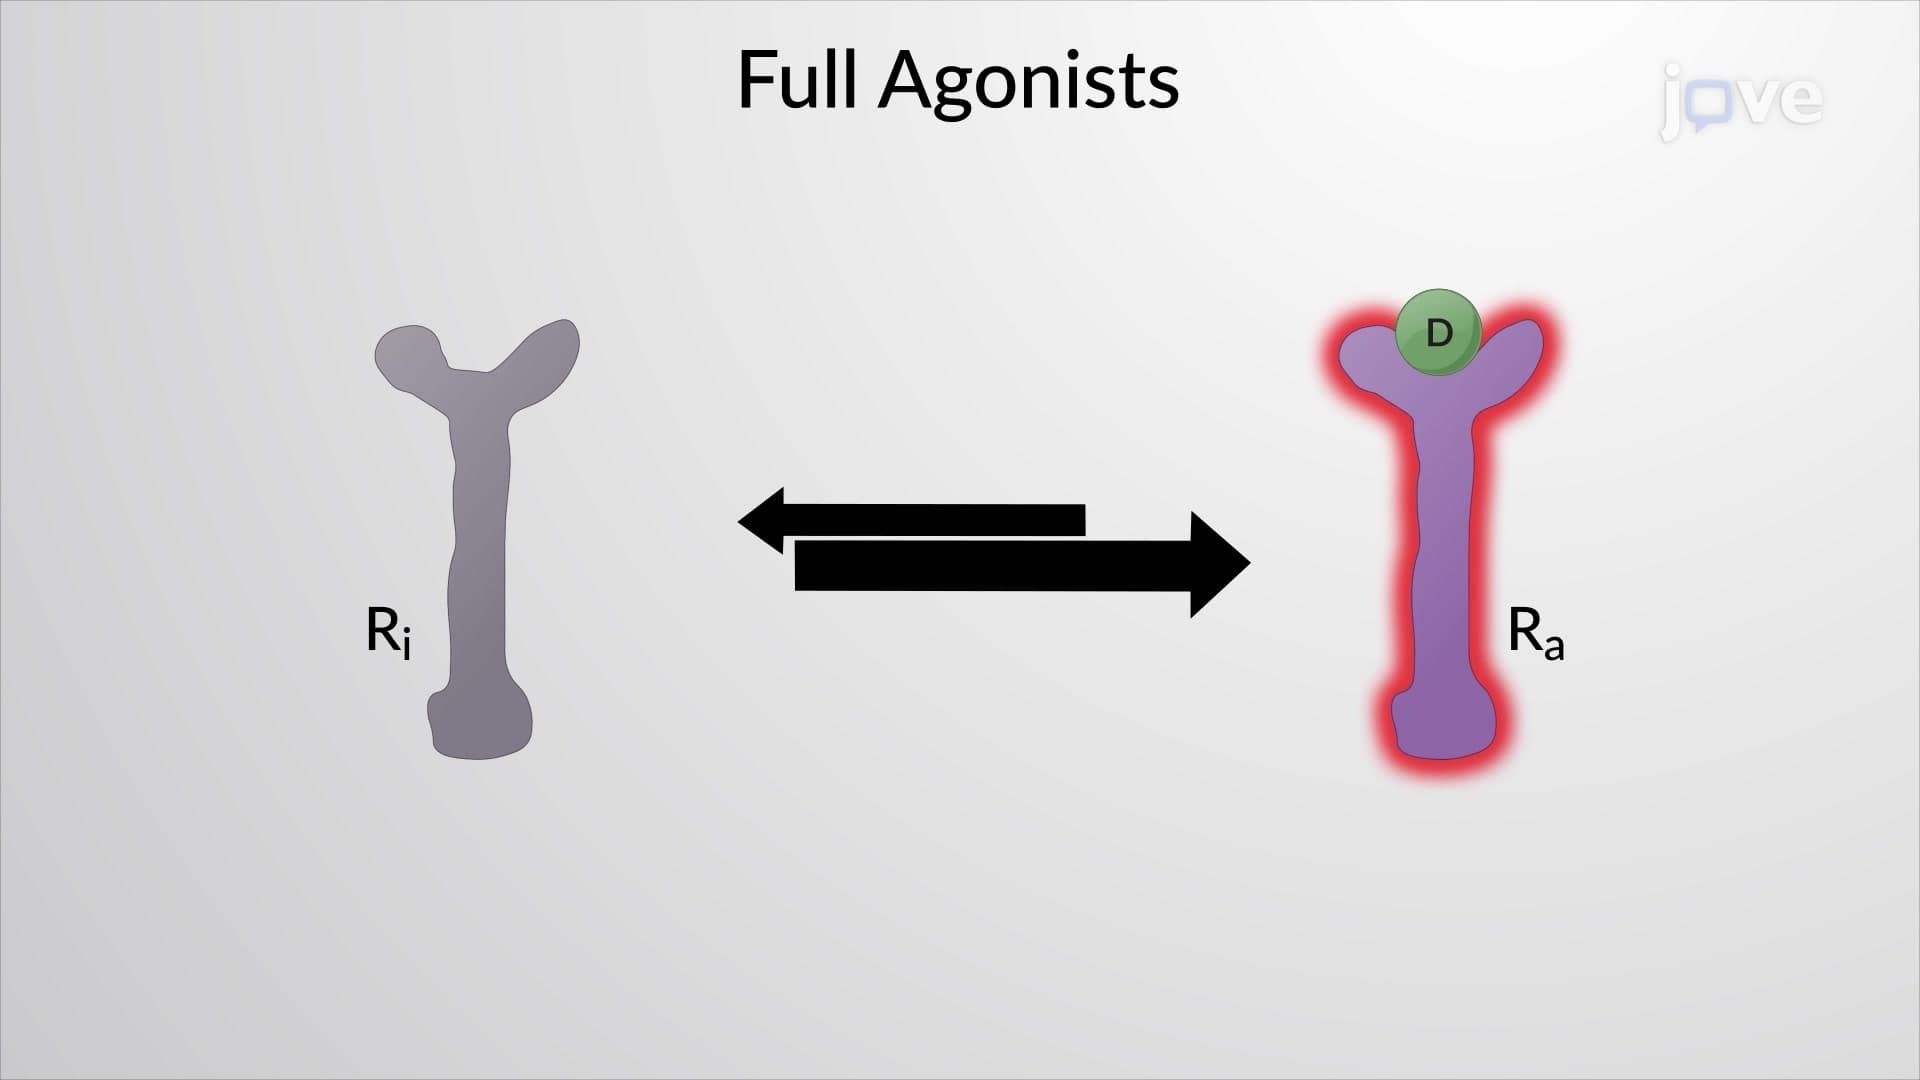
Agonists can bind to receptors in different ways. Some agonists bind directly to the receptor's active site, mimicking the endogenous...
 01:30
Quantitative Aspects of Drug-Receptor Interaction
 01:26
Pharmacokinetic Models: Comparison and Selection Criterion
Physiological models take a detailed approach by considering specific molecular processes. They can predict drug distribution, metabolism, and elimination changes, providing a comprehensive understanding of how drugs interact with the body.