Related Experiment Video
Updated: Jan 22, 2026

Constructing and Visualizing Models using Mime-based Machine-learning Framework
Published on: July 22, 2025
Exploring the association between complete blood cell count-derived inflammatory biomarkers and cancer incidence
Sijun Zhao1, Ping Fu1, Liangqing Lin1
1Department of Traumatology, Jiangxi Provincial People's Hospital, The First Affiliated Hospital of Nanchang Medical College, Nanchang, Jiangxi Province, China.

Abstract:
This study utilized interpretable machine learning approaches to investigate associations between complete blood cell count (CBC)-derived inflammatory parameters and cancer occurrence. Data from 35,591 National Health and Nutrition Examination Survey participants collected between 1999 and 2016 were analyzed. Four CBC-derived inflammatory biomarkers were examined: systemic immune-inflammation index (SIRI), neutrophil-to-lymphocyte ratio (NLR), monocyte-to-lymphocyte ratio (MLR), and neutrophil-monocyte-lymphocyte ratio (NMLR). The analytical framework incorporated weighted multivariable logistic regression, restricted cubic spline modeling, threshold effect evaluation, and subgroup analyses. Machine learning assessment utilized 8 different algorithms, with the Boruta method for feature selection and Shapley additive explanations (SHAP) methodology for enhancing model interpretability. Participants with cancer exhibited significantly elevated levels of all inflammatory markers in comparison to control subjects. Multivariable logistic regression revealed that participants in the highest quartile demonstrated significantly increased cancer risk relative to the lowest quartile: SIRI (OR = 1.32, P = .023), NLR (OR = 1.38, P = .002), MLR (OR = 1.26, P = .041), and NMLR (OR = 1.44, P = .001). Each biomarker exhibited significant positive dose-response trends (all P ≤ .05). Restricted cubic spline analyses highlighted nonlinear associations with inflection points appearing at 2.084, 4.308, 0.145, and 4.739 for SIRI, NLR, MLR, and NMLR, respectively. The random forest model demonstrated optimal performance (AUC = 0.765), with SHAP analysis pinpointing age as the strongest predictor, followed by MLR, lymphocyte count, and NMLR. CBC-derived inflammatory biomarkers show notable nonlinear associations with cancer prevalence. Machine learning models that are interpretable reveal complex relationships that extend beyond traditional statistical methods, indicating that these readily available biomarkers could improve cancer risk stratification and early detection strategies.
More Related Videos
 07:13
Comparison of Predictive Performance of Three Lymph Node Staging Systems in Colorectal Signet Ring Cell Carcinoma Based on Machine Learning Model
Published on: April 18, 2025
 06:22
Machine Learning-Based Cough Tone Classification: Diagnostic Exploration of Chronic Obstructive Pulmonary Disease and Respiratory Tract Infections
Published on: September 19, 2025
Related Concept Videos
 01:27
Associative Learning
Classical conditioning, also known...
 01:20
Blood Studies for Cardiovascular System I: Cardiac Biomarkers
The essential diagnostic tools for detecting myocardial necrosis and monitoring individuals suspected of having acute coronary syndrome (ACS) include:
Troponins
Troponins, particularly cardiac troponins I and T, are the most precise and sensitive markers of myocardial injury. They are detectable within 4-6 hours of myocardial injury and remain...
 01:08
Prevalence and Incidence
Prevalence indicates the proportion of individuals in a population who have a specific disease or health...
 02:43
Mouse Models of Cancer Study
The development of transgenic, knockout, and knock-in mice has led to an exponential increase in their use as model organisms in research,...
 01:11
Genome-wide Association Studies-GWAS
GWAS does not require the identification of the target gene involved in...
 01:30
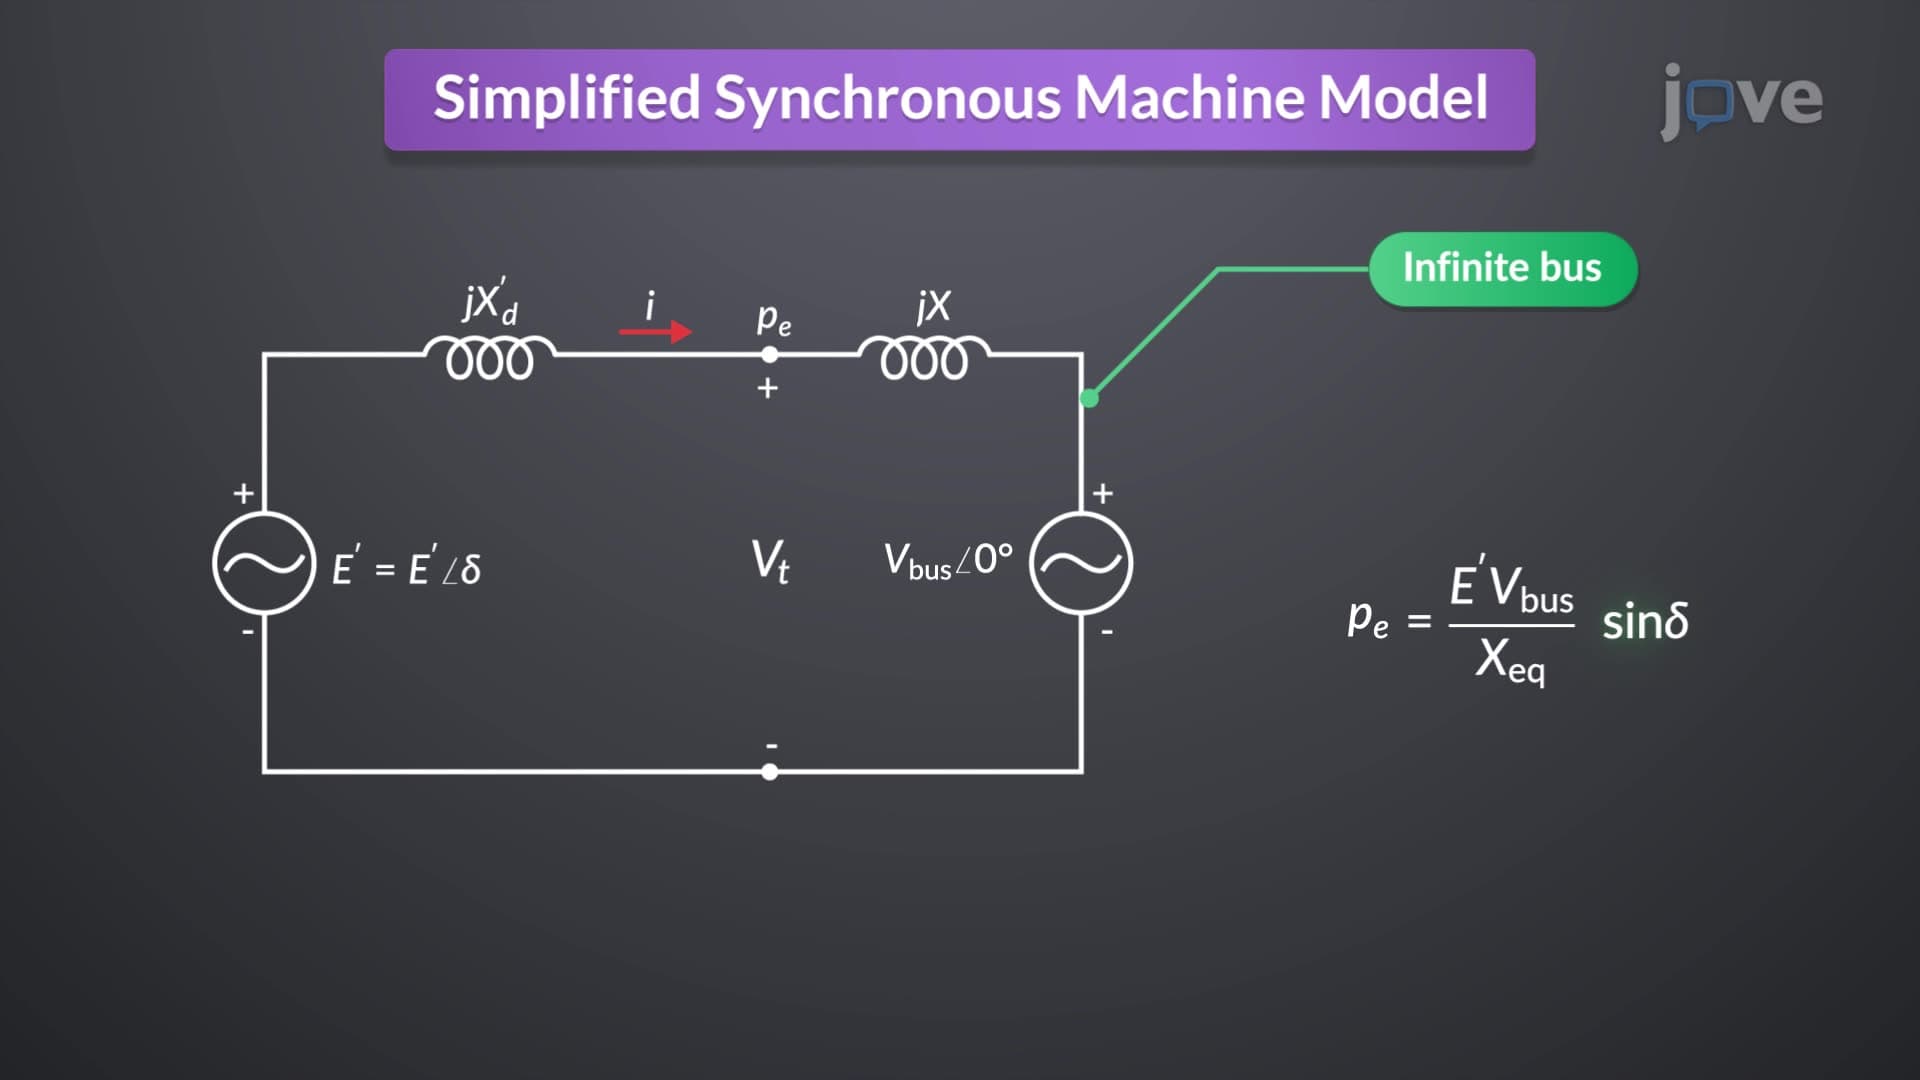
Simplified Synchronous Machine Model
In this model, each generator is connected to a...