Related Experiment Video
Updated: Feb 4, 2026
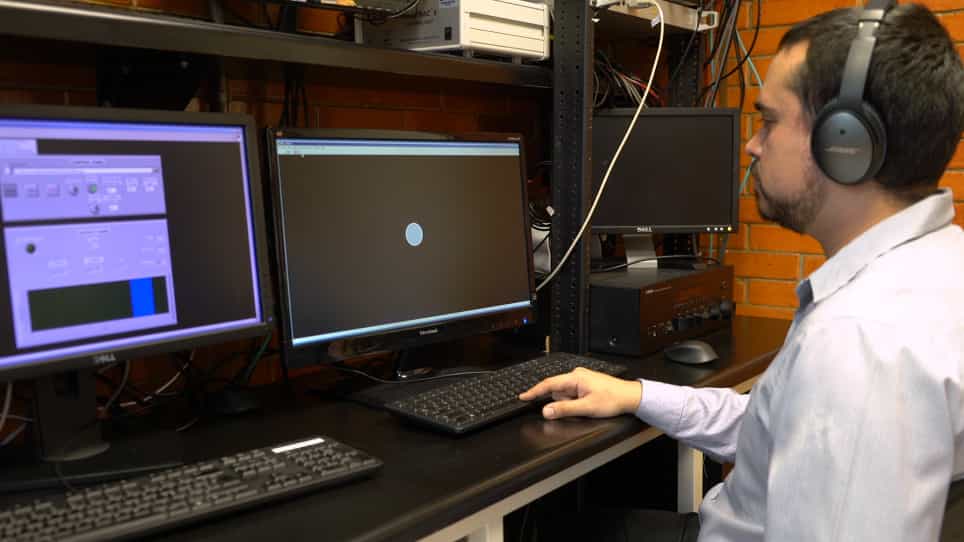

A Two-interval Forced-choice Task for Multisensory Comparisons
Published on: November 9, 2018
Human-anchored longitudinal comparison of generative AI with a bias-calibrated LLM-as-judge
1SUNY Empire State University, New York, United States of America.

Abstract:
Service LLMs evolve without public changelogs, complicating reproducible evaluation. We present a preregistered human-anchored longitudinal study that tracks three major model families over ten weekly waves using a fixed prompt bank (N = 240) across six domains. Blinded human raters provided correctness judgments, and a bias-calibrated LLM-as-judge produced secondary pairwise preferences corrected weekly via a Bradley-Terry model. Mixed-effects modeling and change-point detection (PELT with MBIC penalty) identified significant service drift patterns. Results show divergent stability trajectories among models: one stable, one improving, and one degrading mid-study. Judge calibration increased agreement with humans (τ = 0.59-0.68) while reducing volatility. Safety metrics co-varied with drift events, suggesting behavioral shifts rather than confirmed causal changes. All data, prompts, rubrics, and parameter configurations are provided in supporting files S1-S6.
Related Concept Videos
 01:25
The Anchoring-and-Adjustment Heuristic
 02:20
Longitudinal Research
 01:31
Confirmation Biases
 01:12
Hindsight Biases
 01:22
Bias
In statistics, a sampling bias is created when a sample is collected from a population, and some members of the population are not as likely to be chosen as others (remember, each member...
 01:03
Anchoring Junctions