
A comparative study of ChatGPT 4o and DeepSeek in addressing CIED infection-related questions: Accuracy and
Chang Yu1, Jianhua Fan2, Yu Chen1
1Department of Infection Management, Kunshan Integrated Traditional Chinese and Western Medicine Hospital, Suzhou, Jiangsu, China.

Abstract:
This study aimed to compare the effectiveness of 2 artificial intelligence (AI) models, ChatGPT 4o and DeepSeek, in responding to questions about infections associated with cardiovascular implantable electronic devices (CIED). The focus was on evaluating their accuracy and readability, which are critical for their use in clinical settings. A comparative analysis was conducted using 30 questions based on American Heart Association's guidelines for CIED-related infections. Each question was asked to both AI models under 2 conditions: once without additional context and once with guideline-based prompts. Accuracy was assessed using a 4-level grading scale by 2 cardiovascular experts. Readability was measured using the Flesch-Kincaid Grade score and word-count metrics. Without guideline prompts, ChatGPT 4o provided comprehensive answers for 24 out of 30 questions (80.00%), with 5 correct but incomplete answers (16.67%) and one partially correct answer (3.33%). DeepSeek also provided comprehensive answers for 24 questions (80.00%) but had 6 correct but incomplete answers (20.00%). With guideline prompts, ChatGPT 4o's comprehensive answer rate increased to 93.33% (28/30), while DeepSeek's rate rose to 90.00% (27/30). No significant difference in overall accuracy was found (P = .34). In terms of readability, ChatGPT 4o had a higher word count (859.10 ± 235.90) compared to DeepSeek (526.27 ± 100.45), with a statistically significant difference (P <.01). The Flesch-Kincaid Grade Score for ChatGPT 4o (15.40 ± 1.18) was higher than that of DeepSeek's (13.91 ± 1.42), indicating more complex responses (P <.01). With guidelines, both models showed reduced verbosity, with ChatGPT 4o's word-count dropping to (624.00 ± 249.01) and DeepSeek's to (549.43 ± 117.40); however, this change was not statistically significant (P = .13). Similarly, slight improvements in readability with guidelines were observed for both models, but these were not statistically significant (P = .11). Both AI models demonstrated the ability to provide accurate and clinically relevant information for managing CIED infections. The use of guideline-based prompts significantly improved the completeness of their responses. ChatGPT 4o provided more detailed answers, while DeepSeek produced more concise, potentially easier-to-understand outputs.
Related Concept Videos
 01:25
Strategies for Assessing and Addressing Confounding
Confounding can be addressed at both the design phase of a study and through analytical methods after data...
 03:37
Uncertainty in Measurement: Accuracy and Precision
 02:07
Improving Translational Accuracy
02:07Improving Translational Accuracy
 01:52
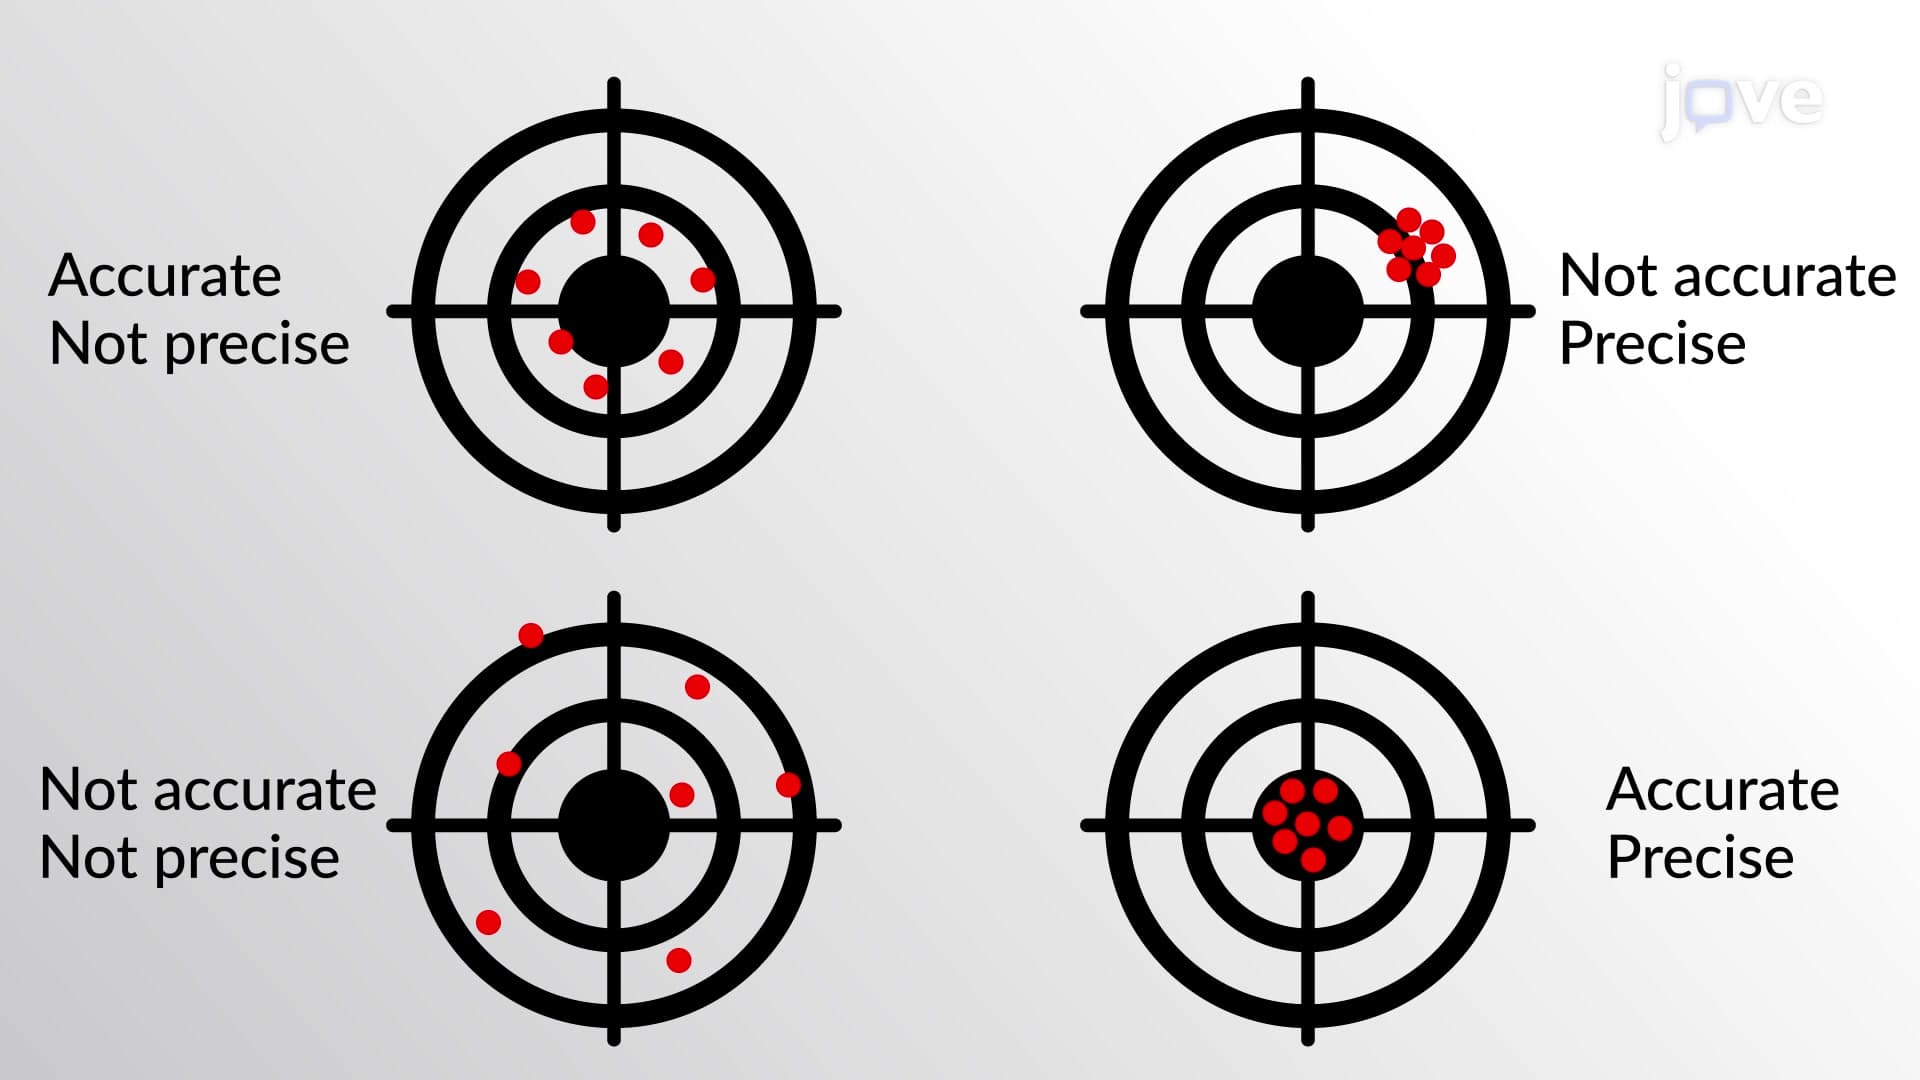
Accuracy and Precision
 01:28
Accuracy, limits, and approximation
Accuracy is defined as the closeness of the measured value to the true or actual value. In engineering mechanics, repeated measurements are taken during theoretical or experimental analyses to ensure that the result is precise and accurate.
The accuracy of any solution is based on the...