Related Experiment Video
Updated: Feb 5, 2026

Area-based Image Analysis Algorithm for Quantification of Macrophage-fibroblast Cocultures
Published on: February 15, 2022
Performance evaluation of GPU-based parallel sorting algorithms
Mohammed Alaa Ala'anzy1, Nurdaulet Tolendi1, Baizhan Baubek1
1Department of Computer Science, SDU University, Kaskelen, Kazakhstan.

Abstract:
Sorting can be approached in two main ways: sequentially and in parallel. In sequential sorting, data is processed in a single-threaded manner, which can be slow for large datasets. However, parallel sorting divides the task across multiple processing units, enabling faster results by processing data simultaneously. Furthermore, Compute Unified Device Architecture (CUDA) technology enables developers to leverage GPU power for general-purpose parallel computing, significantly accelerating tasks like sorting. This paper investigates the GPU-based parallelization of merge sort (MS), quick sort (QS), bubble sort (BS), radix top-k selection sort (RS), and slow sort (SS) presenting optimized algorithms designed for efficient sorting of large datasets using modern GPUs. The primary objective is to evaluate the performance of these algorithms on GPUs utilizing CUDA, with a focus on analyzing both parallel time complexity and space complexity across various data types. Experiments are conducted on four dataset scenarios: randomly generated data, reverse-sorted data, already-sorted data, and nearly-sorted data. Also, the performance of GPU-accelerated implementations is compared with their sequential counterparts to assess improvements in computational efficiency and scalability. Earlier GPU-based generations of this type typically achieved acceleration rates between 2× and 9× over scalar CPU code. With newer GPU enhancements, including parallel-aware primitives and radix- or merge-optimized operations, acceleration rates have seen significant improvement. Our experiments indicate that Radix Sort based on GPUs achieves a significant speedup of approximately 50× (sequential: 240.8 ms, parallel: 4.83 ms) on 10 million random sort elements. Quick Sort and Merge Sort have 97× and 103× speedups, respectively (Quick: 1461.97 ms vs. 15.1 ms; Merge: 2212.33 ms vs. 21.4 ms). Bubble Sort, while significantly improving in parallel (123,321.9 ms to 7377.8 ms for an ≈17× improvement), is considerably worse overall. Slow Sort demonstrates a moderate but consistent acceleration, reducing execution time from 74.07 ms in the sequential version to 3.99 ms on the GPU, yielding an ≈18.6× speedup. These experimental findings confirm that the new single-GPU implementations can get speedups ranging from 17× to over 100×, surpassing the typical gains reported in previous generations and comparable to or over rates of acceleration reported for cutting-edge parallel sorting algorithms in recent studies.
More Related Videos
 09:52
Setting Up a Stroke Team Algorithm and Conducting Simulation-based Training in the Emergency Department - A Practical Guide
Published on: January 15, 2017
 09:01
A Method for Investigating Age-related Differences in the Functional Connectivity of Cognitive Control Networks Associated with Dimensional Change Card Sort Performance
Published on: May 7, 2014
Related Concept Videos
 01:23
Parallel Resonance
 01:20
Parallel Processing
 01:12
Trial and Error and Algorithm
 01:23
Resistors In Parallel
 01:14
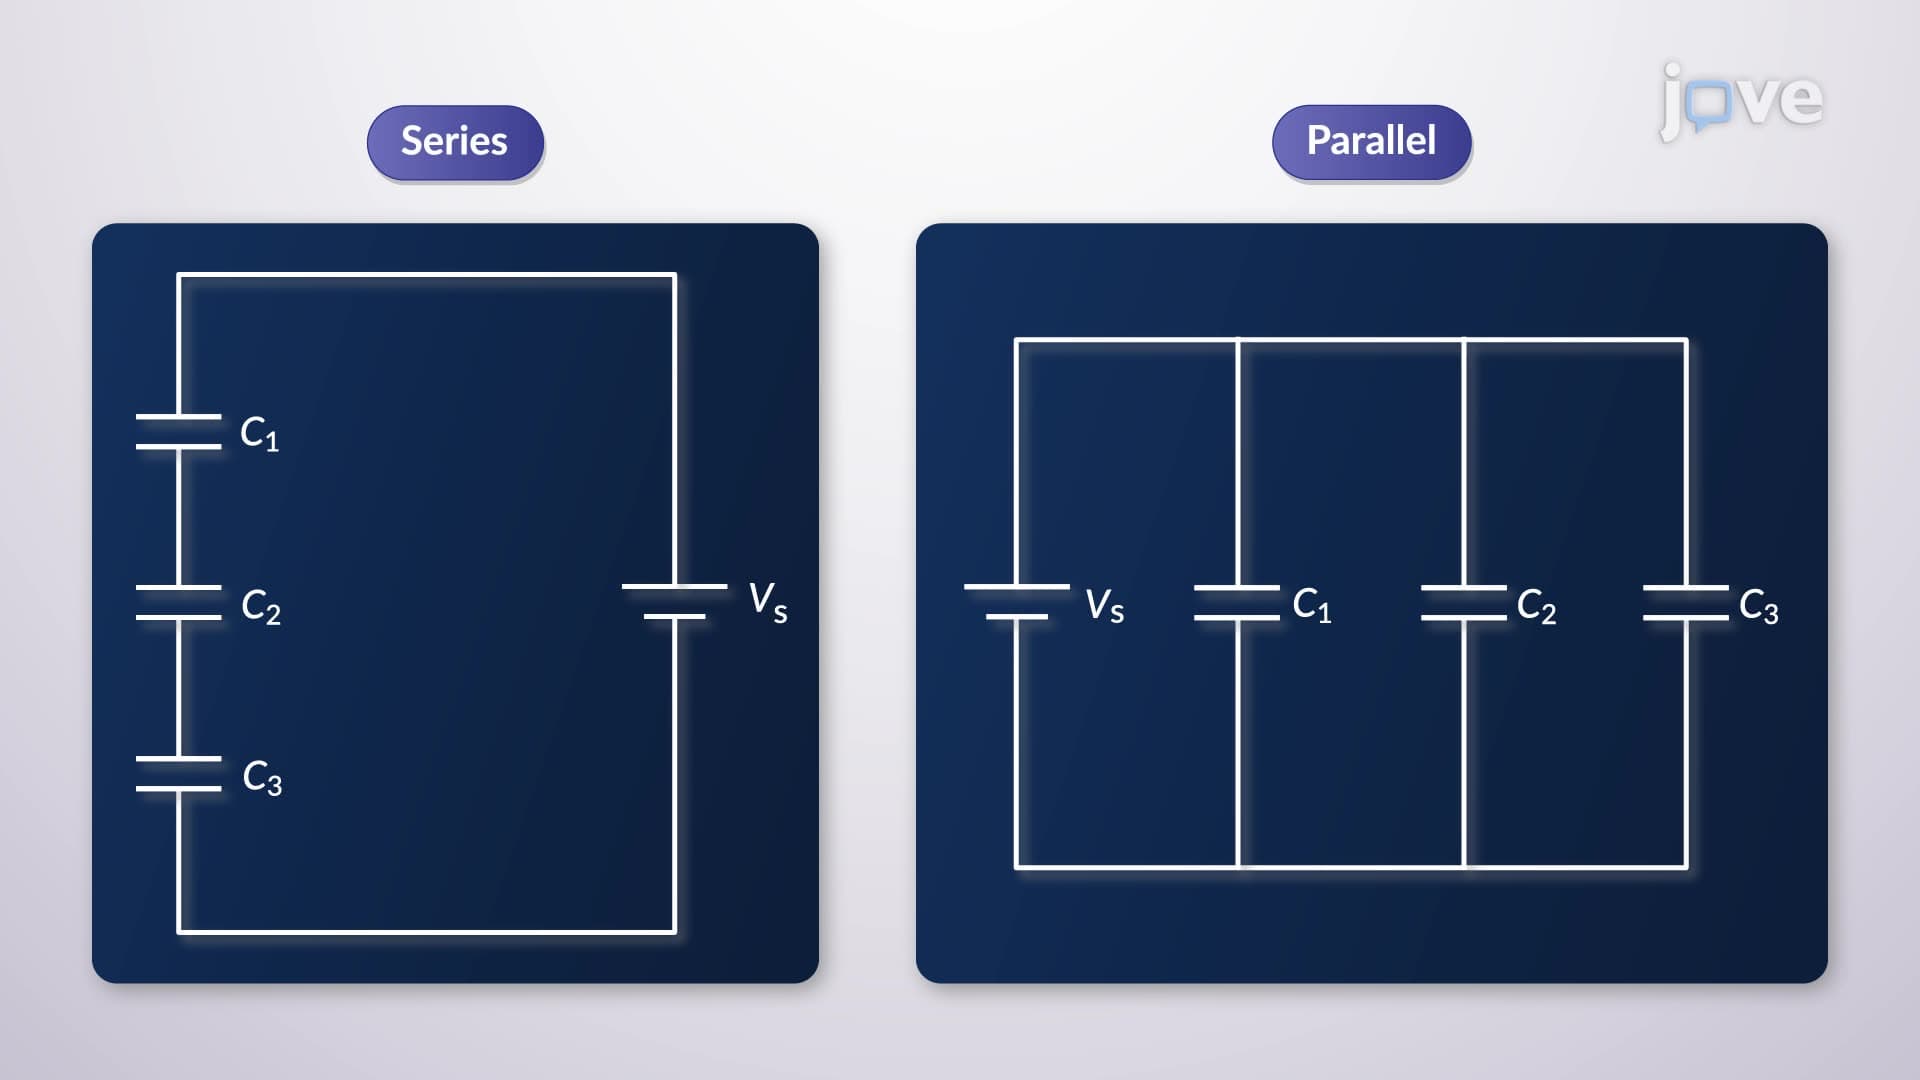
Series and Parallel Capacitors
First, consider capacitors connected in series to a battery. In this configuration, the plate connected to the battery's positive terminal develops a positive charge, while the plate attached to the negative terminal becomes negatively charged. An equal magnitude of charge is induced on the...
 01:06
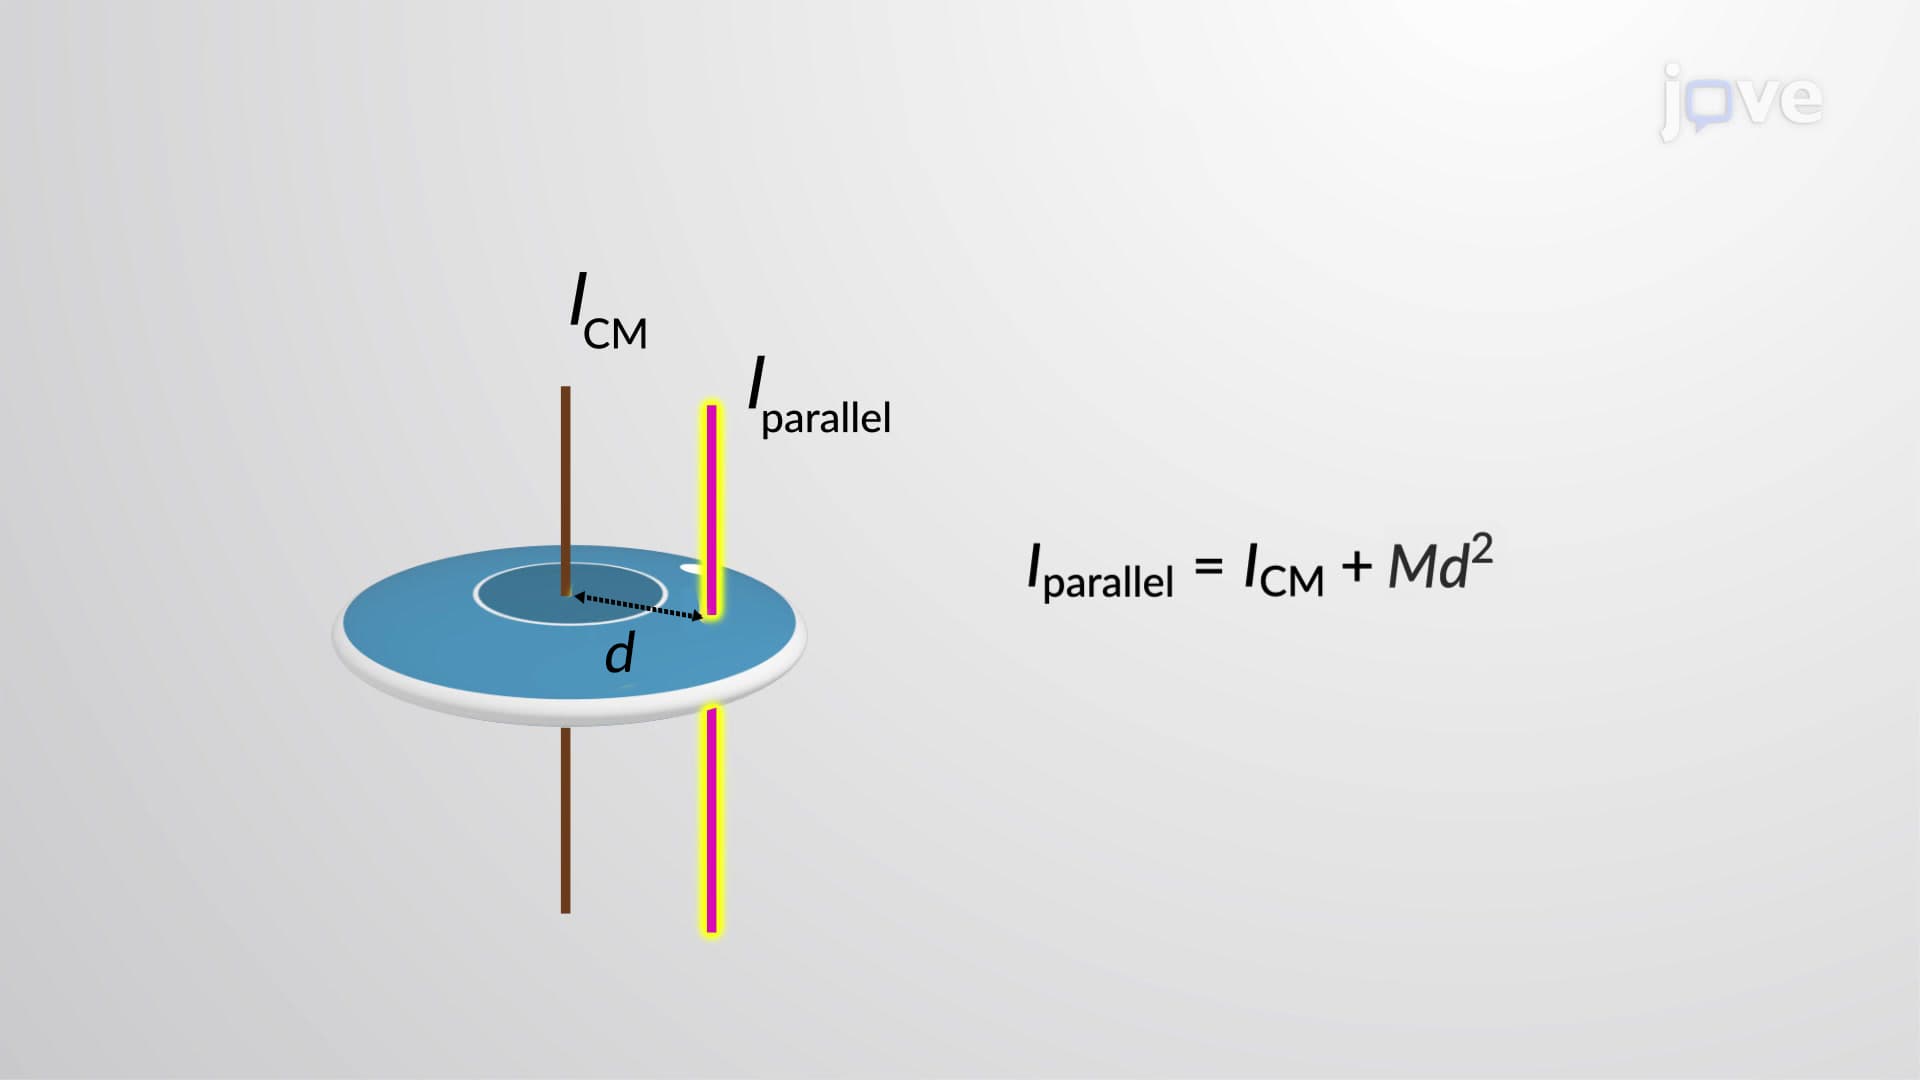
Parallel-axis Theorem