Related Experiment Video
Updated: Feb 11, 2026

Selective Capture of 5-hydroxymethylcytosine from Genomic DNA
Published on: October 5, 2012
Benchmarking Sparse Variable Selection Methods for Genomic Data Analyses
Hema Sri Sai Kollipara1, Tapabrata Maiti1, Sanjukta Chakraborty2
1Department of Statistics & Probability, Michigan State University, East Lansing, Michigan, USA.

Abstract:
Genomics and other studies encounter many features and a selection of essential features with high accuracy is desired. In recent years, there has been a significant advancement in the use of Bayesian inference for variable (or feature) selection. However, there needs to be more practical information regarding their implementation and assessment of their relative performance. Our goal in this paper is to perform a comparative analysis of approaches, mainly from different Bayesian genres that apply to genomic analysis. In particular, we are examining how well shrinkage, global-local, and mixture priors, SUSIE, and a simple two-step procedure-namely, RFSFS, which we propose-perform in terms of several metrics: FDR, FNR, F-score, and mean squared prediction error under various simulation scenarios. There is no single method that outperforms others uniformly across all scenarios and in terms of variable selection and prediction performance metrics. So, we order the methods based on the average ranking across different scenarios. We found LASSO, spike-and-slab prior with normal slab (SN), and RFSFS are the most competitive methods for FDR and F-score when features are uncorrelated. When features are correlated, SN, SuSIE, and RFSFS are the most competitive methods for FDR whereas LASSO has an edge over SuSIE in terms of F-score. For illustration, we have applied these methods to analyzed The Cancer Genome Atlas Program (TCGA) renal cell carcinoma (RCC) data and have offered methodological direction.

Related Concept Videos
 01:25
Selected Data About Geographic Locations
 02:02
Genomics
 01:11
Variability: Analysis
The range is a simple measure of variability, indicating the difference between the highest and...
 01:09
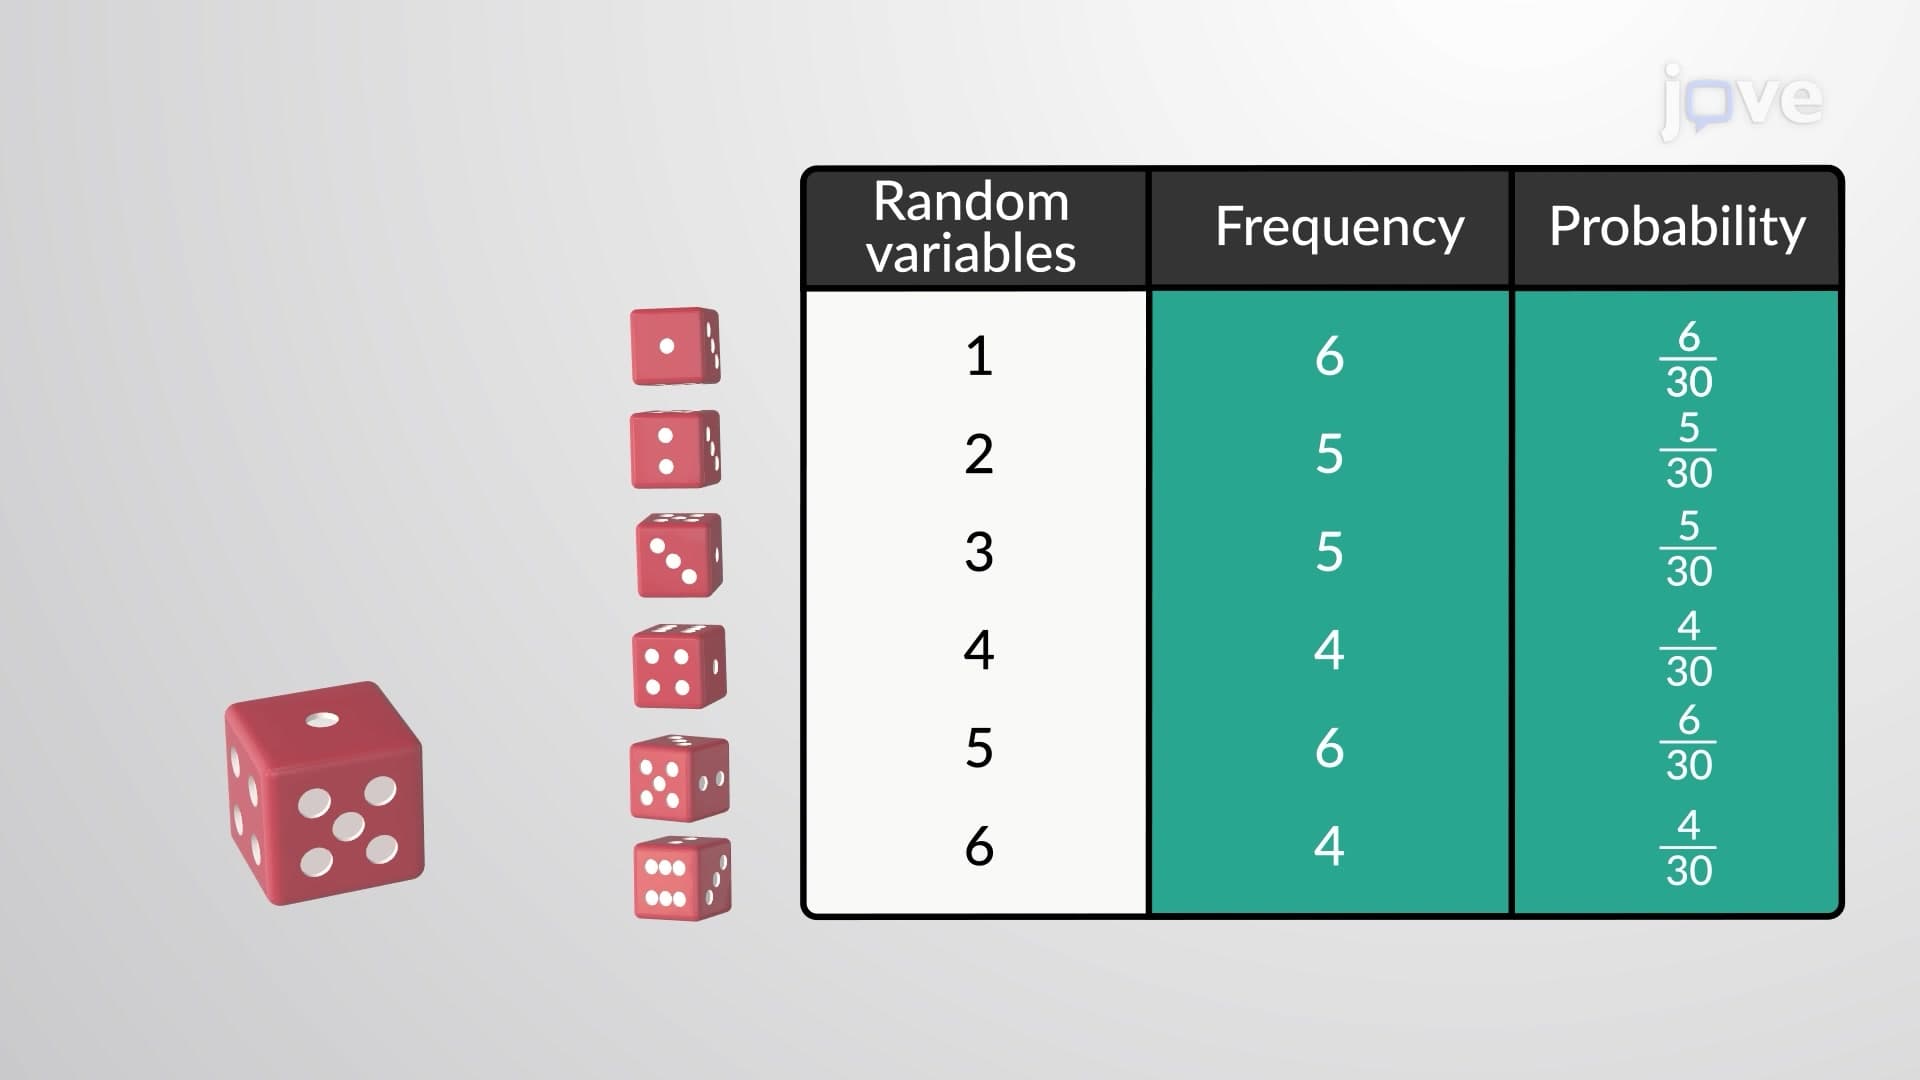
Random Variables
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
 01:25
Statistical Methods for Analyzing Epidemiological Data
 01:30
Graphs of Equations in Two Variables