Related Experiment Video
Updated: Feb 13, 2026

Setting Limits on Supersymmetry Using Simplified Models
Published on: November 15, 2013
Simplifying radiology reports with large language models: privacy-compliant open- versus closed-weight models
Annemarie Katharina Proff1,2, Babak Salam1,2, Mohammed Hayawi3
1Department of Diagnostic and Interventional Radiology, University Hospital Bonn, Bonn, Germany.

Objectives:
Large language models (LLMs) like generative pre-trained transformer (GPT) can simplify radiology reports for medical laypersons, but privacy concerns limit their clinical applicability. This study compares closed-weight and in-hospital deployed privacy-compliant open-weight LLMs in generating patient-friendly radiology reports.
Materials And Methods:
A total of 60 radiology reports containing indication and impression sections (15 each from X-ray, ultrasound, CT, and MRI) were translated into lay-friendly versions using different LLMs: one commercial closed-weight model (GPT-4o) and two in-hospital deployed open-weight models (Llama-3-70b, Mixtral-8x22B). All reports were evaluated for readability (Flesch reading ease, reading time, word and sentence count). 21 medical laypeople assessed understandability using a 5-point Likert scale. Linear mixed-effects models and H-Kruskal-Wallis test were used for statistical analysis.
Results:
LLM-generated reports demonstrated significantly improved readability, achieving higher Flesch reading ease scores (GPT-4o: 46 ± 7, Llama-3-70b: 44 ± 6, Mixtral-8x22B: 44 ± 6, original: 17 ± 13; p < 0.001). All three LLM reports yielded markedly higher layperson-understandability ratings than the original reports (GPT-4o: 4.4 ± 0.1; Llama-3-70B: 4.3 ± 0.1; Mixtral-8x22B: 4.1 ± 0.1 vs. 1.5 ± 0.1; p < 0.001 for each), with no significant difference between GPT-4o and Llama-3-70B (p = 0.136). Mixtral-8x22B and Llama-3-70B produced more errors with potential for patient harm than GPT-4o (p = 0.005 and p = 0.025, respectively). Imaging modality did not influence understandability (all p > 0.05).
Conclusion:
LLMs substantially improved layperson understanding of radiology reports. Open-weight, on-premises LLMs like Llama-3-70B show strong potential for real-world clinical use, though human oversight is still required.
Key Points:
Question Can locally deployed open-weight large language models (LLMs) improve the readability and understandability of radiology reports for medical laypersons at a level comparable to closed-weight models? Findings LLMs significantly improved quantitative readability scores and qualitative ratings of layperson understandability; Llama-3-70B and GPT-4o showed comparable performance, and although the open-source models exhibited a higher error rate, they still performed well overall. Clinical relevance Open-weight LLMs provide a privacy-compliant way to generate a template for patient-friendly radiology reports suitable for real-world clinical use.

Related Concept Videos
 01:30
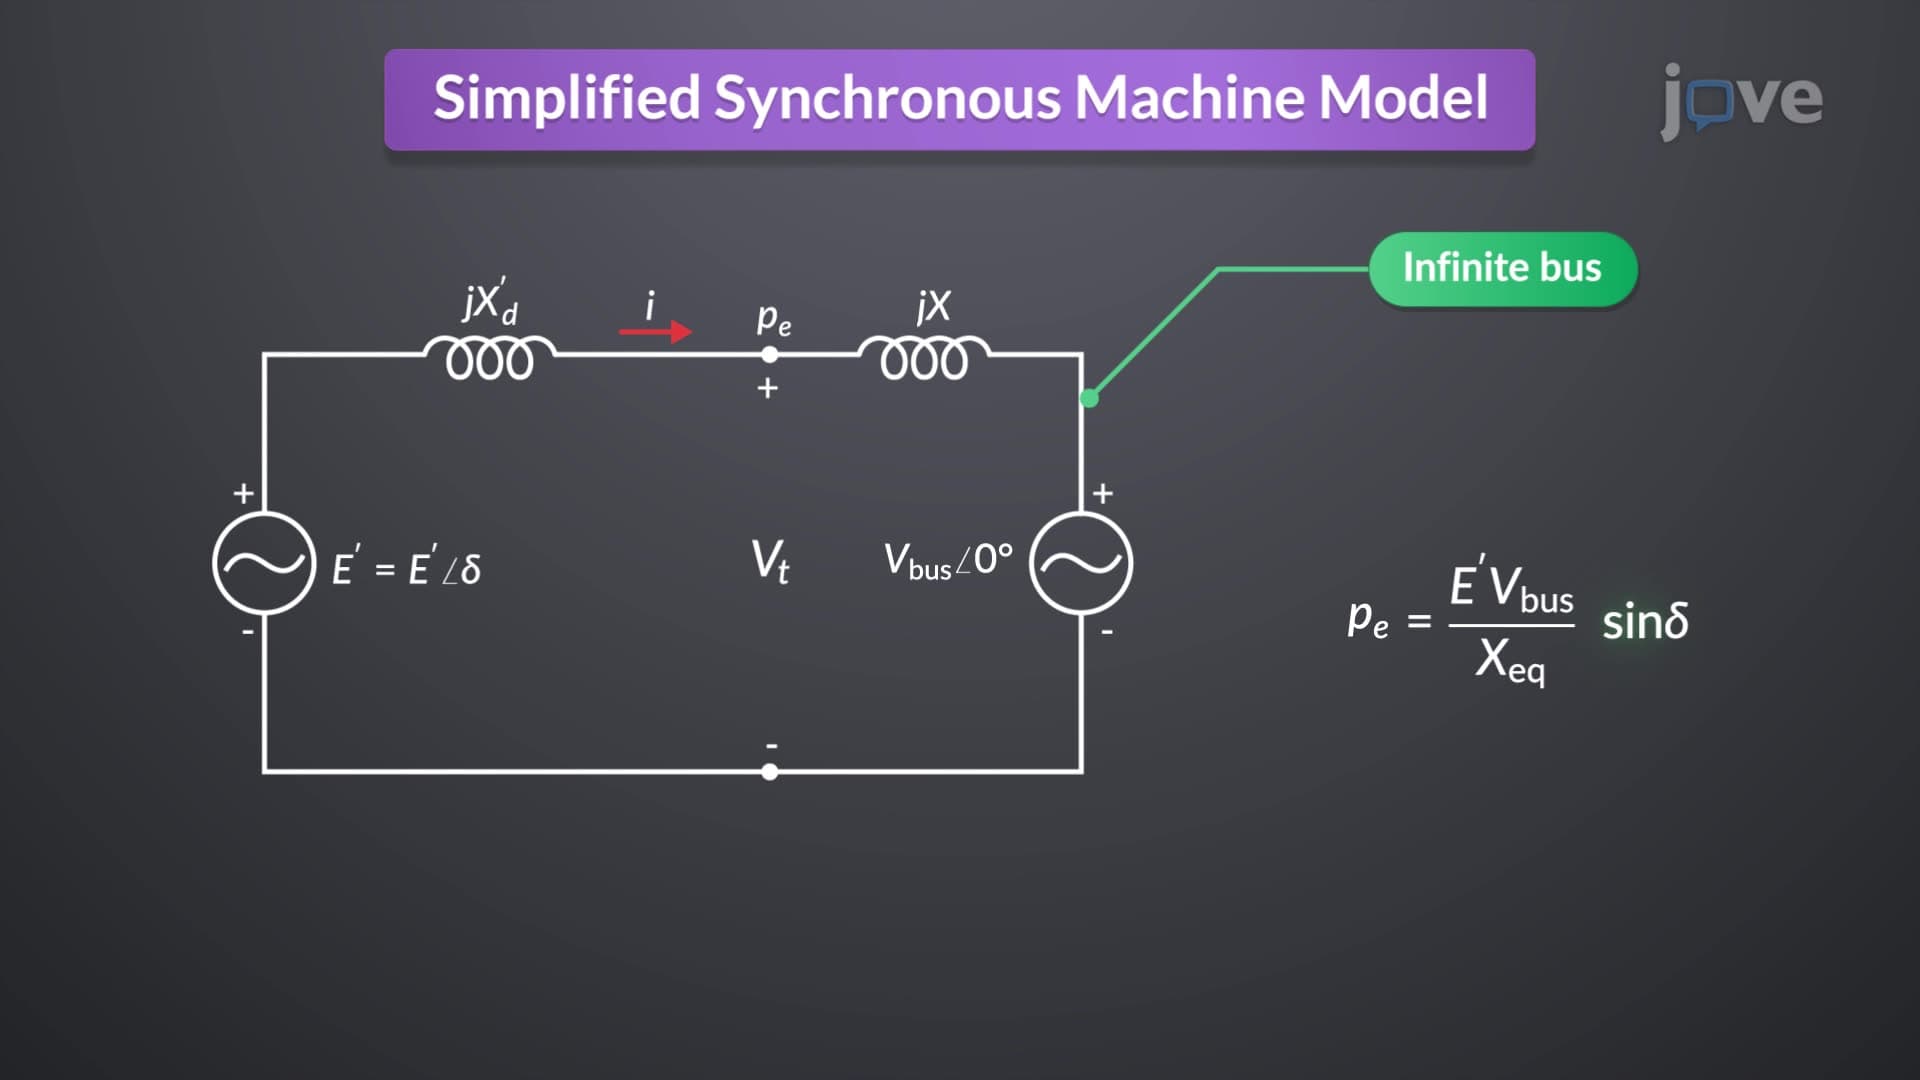
Simplified Synchronous Machine Model
In this model, each generator is connected to a...
 01:16
Language
Corballis and Suddendorf (2007) and Tomasello and Rakoczy (2003) highlight the role of language in...
 01:24
Components of Language
 01:22
Language Development
The critical period for language acquisition suggests that the ability to acquire language is at its peak early in life. As people age, this proficiency decreases. Language development begins very...
 01:27
Language and Cognition
 00:57
Weighted Mean
For example, consider the number of goals scored in the matches of a tournament. While computing the average number of goals scored in the tournament, it may be more important to...