Tail Task Risk Minimization in Meta-Learning From Theoretical Advances to Practical Strategies
Related Experiment Video
Updated: May 5, 2026
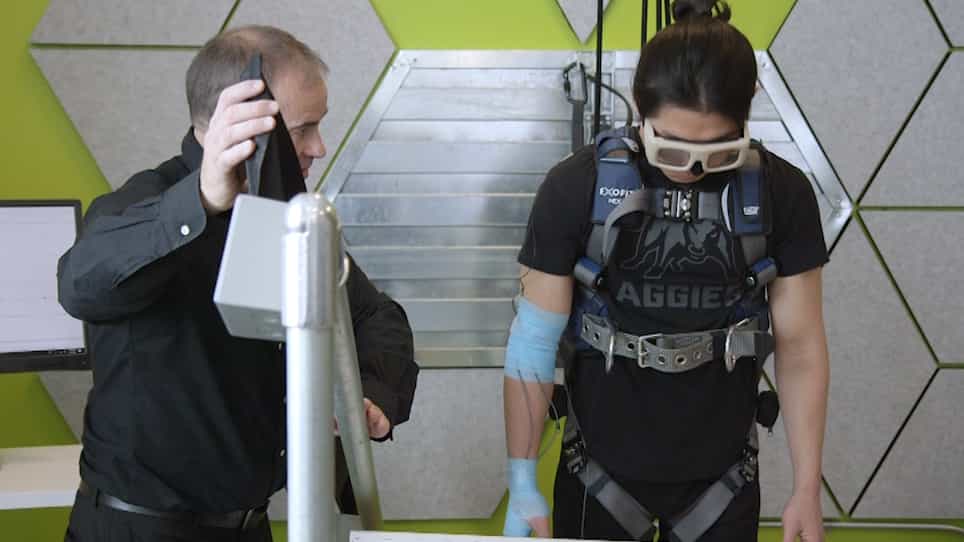
A Modified Lean and Release Technique to Emphasize Response Inhibition and Action Selection in Reactive Balance
Published on: March 19, 2020

Abstract:
Meta learning is a promising paradigm in the era of large models, and task distributional robustness has become an indispensable consideration in real-world scenarios. Recent advances have examined the effectiveness of tail task risk minimization in fast adaptation robustness improvement. This work contributes to more theoretical investigations and practical enhancements in the field. Specifically, we reduce the distributionally robust strategy to a max-min optimization problem, constitute the Stackelberg equilibrium as the solution concept, and estimate the convergence rate. Under certain scenarios, we incorporate the diversity regularizer into the acquisition criteria design during active subset selection and further improve meta learners' comprehensive generalization under tail risk minimization. In the presence of tail risk, we further derive the generalization bound, establish connections with estimated quantiles, systematically analyze the diversity regularizer's impacts, and practically improve the studied strategy. Accordingly, extensive evaluations on tasks such as few-shot sinusoid regression, system identification, image classification, and meta reinforcement learning, along with experiments on multimodal large models, demonstrate the significance, robustness and scalability of our proposal.
Related Concept Videos
 01:29
Mechanistic Models: Compartment Models in Algorithms for Numerical Problem Solving
In individual population analyses, different algorithms are employed, such as Cauchy's method, which uses a...
 01:14
Avoidance Learning and Learned Helplessness
Avoidance learning occurs when an organism learns that a specific behavior can prevent an unpleasant outcome. For example, a student who receives a bad grade may start studying harder to avoid future poor grades. This behavior persists even when the negative outcome is no longer present. Avoidance learning is powerful because it maintains behavior in the absence of the...