Related Experiment Video
Updated: Feb 26, 2026

Author Spotlight: Efficient Image Recognition Using Directional Gradient Histogram Technique and Support Vector Machines
Published on: January 5, 2024
DHS-AE: A Distributed Support Vector Machine With Adaptive Regularization Parameters for Different Data Distributions

Abstract:
In distributed machine learning scenarios, the difference in data distribution among different nodes is a key issue that cannot be ignored. However, existing methods make it difficult to autonomously adjust model parameters for dynamically changing data distributions, leading to inflexible global decision boundaries with insufficient local adaptation. To address this problem, we propose a distributed hybrid support vector machine (SVM) based on the adaptive ensemble selection of regularization parameters, DHS-AE. The model utilizes the data structure information to cut the data space and thus identify data distribution characteristics. The SVM, integrated with regularization parameters that are adaptively determined within specific ranges, is utilized in the local subspace to enable real-time adjustment of decision boundaries in response to distribution changes, thereby further reducing the computational overhead. The generalization bound of DHS-AE is theoretically established using covering numbers, and the fast convergence speed and consistency are derived. In practical applications, we verify the excellent performance of the DHS-AE using a large number of real datasets.
Related Concept Videos
 01:26
Distributions to Estimate Population Parameter
 01:25
Choosing Between z and t Distribution
 01:31
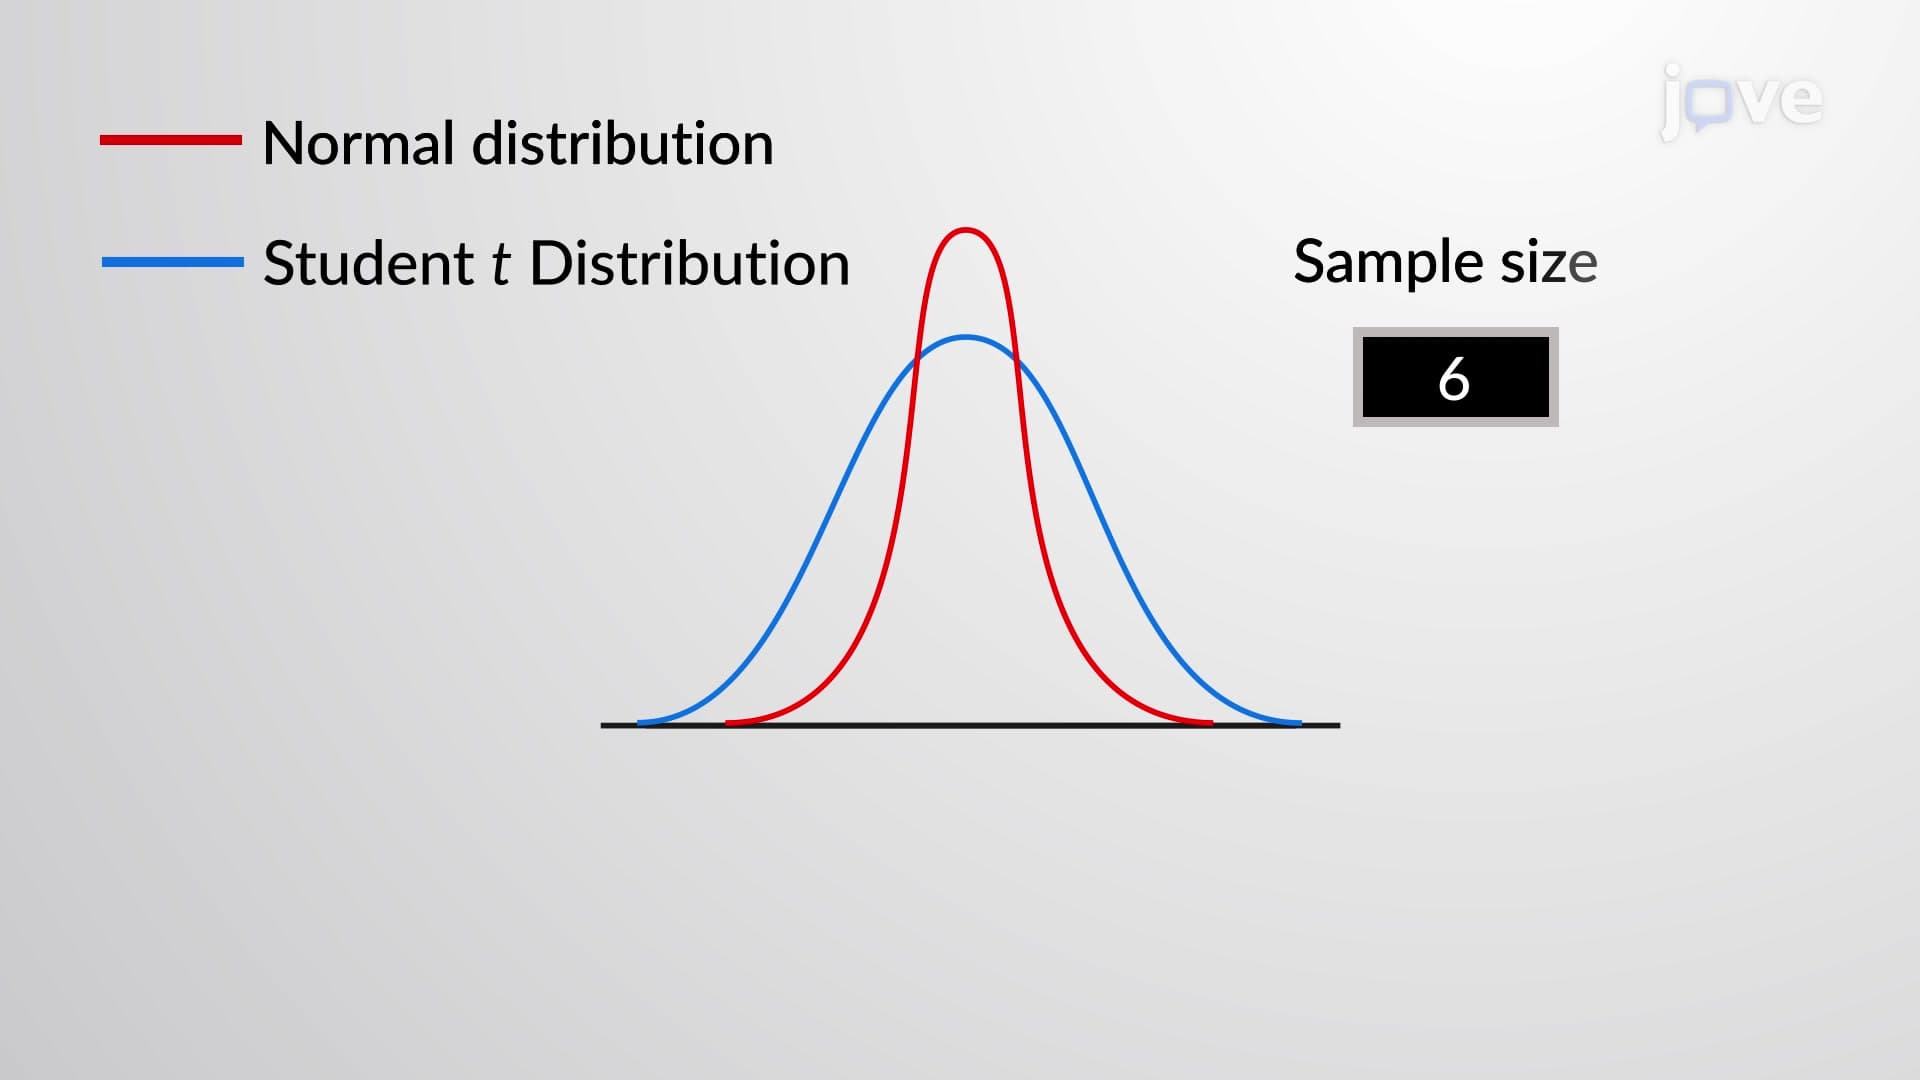
Student t Distribution
The Student t distribution was developed by William S. Goset (1876–1937) of the...
 01:06
Model Approaches for Pharmacokinetic Data: Distributed Parameter Models
The distributed parameter models are specifically designed to account for variations and differences in some drug classes. This model is particularly useful for assessing regional concentrations of anticancer or...
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:19
Survival Tree
Building a Survival Tree
Constructing a...