Related Experiment Video
Updated: Feb 28, 2026
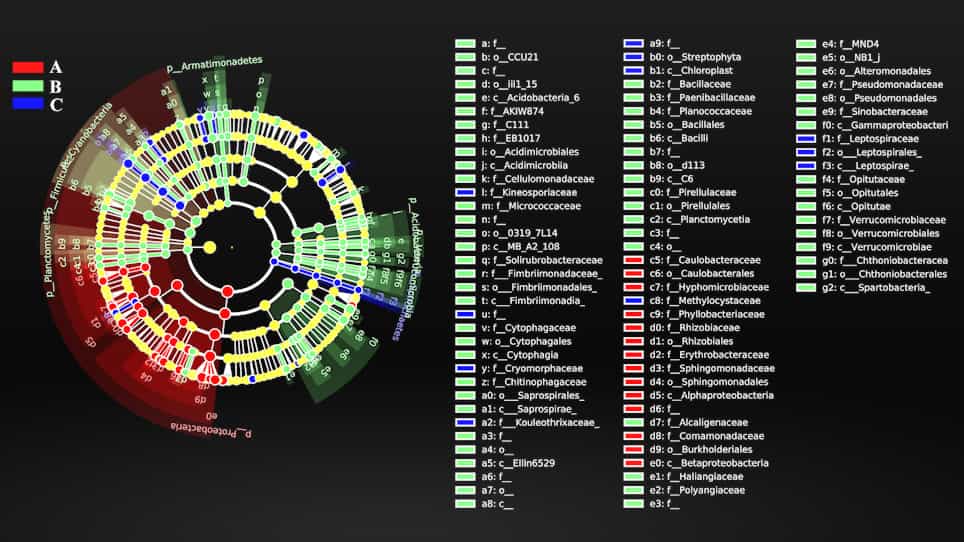

Assisted Selection of Biomarkers by Linear Discriminant Analysis Effect Size LEfSe in Microbiome Data
Published on: May 16, 2022
Sparse robust discriminant analysis for high-dimensional and heavy-tailed data
Weijian Huang1, Qing Mai2, Jing Zeng1
1Faculty of Business for Science & Technology, School of Management, University of Science and Technology of China, Hefei, Anhui 230026, China.

Abstract:
With advancements in data-collecting techniques, large-scale data have become increasingly prevalent in medical science. For instance, gene expression data provide information on tens of thousands of genes, while diagnostic imaging, such as the magnetic resonance imaging, generates a vast volume of pixels. While various sparse linear discriminant analysis methods have been developed to handle high-dimensional medical data, they often assume the light-tailed predictors, which is frequently violated in real applications. In this paper, we propose a robust classifier under an elliptically contoured discriminant analysis (EDA) model, which accommodates both light-tailed and heavy-tailed data. In addition, we assess the prediction accuracy using the balanced rate, a more appropriate metric when the data is imbalanced. Under the EDA model, we identify the intrinsic dimension-reduction subspace that captures all information from predictors for achieving the lowest balanced rate. By leveraging this dimension-reduction subspace, we propose a robust high-dimensional classifier, which reduces data dimensionality through subspace projection, followed by prediction on the reduced data. Theoretically, our proposal simultaneously enjoys the consistencies of subspace estimation, variable selection, and prediction accuracy under only finite fourth-moment condition of predictors. Numerically, we apply our method to synthetic data and three real datasets, including two lung cancer data and a leukemia data. The empirical findings support the superiority of our approach over other state-of-the-art methods.


Related Concept Videos
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
 01:19
Expected Frequencies in Goodness-of-Fit Tests
 01:08
Outliers and Influential Points
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:12
What Are Outliers?
The z score is used to find outliers or unusual values. It should be noted that any values beyond -2 and +2 are...