Related Experiment Video
Updated: Mar 15, 2026

Operant Protocols for Assessing the Cost-benefit Analysis During Reinforced Decision Making by Rodents
Published on: September 10, 2018
AF-CuRL: Stable Reinforcement Learning for Resource-Constrained Long-Form Reasoning in Edge-Intelligent Systems
Ziqin Yan1,2, Yurong Wang2,3, Qingsheng Yue1
1School of Electronic and Information Engineering, Lanzhou Jiaotong University, Lanzhou 730070, China.

Abstract:
Resource-constrained intelligent systems increasingly require reliable long-form reasoning capabilities under limited computational and memory budgets, particularly in edge and embedded sensing environments. However, reinforcement learning for long-horizon decision generation remains highly unstable in such low-resource settings due to severe reward sparsity and imbalanced credit assignment, which often lead to non-convergent or excessively verbose generation behavior. In this work, we propose AF-CuRL (Answer-Focused Curriculum Reinforcement Learning), a lightweight reinforcement learning framework designed to stabilize long-form generation without increasing model size or computational cost. AF-CuRL improves optimization learnability through two complementary objective-level designs: (1) answer-focused token reweighting, which concentrates policy updates on reward-critical regions of generated sequences to alleviate credit assignment imbalance, and (2) a two-phase curriculum reward schedule that prioritizes stable termination and output regularity before shifting toward correctness-oriented optimization. We evaluate AF-CuRL on a 1.5B-parameter language model under strictly constrained training settings, using mathematical reasoning tasks as a controlled and reproducible proxy for long-horizon, rule-based decision-making commonly encountered in intelligent sensing and embedded systems. Experimental results demonstrate consistent improvements in both decision accuracy and generation regularity, including higher termination reliability and reduced generation length, compared with standard sequence-level reinforcement learning baselines. These results suggest that, for resource-limited and edge-intelligent systems, structured objective design can be more effective than model scaling for achieving stable and efficient long-form reasoning, providing a practical reinforcement learning solution for intelligent systems operating under real-world constraints.
Related Concept Videos
 01:30
Reasoning
Inductive reasoning involves deriving generalizations from specific observations. This type of reasoning helps form beliefs about the world. For example,...
 01:13
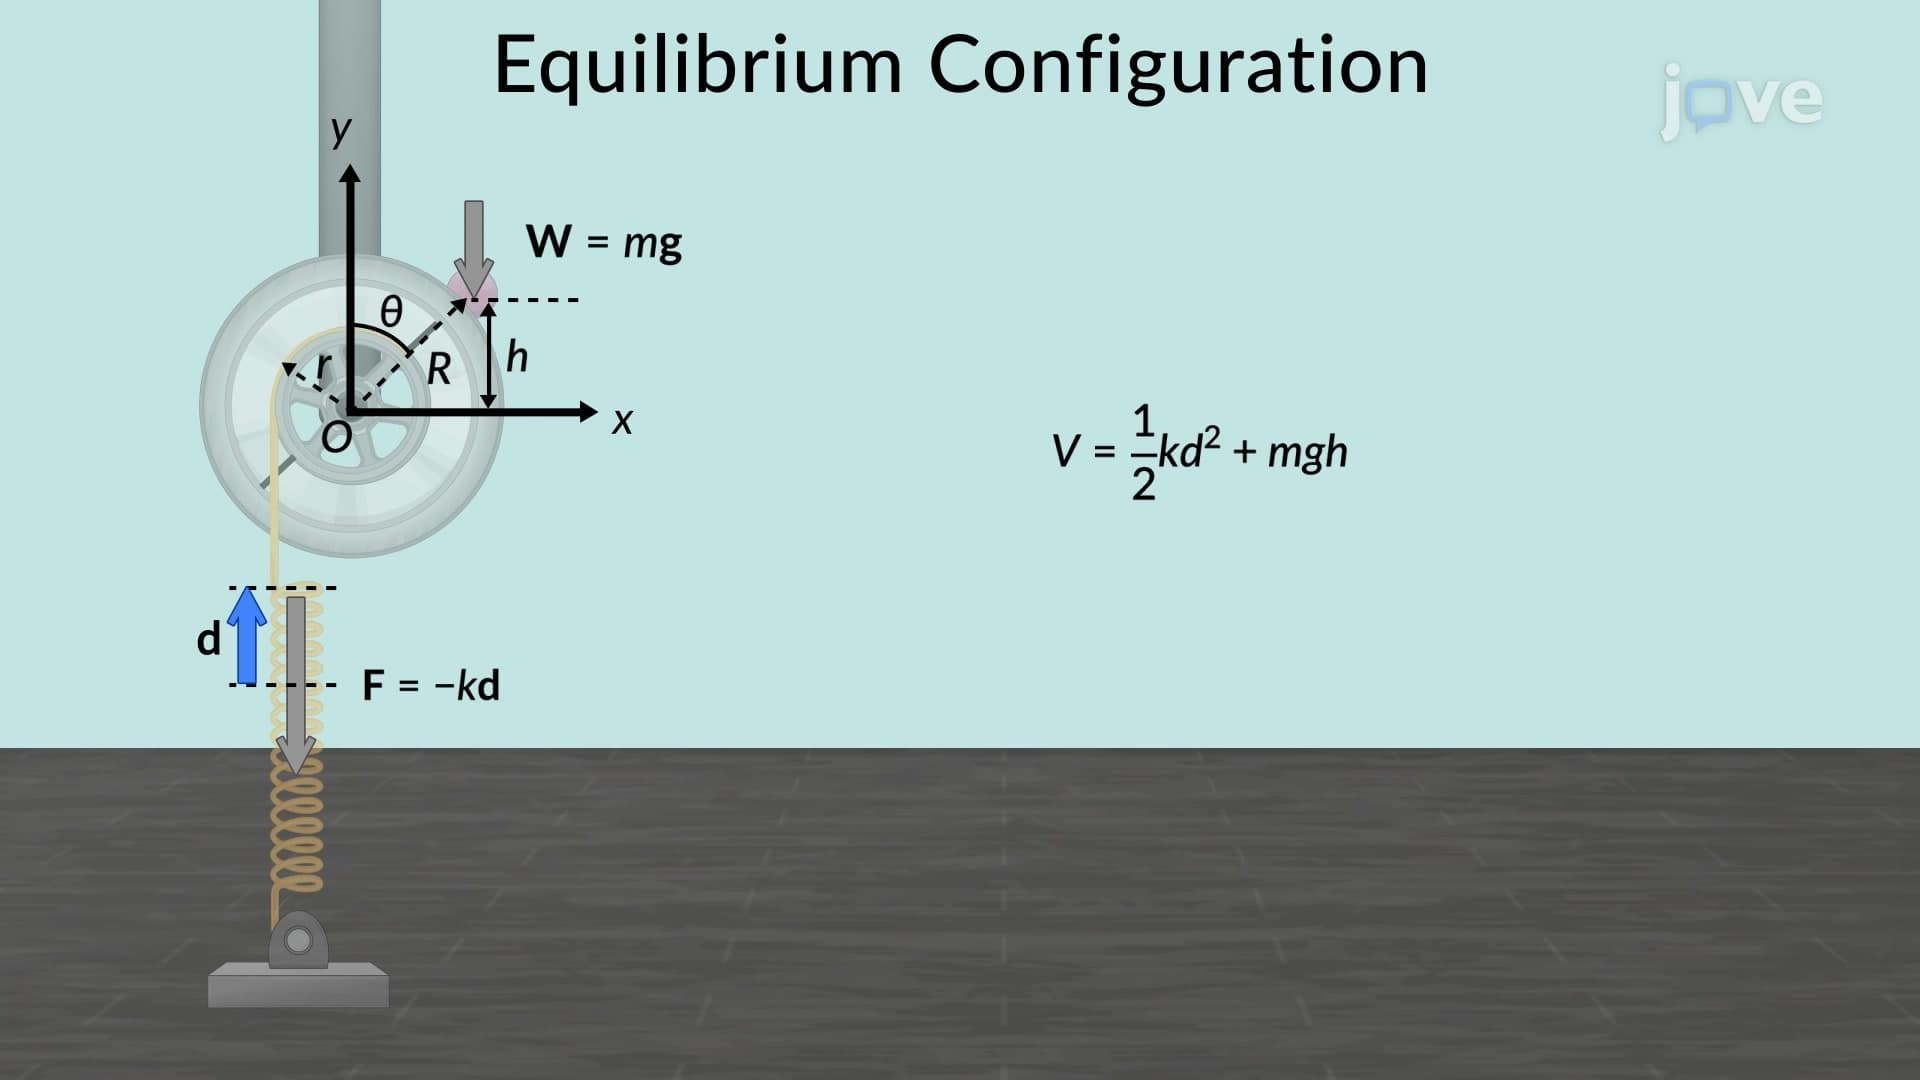
Stability of Equilibrium Configuration: Problem Solving
Problem-solving in the context of the stability of equilibrium configuration...
 01:37
Reason and Intuition
 01:16
Statically Indeterminate Problem Solving
 00:59
Inductive Reasoning
Inductive reasoning is common in descriptive science. A life scientist makes observations and records them. This data can be qualitative or...
 01:12
Observational Learning