Related Experiment Video
Updated: Mar 18, 2026
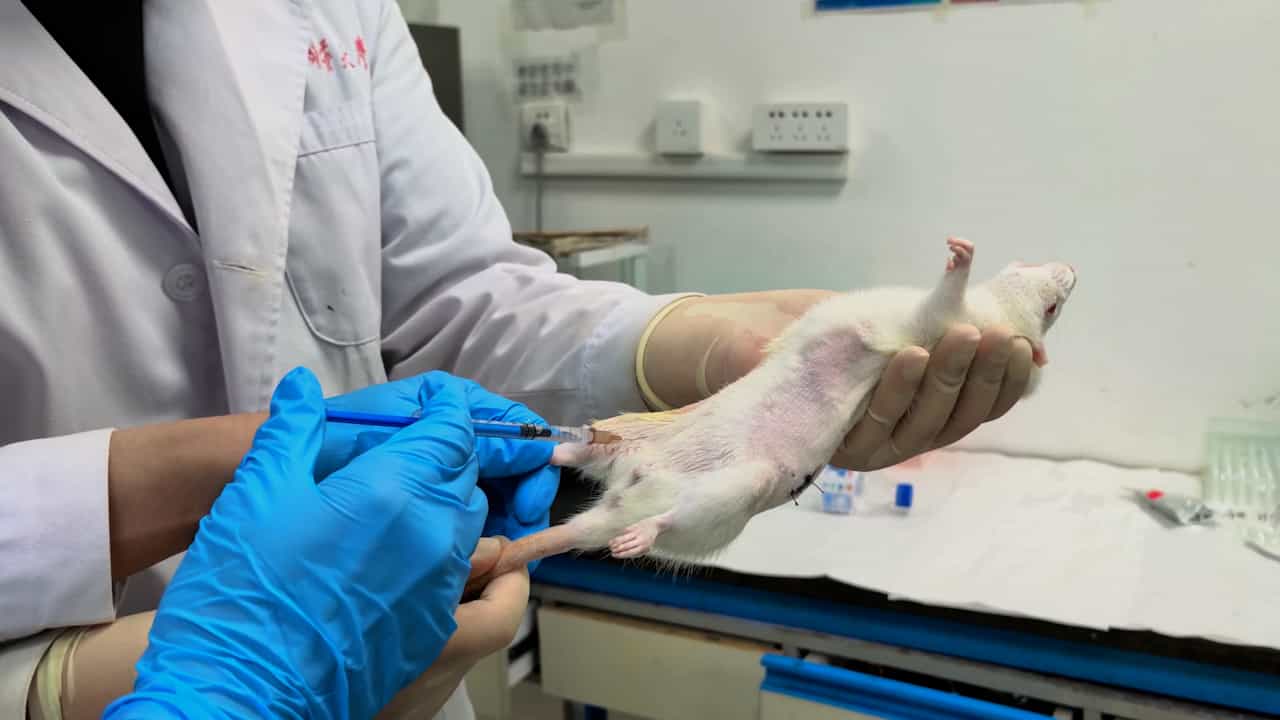

The Creation of a Rat Model for Osteosarcopenia via Ovariectomy
Published on: February 21, 2025
Evaluating the performance of large language models in sarcopenia-related patient queries: a foundational assessment
Tao Huang1, Ben Kirk2, Jacqueline Close3
1Department of Orthopaedics and Traumatology, The Chinese University of Hong Kong, Hong Kong SAR, China.

Background:
Large Language Models (LLMs) have shown promise in clinical applications but their performance in specialized areas such as sarcopenia remains understudied.
Methods:
A panel of sarcopenia clinician researchers developed 20 standardized patient-centered questions across six clinical domains. Each question was input into all three LLMs, and responses were anonymized, randomized, and independently assessed by three clinician researchers. Accuracy was graded on a four-point scale ("Poor" to "Excellent"), and comprehensiveness was evaluated for responses rated "Good" or higher using a five-point scale.
Results:
All LLMs achieved good performance, with no responses rated "Poor" across any domain. Deepseek had the longest and most detailed responses (mean word count: 583.75 ± 71.89) and showed superior performance in "risk factors" and "prognosis." ChatGPT provided the most concise replies (359.5 ± 87.89 words, p = 0.0011) but achieved the highest proportion of "Good" ratings (90%). Gemini excelled in "pathogenesis" and "diagnosis" but received the most critical feedback in "prevention and treatment." Although trends in performance differences were noted, they did not reach statistical significance. Mean comprehensiveness scores were also similar across models (Deepseek: 4.017 ± 0.77, Gemini: 3.97 ± 0.88, ChatGPT: 3.953 ± 0.83; p > 0.05).
Conclusion:
Despite minor differences in performance across domains, all three LLMs demonstrated acceptable accuracy and comprehensiveness when responding to sarcopenia-related queries. Their comparable results may reflect similarly recent training data and language capabilities. These findings suggest that LLMs could potentially serve as a valuable tool in patient education and care on sarcopenia. This study provides an initial, expert-based assessment of LLM information quality regarding sarcopenia. While the responses demonstrated good accuracy, this evaluation focuses on content correctness from a clinical perspective. Future research must complement these findings by directly engaging older adult cohorts before clinical implementation can be considered. However, human oversight remains essential to ensure safe and appropriate assessment and individually tailored advice and management.

Related Concept Videos
 02:07
Improving Translational Accuracy
02:07Improving Translational Accuracy