Related Experiment Video
Updated: Apr 2, 2026

Mining Spatial Transcriptomics Datasets using DeepSpaceDB
Published on: September 5, 2025
Sparser2Sparse: Single-shot Sparser-to-Sparse Learning for Spatial Transcriptomics Imputation with Natural Image

Abstract:
Spatial transcriptomics (ST) has revolutionized biomedical research by enabling high-resolution gene expression profiling within tissues. However, the high cost and scarcity of high-resolution ST data remain significant challenges. We present Single-shot Sparser-to-Sparse (S2S-ST), a novel framework for accurate ST imputation that requires only a single and low-cost sparsely sampled ST dataset alongside widely available natural images for co-training. Our approach integrates three key innovations: (1) a sparser-to-sparse self-supervised learning strategy that learns to predict partially observed sparse regions from even sparser subsets within the same sample, leveraging intrinsic spatial patterns in ST data; (2) cross-domain co-learning with natural images to enhance feature representation, and (3) a Cascaded Data Consistent Imputation Network (CDCIN) that iteratively refines predictions while preserving sampled gene data fidelity. Extensive experiments on diverse tissue types, including breast cancer, liver, and lymphoid tissue, demonstrate that our method outperforms state-of-the-art approaches in imputation accuracy. By enabling robust ST reconstruction from sparse inputs, our framework significantly reduces reliance on costly high-resolution data, facilitating potential broader adoption in biomedical research and clinical applications. Code is available at: https://github.com/Advanced-AI-in-Medicine-and-Physics-Lab/S2S-ST.
Related Concept Videos
 02:07
Improving Translational Accuracy
02:07Improving Translational Accuracy
 00:56
Extraction: Advanced Methods
 01:18
Imaging Biological Samples with Optical Microscopy
In optical microscopy, the specimen to be viewed is placed on a glass slide and clipped on the stage...
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:14
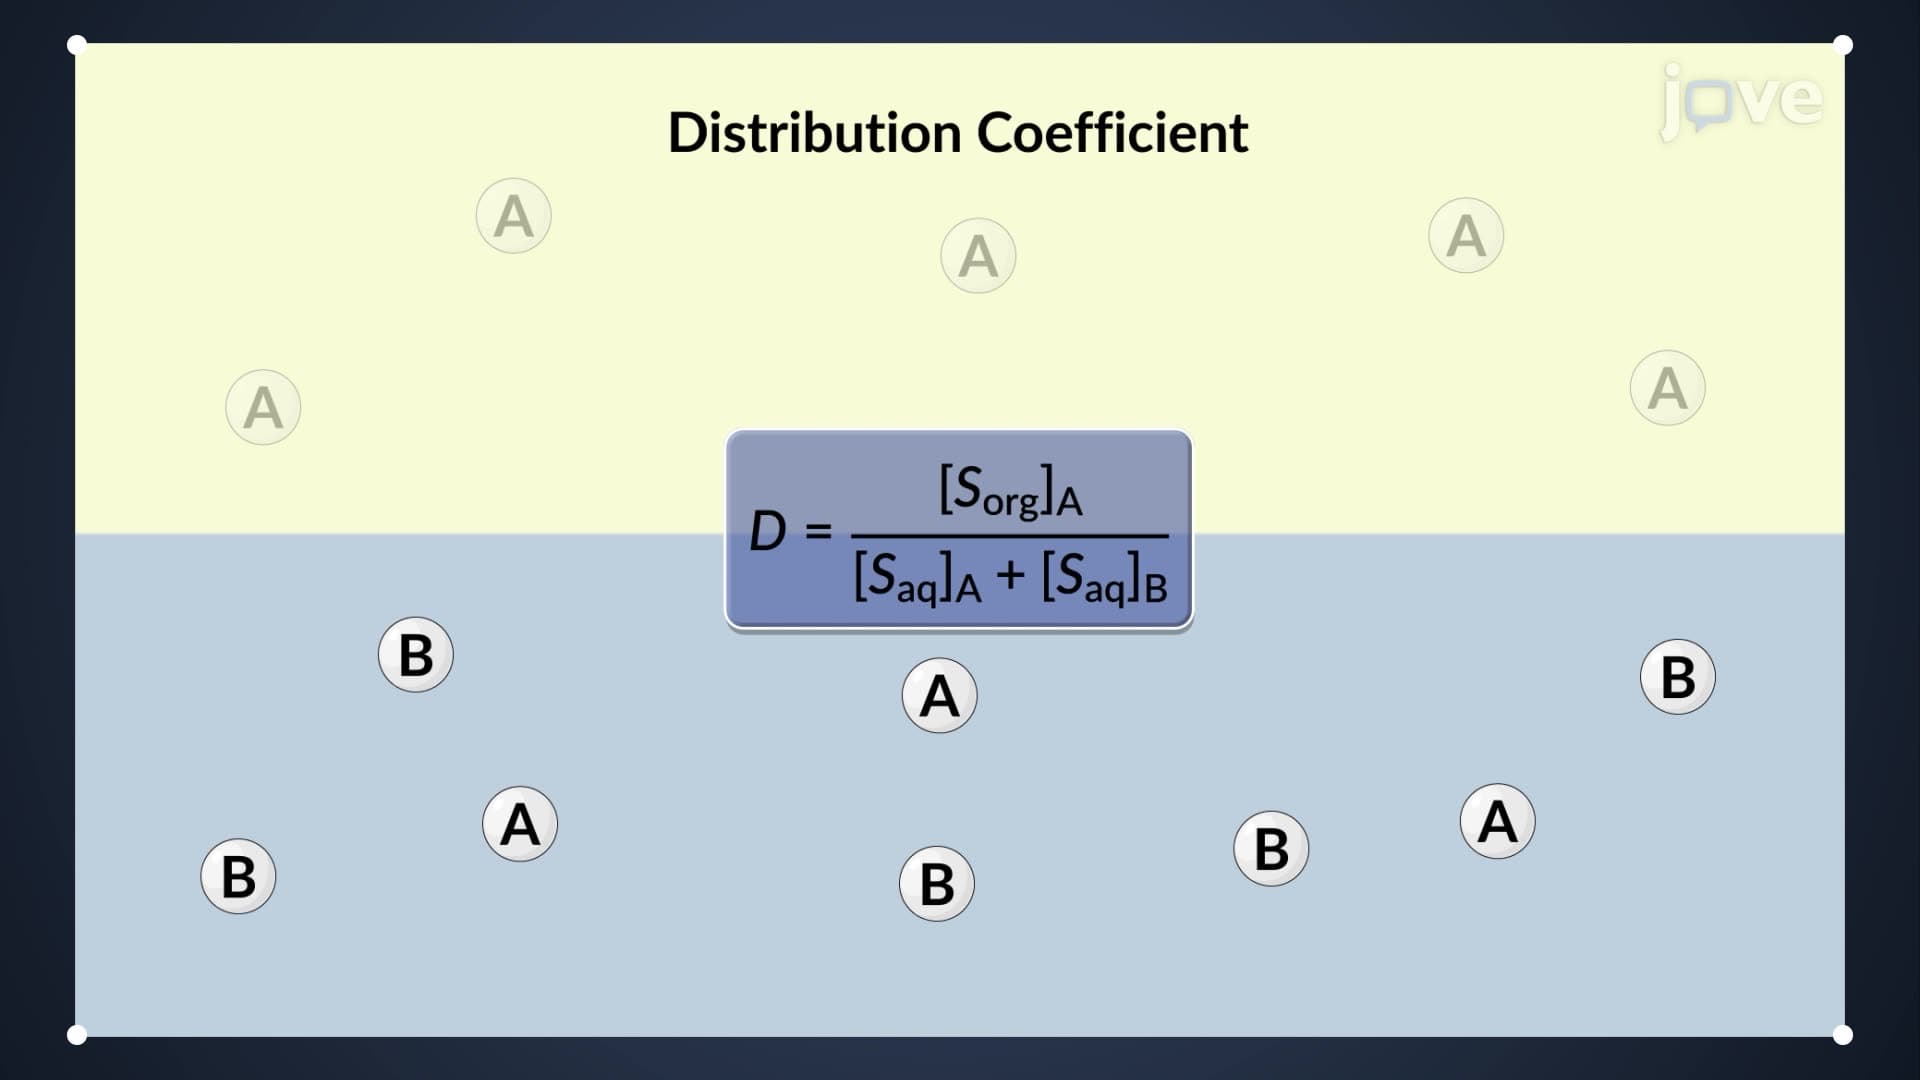
Extraction: Partition and Distribution Coefficients
For extracting a solute from an aqueous phase into an...