Related Experiment Video
Updated: Apr 7, 2026
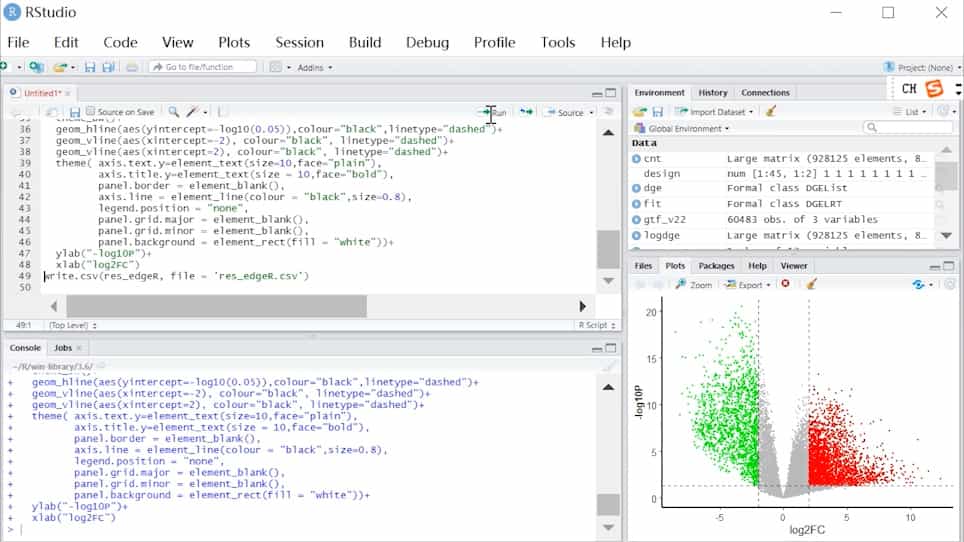

Three Differential Expression Analysis Methods for RNA Sequencing: limma, EdgeR, DESeq2
Published on: September 18, 2021
A Comparison of Combined P-value Methods for Gene Differential Expression Using RNA-Seq Data
Abdallah M Eteleeb1, Hunter N Moseley2, Eric C Rouchka1
1Department of Computer, Engineering and Computer Science, University of Louisville, Louisville, KY, USA.

Abstract:
Detection of differentially expressed (DE) genes across conditions within RNA-Seq datasets yields insight into the differences in biological processes at work in these conditions. Most methods available for discovering DE genes use statistical methods that model the data based on counting reads that map to individual genes. However, the distribution of reads across different regions of a gene can be heterogeneous. Summarizing reads at the gene level may provide inaccurate results. If genes are broken down into smaller regions, such as exons or even smaller fragments, and DE analysis is performed on those regions, the significance of the overall region can be determined using combined -values which may improve the accuracy of detecting DE genes. We therefore conducted analysis to consider the performance of widelyused methods for combining -values using publicly available RNA-Seq data. The combined -value methods include: Fisher's, Z-transform, Weighted Z-test, Minimum -value, Logit, and Weighted-sum methods. On liver and kidney data, the Weighted Z-test performs the best, detecting the highest number of truly DE genes. The effect of weights assigned in the Weighted Z-test enables this approach to outperform Fisher's method. On the MAQC datasets, our analysis indicates these methods perform similarly with a slight edge to the Weighted Z-test and Fisher's method in detecting true DE genes. However, the Weighted-sum clearly performs best in detecting true non-DE genes. Furthermore, these methods appear to have an inverse relationship in their performance in detecting DE genes versus non-DE genes in the MAQC datasets. These results indicate issues in properly combining high and low p-values, which may be due to a lack of independence between tests. Thus, a modified Fisher's method may provide more accurate results in these circumstances.
Related Concept Videos
 03:21
RNA-seq
Before the discovery of RNA-seq, microarray-based methods and Sanger sequencing were used for transcriptome analysis. However, while...
 02:26
Comparing Copy Number Variations and SNPs
Copy number variations or CNVs are the structural variations that cover more than 1kb of DNA sequence. The single nucleotide polymorphism (SNP), on the other hand, is a single nucleotide change or a point mutation that is found in more than 1%...