Graphicalized vision-language modeling for comprehensive lung nodule analysis and risk stratification
Related Experiment Video
Updated: Apr 13, 2026
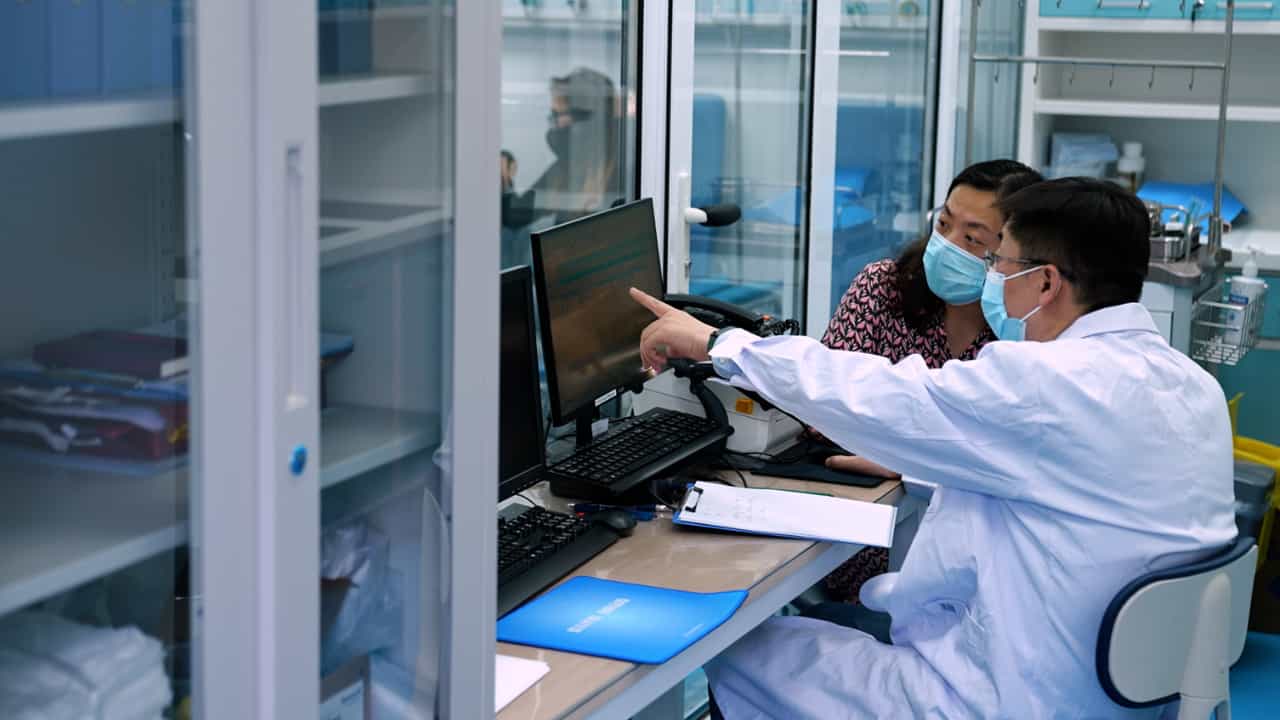
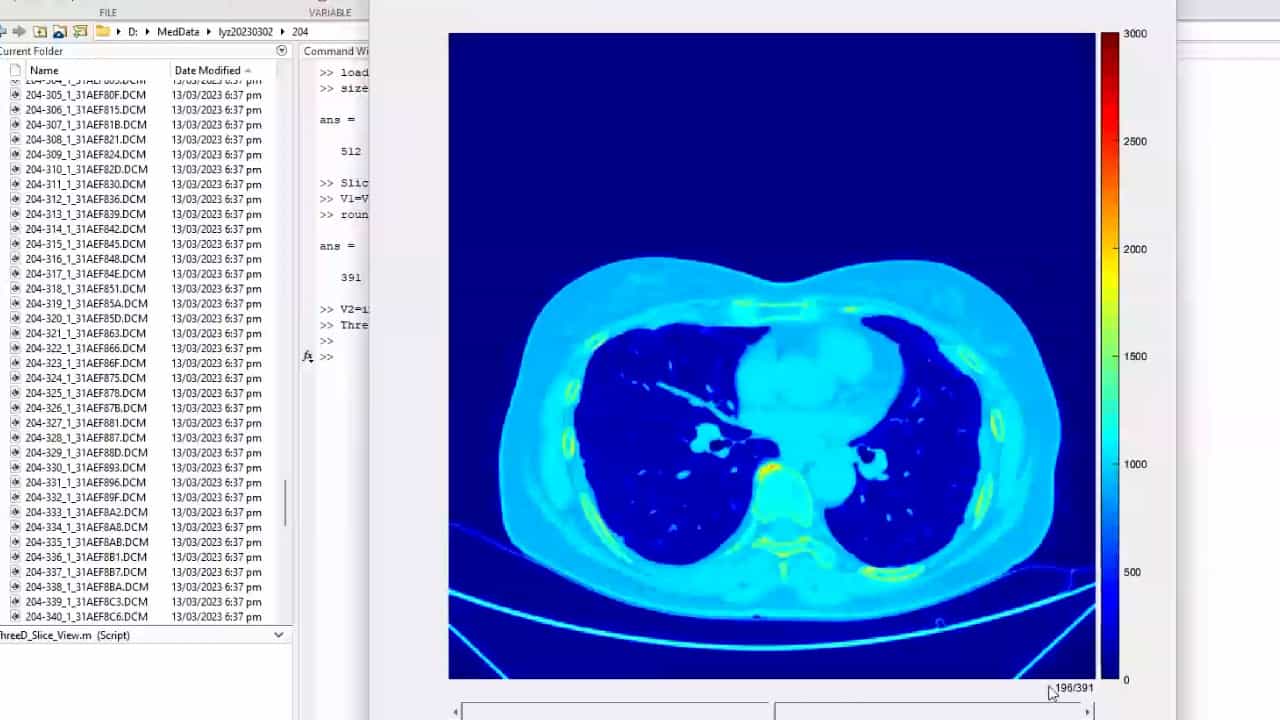
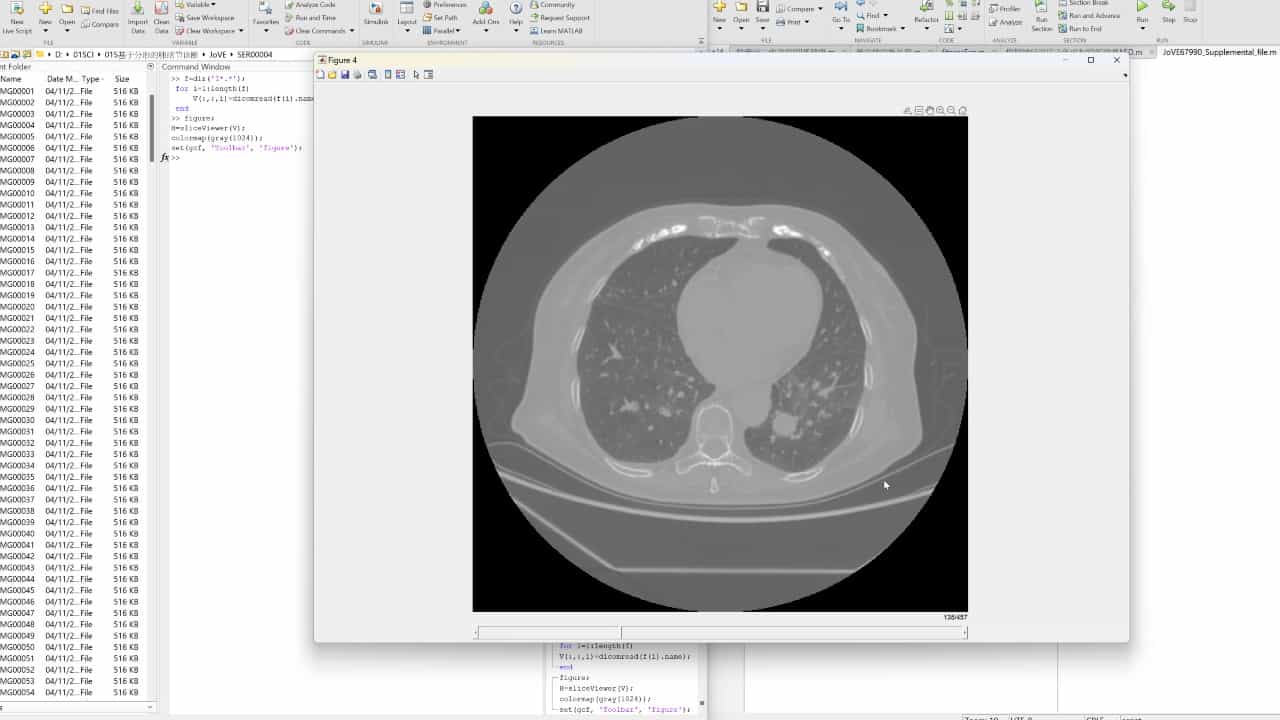
Author Spotlight: A 3D Digital Model for the Diagnosis and Treatment of Pulmonary Nodules
Published on: May 19, 2023
Danwen Zhao1, Junfeng Xi2, Xun Guo1
1Department of Thoracic Surgery, The Second Affiliated Hospital of Xi'an Jiaotong University, Xi'an, 710004, China.

Abstract:
Lung cancer care involves coupled tasks such as precise nodule detection, patient-level survival risk estimation, and nodule count quantification, typically handled by separate systems despite clear interdependence. We present VITALIS, a multimodal vision-language framework that fuses CT and PET/CT imaging with structured radiology text using a graph-aware Transformer: Laplacian diffusion enriches token features on an image-text graph, while structural and prior-guided attention focus computation on anatomically and clinically related contexts, followed by bidirectional image-text conditioning to form a fused patient representation. This representation parameterizes a continuous-time latent risk process governed by a context-modulated Neural ODE, enabling individualized continuous-time modeling of time-to-event risk. Task-specific heads decode the latent trajectory into nodule detection, nodule malignancy classification, survival risk estimation, and nodule count prediction. Evaluated on three public cohorts, the framework delivers accurate delineations, low-false-positive localization, calibrated survival risk estimates, and consistent nodule counts across tasks. These findings indicate that coupling graph-aware multimodal encoding with continuous-time latent dynamics provides a coherent basis for integrated diagnostic and prognostic modeling in lung cancer.