Related Experiment Video
Updated: Apr 18, 2026

Diagonal Method to Measure Synergy Among Any Number of Drugs
Published on: June 21, 2018
Comparative performance of large language models and Drugs.com versus Lexicomp for antiseizure medication drug-drug
Maazuddin Mohammed1, Mohammed Amer Khan1,2, Vaibhav Chaudhary1
1School of Pharmaceutical Sciences, Lovely Professional University, Phagwara, Punjab, India.

Background:
Antiseizure medications (ASMs) are frequently co-prescribed and are associated with a high risk of clinically significant drug-drug interactions (DDIs). Large language models (LLMs) are increasingly used for clinical queries, yet their performance in detecting ASM-related DDIs compared with established drug interaction databases remains uncertain.
Methods:
A cross-sectional comparative study evaluated 186 ASM-comedication pairs (126 classified as major/moderate by Lexicomp) using ChatGPT-4, DeepSeek-V3, and Drugs.com, with Lexicomp as the reference standard. Interactions were assessed for presence, severity, mechanism, and management recommendations. Major and moderate interactions were classified as clinically relevant for performance analysis. A post hoc iterative prompting analysis was conducted exclusively on false positive cases to assess improvements in specificity. Performance metrics included sensitivity, specificity, predictive values, and overall accuracy. Two clinical pharmacists independently assessed outputs for accuracy, clarity, and completeness, with adjudication by a third pharmacist.
Results:
Drugs.com demonstrated the best overall performance, with sensitivity 0.870, specificity 0.629, and accuracy 0.709. ChatGPT showed high sensitivity (0.842) but low specificity (0.358), reflecting frequent over prediction of interactions. Low specificity reflected frequent overclassification of non-interacting or minor pairs as clinically relevant, potentially leading to alert fatigue, unnecessary monitoring or therapeutic modification. DeepSeek achieved the highest sensitivity (0.877) but the lowest specificity (0.200) and the greatest number of false positives. Iterative prompting substantially improved specificity for ChatGPT (0.77) and DeepSeek (0.42), correcting many false positive classifications.
Conclusion:
ChatGPT and DeepSeek provided broad interaction overviews but demonstrated limited specificity under single-prompt conditions. Structured, evidence-constrained prompting improved specificity in false positive cases within this dataset. Drugs.com showed the most balanced performance compared with zero-shot LLM outputs. At present, LLMs may serve as supplementary explanatory tools, whereas structured drug interaction databases remain more reliable for primary DDI screening.
More Related Videos
Related Concept Videos
 01:30
Drug toxicity: Drug–Drug Interaction
 01:30
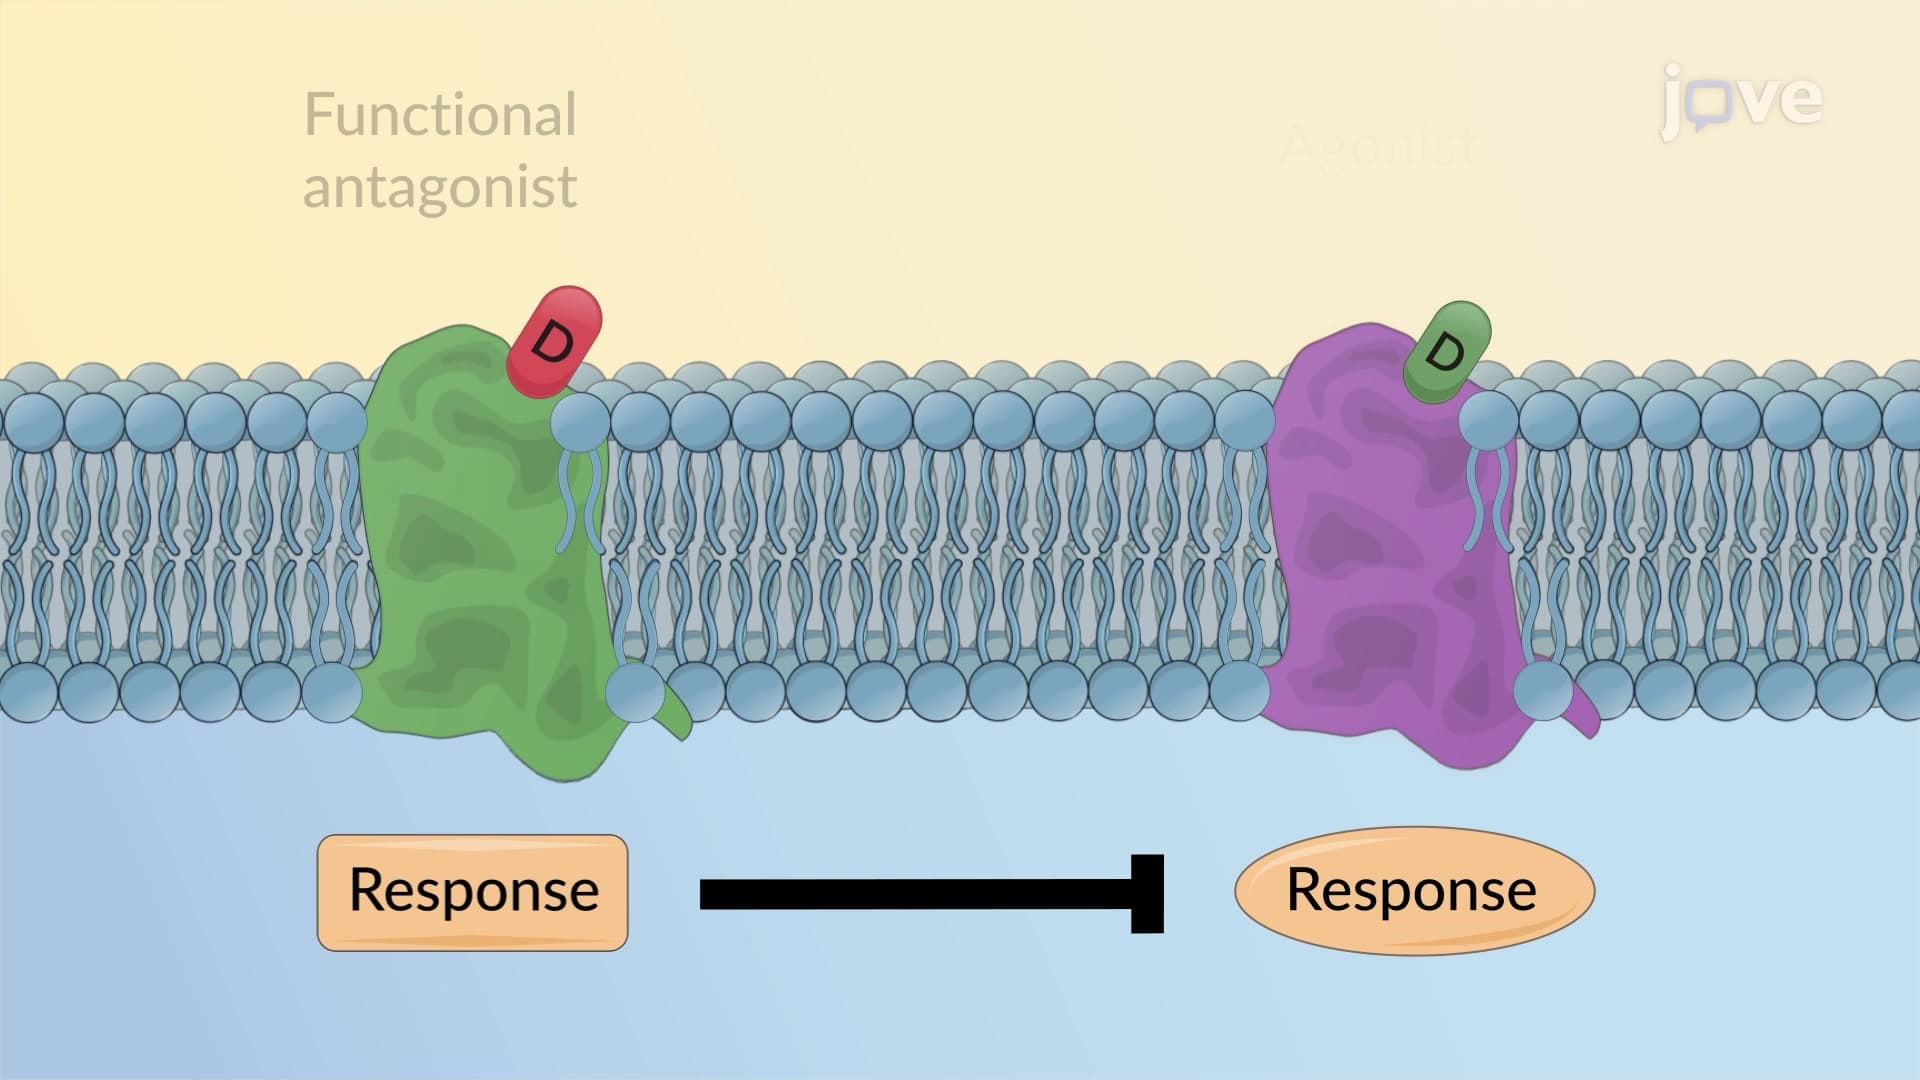
Combined Effects of Drugs: Antagonism
The most common type is receptor antagonism, where one drug acts as an antagonist to block the effects of another drug by...
 01:27
Combined Effects of Drugs: Synergism
Such synergistic combinations...
 01:20
Antiepileptic Drugs: Potassium Channel Activators
Ezogabine has gained approval as an adjunctive treatment...
 01:14
Agonism and Antagonism: Quantification
To quantify these effects, researchers use a dose-response curve, which provides valuable information about the potency and efficacy of a drug. Potency refers to...
 01:21
Factors Affecting Drug Response: Overview