Related Experiment Video
Updated: Apr 28, 2026
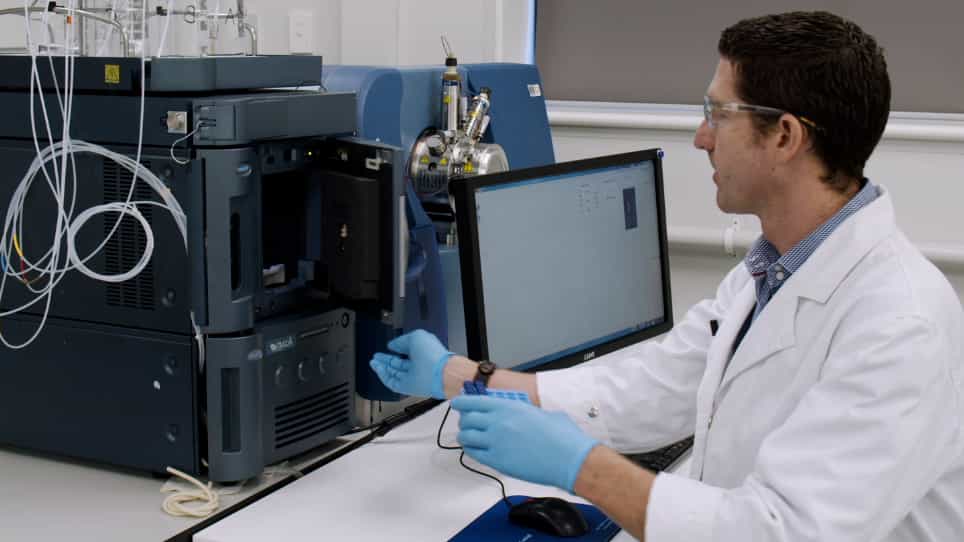

Untargeted Liquid Chromatography-Mass Spectrometry-Based Metabolomics Analysis of Wheat Grain
Published on: March 13, 2020
Information-Content-Informed Kendall-Tau Correlation Methodology: Interpreting Missing Values in Metabolomics as
Robert M Flight1,2,3, Praneeth S Bhatt4, Hunter N B Moseley1,2,3,5,6
1Markey Cancer Center, University of Kentucky, Lexington, KY 40536, USA.

Abstract:
Background: Almost all correlation measures currently available are unable to directly handle missing values. Typically, missing values are either ignored completely by removing them or are imputed and used in the calculation of the correlation coefficient. In either case, the correlation value will be impacted based on the perspective that the missing data represents no useful information. However, missing values occur in real datasets for a variety of reasons. In metabolomics datasets a major reason for missing values is that a specific measurable phenomenon falls below the detection limits of the analytical instrumentation (left-censored values). These missing data are not missing at random, but represent potentially useful information by virtue of their "missingness" at one end of the data distribution. Methods: To include this information due to left-censored missingness, we propose the information-content-informed Kendall-tau (ICI-Kt) methodology. We develop a statistical test and then show that most missing values in metabolomics datasets are the result of left-censorship. Next, we show how left-censored missing values can be included within the definition of the Kendall-tau correlation coefficient, and how that inclusion leads to an interpretation of information being added to the correlation. We also implement calculations for additional measures of theoretical maxima and pairwise completeness that add further layers of information interpretation in the methodology. Results: Using both simulated and over 700 experimental data sets from the Metabolomics Workbench, we demonstrate that the ICI-Kt methodology allows for the inclusion of left-censored missing data values as interpretable information, enabling both improved determination of outlier samples and improved feature-feature network construction. Conclusions: We provide explicitly parallel implementations in both R and Python that allow fast calculations of all the variables used when applying the ICI-Kt methodology on large numbers of samples. The ICI-Kt methods are available as an R package and Python module on GitHub.
More Related Videos
Related Concept Videos
 01:16
Kendall's Tau Test
A τ value of +1...
 00:59
Model-Independent Approaches for Pharmacokinetic Data: Noncompartmental Analysis
One important characteristic of noncompartmental analyses is that drug exposure increases proportionally with increasing doses. This...
 00:54
Noncompartmental Analysis: Miscellaneous Pharmacokinetic Parameters
One key aspect of the noncompartmental approach is determining a drug's total clearance. This can be done by dividing the drug dose by the area under the concentration-time curve from zero to infinity. The area under the concentration-time curve represents the drug's...
 01:14
Analysis Methods of Pharmacokinetic Data: Model and Model-Independent Approaches
The model approach uses mathematical models to describe changes in drug concentration over time. Pharmacokinetic models help characterize drug behavior in patients, predict drug concentration in the body fluids, calculate optimum dosage regimens, and evaluate the risk of toxicity. However, ensuring that the model fits the experimental data accurately...
 01:20
Kendall's Coefficient of Concordance