Gradient Normalization Enables Communication-Efficient Distributed Learning Under Initialization Data Heterogeneity
Related Experiment Videos

Abstract:
Communication-efficient distributed learning has achieved remarkable progress in training large-scale deep neural networks across numerous clients. However, in heterogeneous environments-where local data distributions vary significantly-the empirical performance of many such algorithms degrades sharply. Moreover, existing theoretical analyses often depend on overly restrictive assumptions, such as bounded data heterogeneity, which may not be valid even for a single client. In this work, we introduce a general gradient normalization strategy that can be seamlessly integrated into a wide range of distributed learning algorithms, including compressed distributed stochastic gradient descent, federated averaging, and asynchronous variants. Our theoretical analysis demonstrates that this normalization technique effectively mitigates the negative impact of data heterogeneity, allowing these algorithms to achieve linear speedup rates with only requiring the boundedness of initialization data heterogeneity. Extensive numerical experiments further confirm the practical effectiveness and theoretical guarantees of our approach.
Related Concept Videos
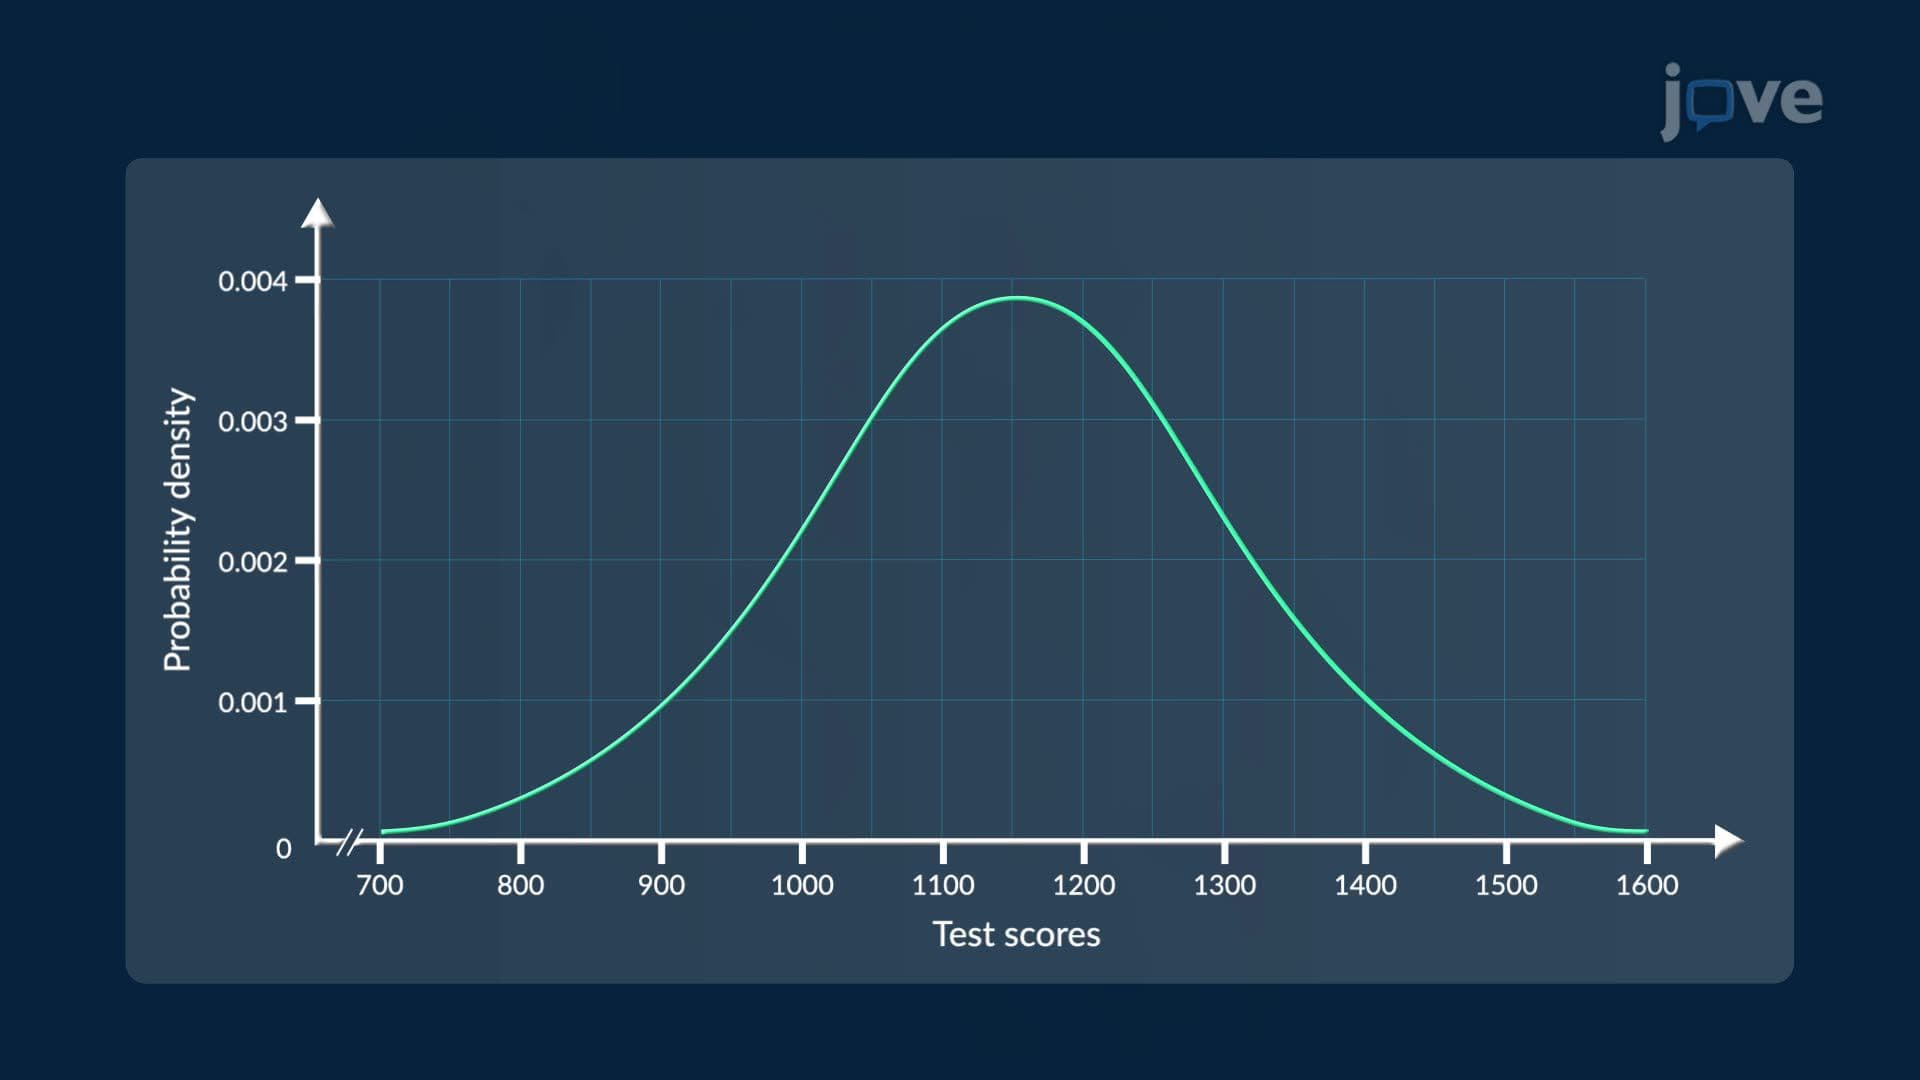 01:29
Introduction to Normal Distributions
 02:07
Improving Translational Accuracy
02:07Improving Translational Accuracy
 01:24
Generalization, Discrimination, and Extinction
Generalization occurs when a behavior reinforced in one context is performed in similar situations. For instance, a student who studies diligently for calculus and receives excellent grades might apply the same study habits to psychology and history, expecting similar results. Generalization shows how learning in one setting can influence behavior in...
 01:22
Applications of Normal Distribution
The heights of 15 to 18-year-old males from Chile from 1984 to 1985 followed a normal distribution. The mean height is 172.36...