Related Experiment Video
Updated: May 11, 2026


Augmenting Large Language Models via Vector Embeddings to Improve Domain-Specific Responsiveness
Published on: December 6, 2024
Confidence-Accuracy Alignment in Cardiology Knowledge: Comparing Medical-Specific and General-Purpose Large Language
Ali Zidan1, Mousa El-Sururi2, Avi Belbase3
1Faculty of Medicine, University of Toronto, Toronto, Ontario, Canada.

Abstract:
Large language models (LLMs) are increasingly integrated into healthcare, yet their clinical reliability depends not only on accuracy but also on confidence calibration. General-purpose models have demonstrated strong performance on medical knowledge tasks, while medical-specific models are designed to offer domain alignment. Whether specialization improves clinically meaningful reliability remains unclear. Cardiology, with its complex case-based reasoning, provides a high-stakes test domain. To compare general-purpose and medical-specific LLMs on a standardized cardiology knowledge benchmark, with emphasis on diagnostic accuracy, confidence calibration, uncertainty, and fidelity. A total of 365 text-based questions from the Adult Clinical Cardiology Self-Assessment Program (ACCSAP) were evaluated after exclusion of image-dependent items. ChatGPT-4o and Gemini 2.5 Pro represented general-purpose models, while MedGemma 27B served as a medically fine-tuned comparator. Models received a standardized structured prompt eliciting stepwise reasoning, final answer selection, and self-reported confidence, uncertainty, and fidelity. Statistical comparisons included chi-square testing, nonparametric analyses, correlation coefficients, and Brier scores for calibration. Accuracy differed significantly by model (chi-square = 58.26, p < 0.001): Gemini achieved 87% (95% CI 84% to 91%), ChatGPT 85% (81% to 89%), and MedGemma 67% (62% to 71%). All models reported high confidence, but calibration was modest. Mean confidence differed only slightly between correct and incorrect responses (absolute differences <3%). Brier scores indicated imperfect calibration (Gemini 0.115, ChatGPT 0.137, MedGemma 0.262). ChatGPT demonstrated the strongest confidence-accuracy correlation (r = 0.80, p = 0.005), while Gemini and MedGemma showed weak or nonsignificant alignment. MedGemma exhibited higher uncertainty and lower fidelity across categories. Performance varied by subspecialty, with generalist models outperforming in integrative domains. General-purpose LLMs outperformed a medical-specific model on text-based cardiology assessment, suggesting that large-scale general training may confer advantages in complex clinical reasoning. However, all models showed clinically limited confidence calibration, indicating that self-reported certainty is an unreliable indicator of correctness. Until uncertainty estimation improves, LLM use in cardiology should remain supportive and clinician-supervised.
Related Concept Videos
 02:07
Improving Translational Accuracy
02:07Improving Translational Accuracy
 01:52
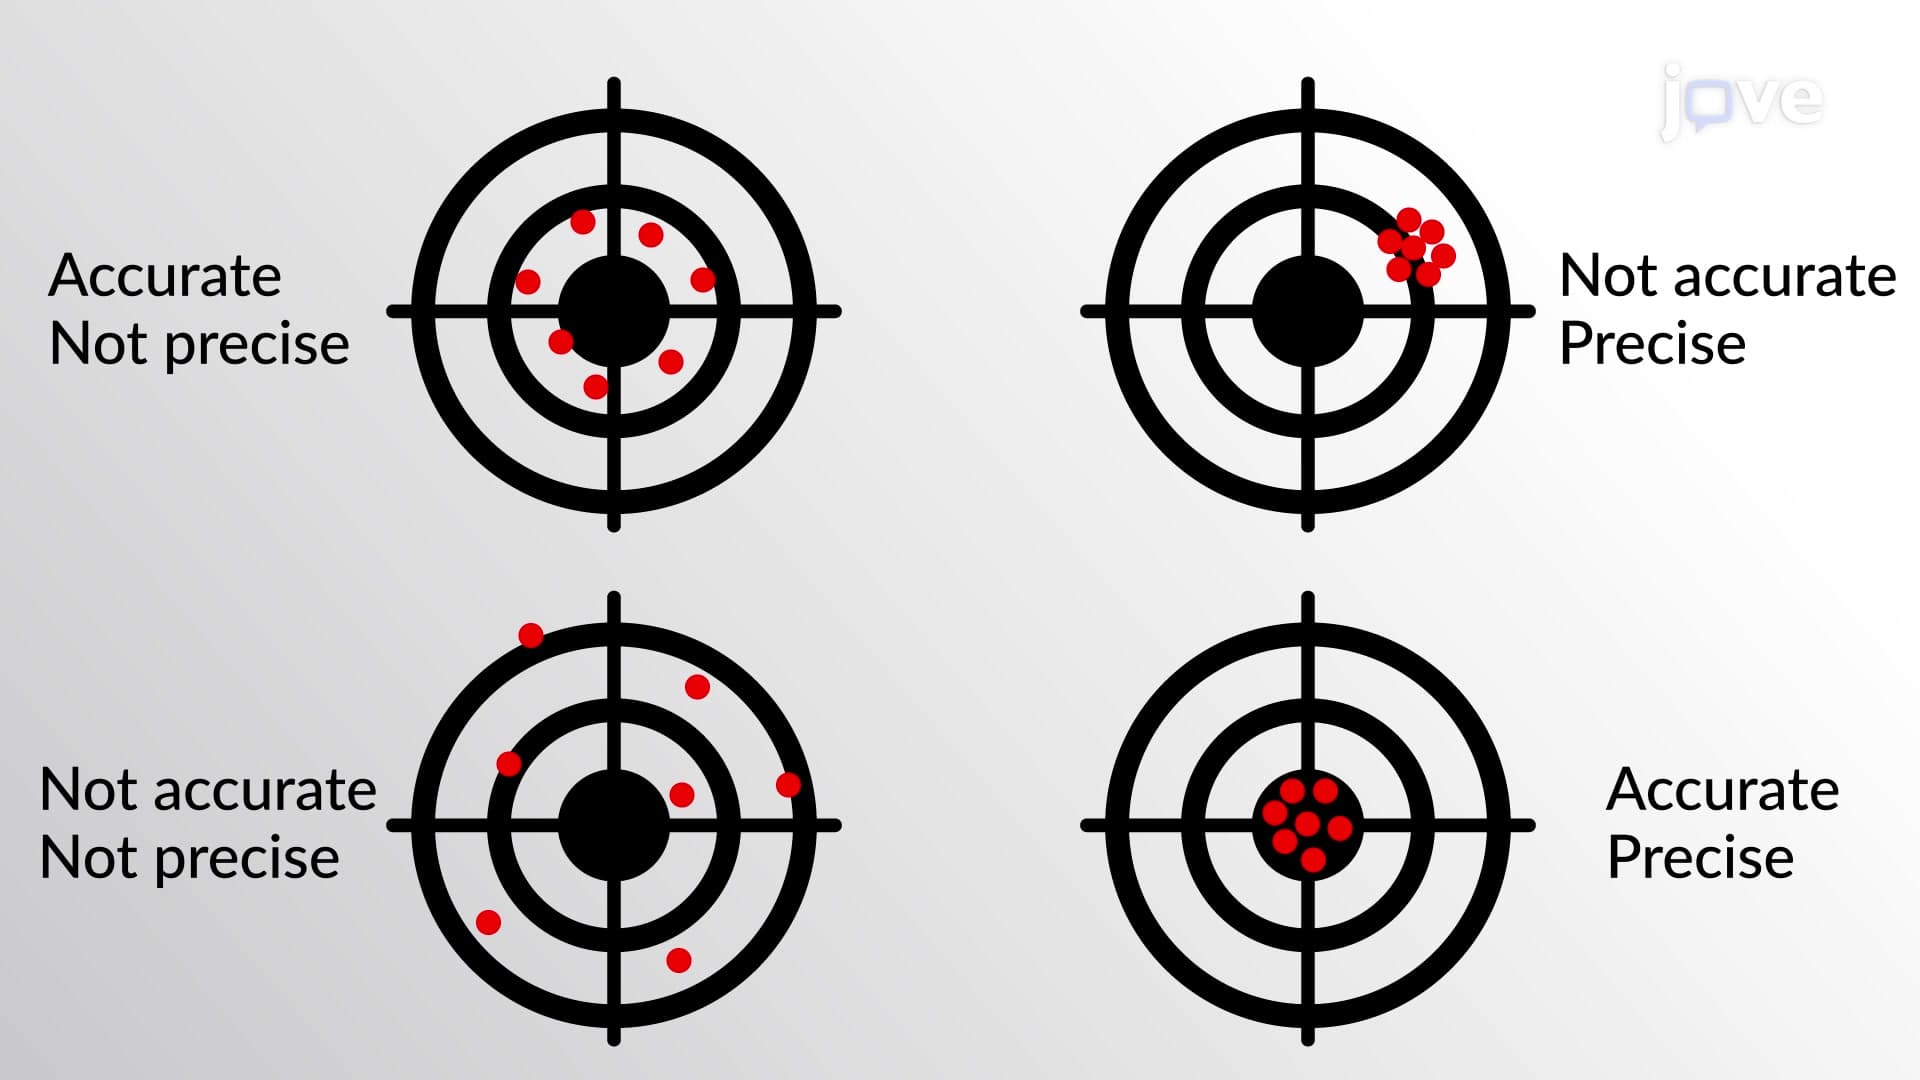
Accuracy and Precision
01:52Accuracy and Precision
 01:28
Accuracy, limits, and approximation
Accuracy is defined as the closeness of the measured value to the true or actual value. In engineering mechanics, repeated measurements are taken during theoretical or experimental analyses to ensure that the result is precise and accurate.
The accuracy of any solution is based on the...