Related Experiment Videos
FreeKD+: A Frequency Knowledge Distillation Framework for Dense Prediction

Abstract:
Knowledge distillation (KD) has been successfully applied to dense prediction tasks, and mainstream methods typically boost the student via spatial imitation losses. However, the consecutive downsamplings (e.g., existing in feature pyramid network of detectors) induced in the spatial domain are a type of distortion, hindering the student from analyzing what specific information needs to be imitated, which results in accuracy degradation. To better understand the underlying pattern of corrupted feature maps, we shift our attention to frequency knowledge distillation and propose FreeKD, which determines the optimal localization and extent for the frequency distillation. (1) Frequency Prompts in FreeKD plug into the teacher model, absorbing the semantic frequency context during finetuning. During the distillation period, a pixel-wise frequency mask is generated via Frequency Prompt, to localize those pixels of interest in various frequency bands. (2) A position-aware relational frequency loss is for dense prediction tasks, delivering a high-order spatial enhancement to the student model. While a single distillation loss might not adequately capture both high- and low-frequency signals, especially given their contextual nuances, we enhance FreeKD by introducing a frequency-decoupled strategy. This approach emphasizes relaxed alignment in the high-frequency domain and enforces stronger alignment for low-frequency features. Additionally, we refine the frequency masks by reconstructing the regions of interest based on the student's knowledge, thereby optimizing the distillation process. Extensive experimental results on the widely used COCO, VisDrone, Cityscapes, ADE20K, and COCO-C datasets demonstrate the effectiveness of our proposed framework FreeKD+.
Related Concept Videos
 01:26
Linear Approximation in Frequency Domain
In contrast, nonlinear systems do not inherently possess these properties. However, for small deviations around an operating point, a nonlinear system can often be approximated as linear.
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
The...
 01:08
Determination of Expected Frequency
 01:15
Construction of Frequency Distribution
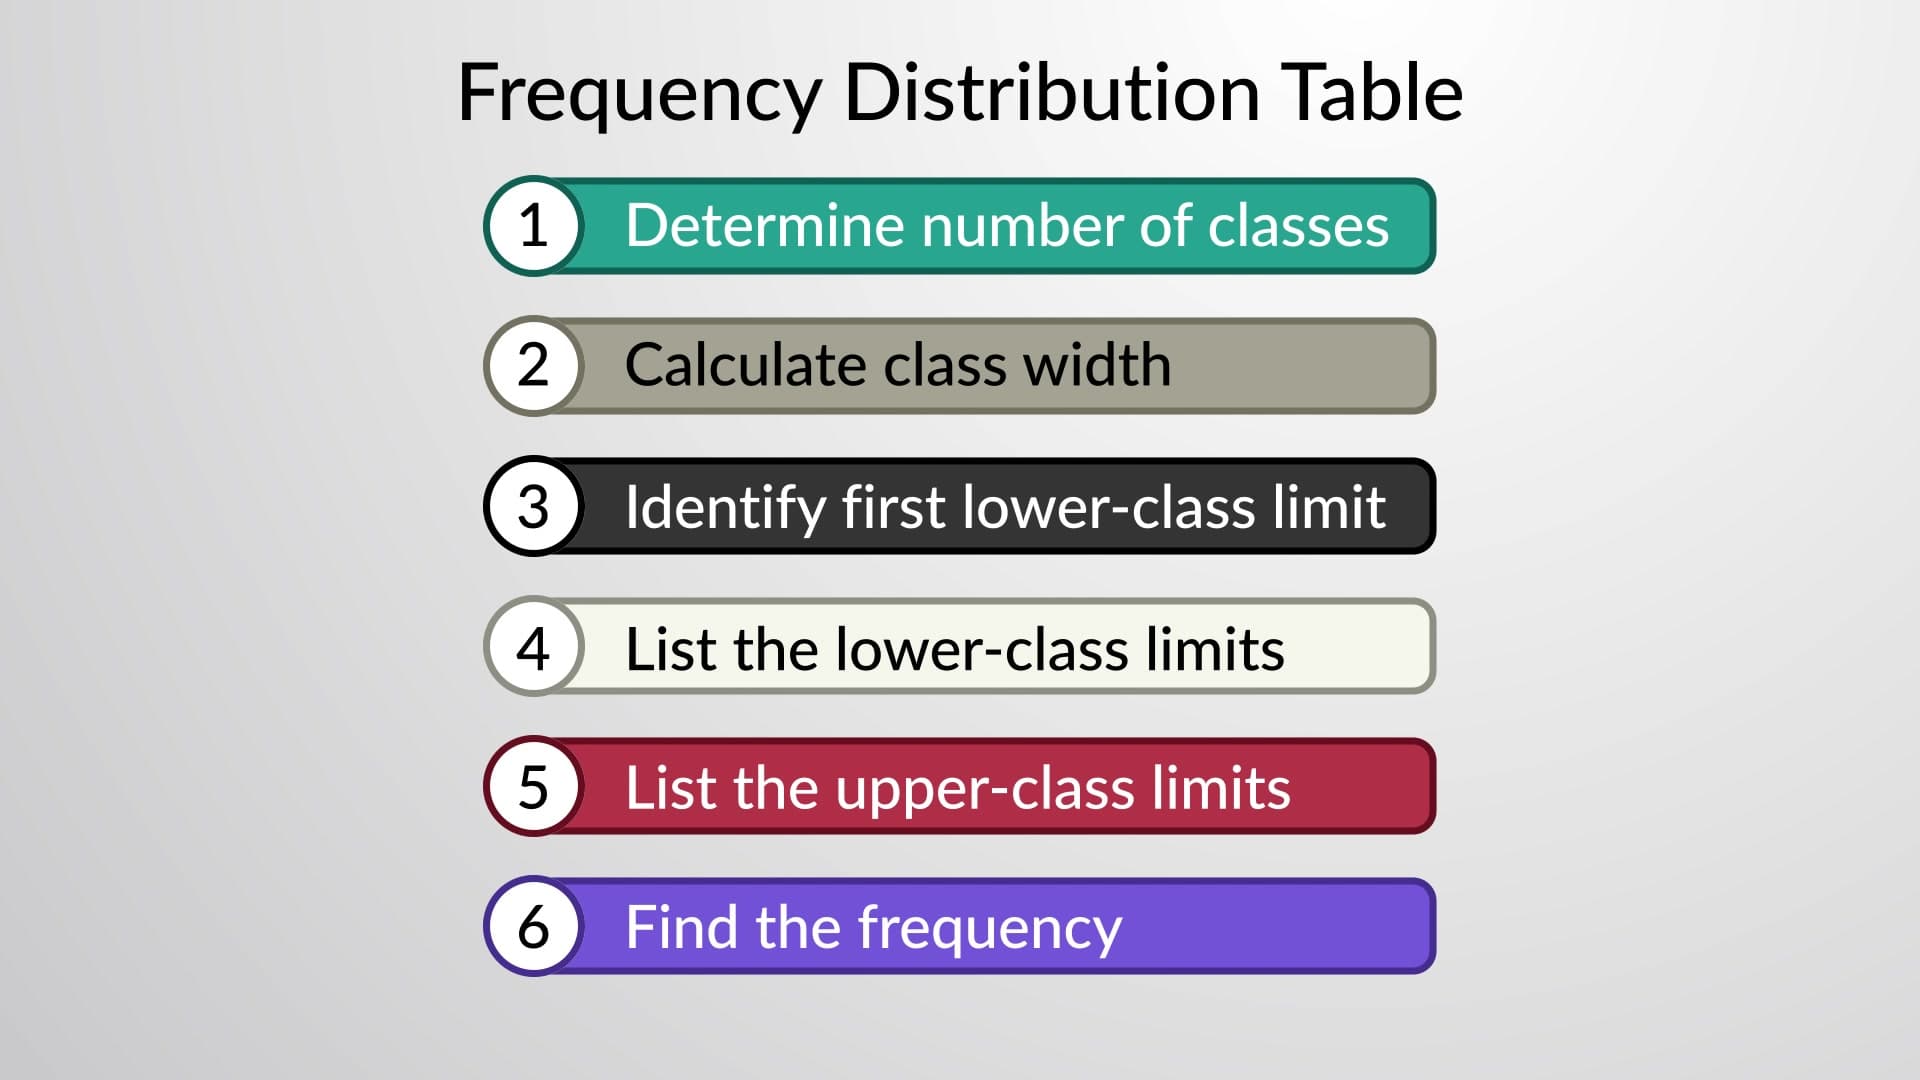
First, make a table with two columns—one with the title of the data that needs to be organized, and the other column for frequency. [Draw a third column for tally marks if needed]. Then, take a look at the items given in the data set and decide if an ungrouped frequency distribution table or a grouped frequency distribution table would be more suitable. If there are large sets of different values, then it is best to...
 01:21
Frequency-dependent Selection
 00:55
Relative Frequency Distribution