

Handling missing data, skewness, and outliers in medical research: A robust factor analysis approach using the
Wan-Lun Wang1, Luis M Castro2,3, Tsung-I Lin4,5
1Department of Statistics and Institute of Data Science, National Cheng Kung University, Tainan, Taiwan.

Abstract:
Addressing incomplete and non-normally distributed multivariate data poses significant challenges in medical research, particularly when the interest is in discovering underlying data structures. This article introduces a robust factor analysis framework for handling missing data by employing the canonical fundamental skew- factor analysis (CFUSTFA) model, which incorporates the canonical fundamental skew- distribution into the latent factors and error terms. This versatile framework accounts for skewness, heavy tails, and missing data, thereby enhancing the model's ability to capture complex structures commonly observed in biomedical datasets. For parameter estimation under the missing at random mechanism, we develop a computationally efficient alternating expectation-conditional maximization algorithm within the maximum likelihood framework. This approach facilitates the simultaneous imputation of missing values and the extraction of low-dimensional factor representations. Standard errors for parameter estimates are also derived using a general information matrix-based approach. The proposed methodology is validated through simulations and applied to a hepatitis C virus laboratory dataset exhibiting skewness, excess kurtosis, and missingness. Our findings highlight the capability of the CFUSTFA model to robustly capture complex, incomplete, and asymmetric biomedical data, offering enhanced inference and interpretability compared with existing factor analysis approaches.
Related Concept Videos
 01:06
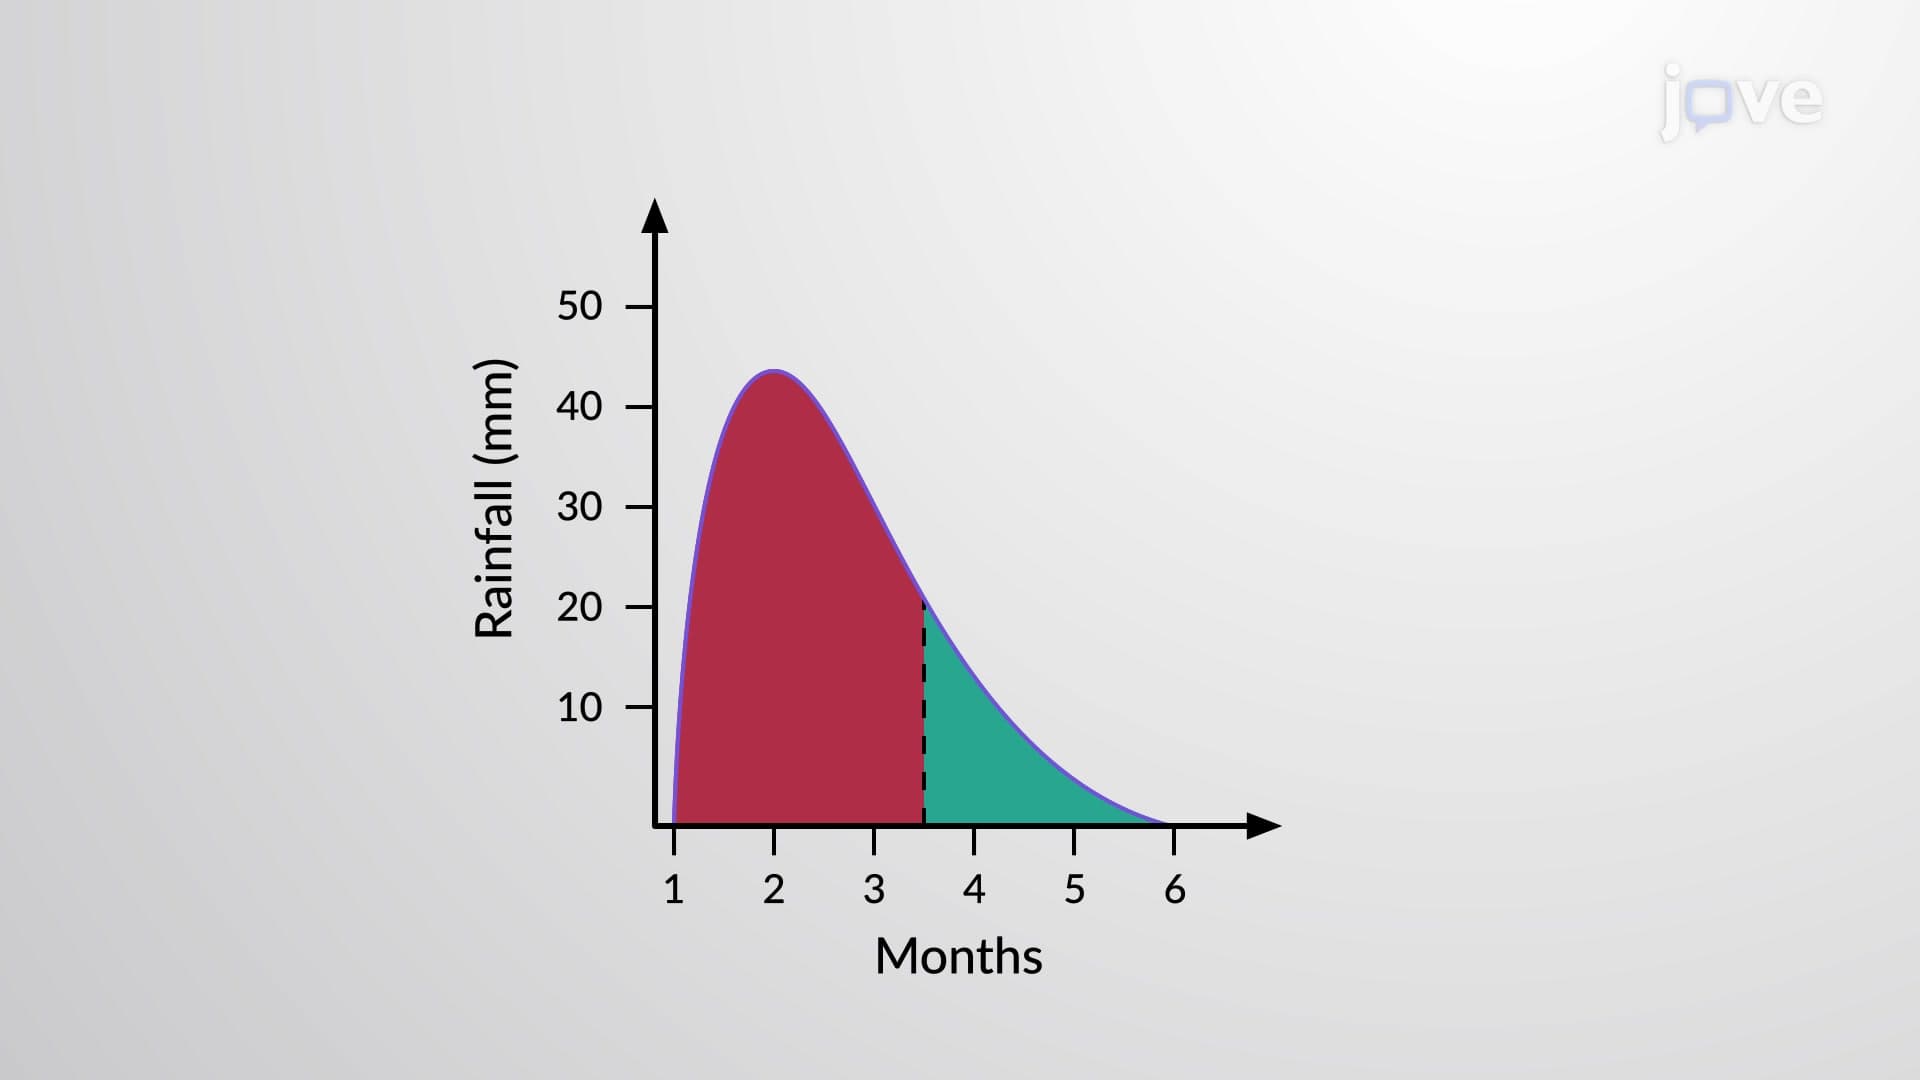
Skewness
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency are...
 01:09
Types of Skewness
For instance, in the middle of a pandemic, the geographical distribution of vaccine coverage may be positively skewed towards populations in the global north countries. However,...
 01:19
Data: Types and Distribution
Distributions in...
 01:24
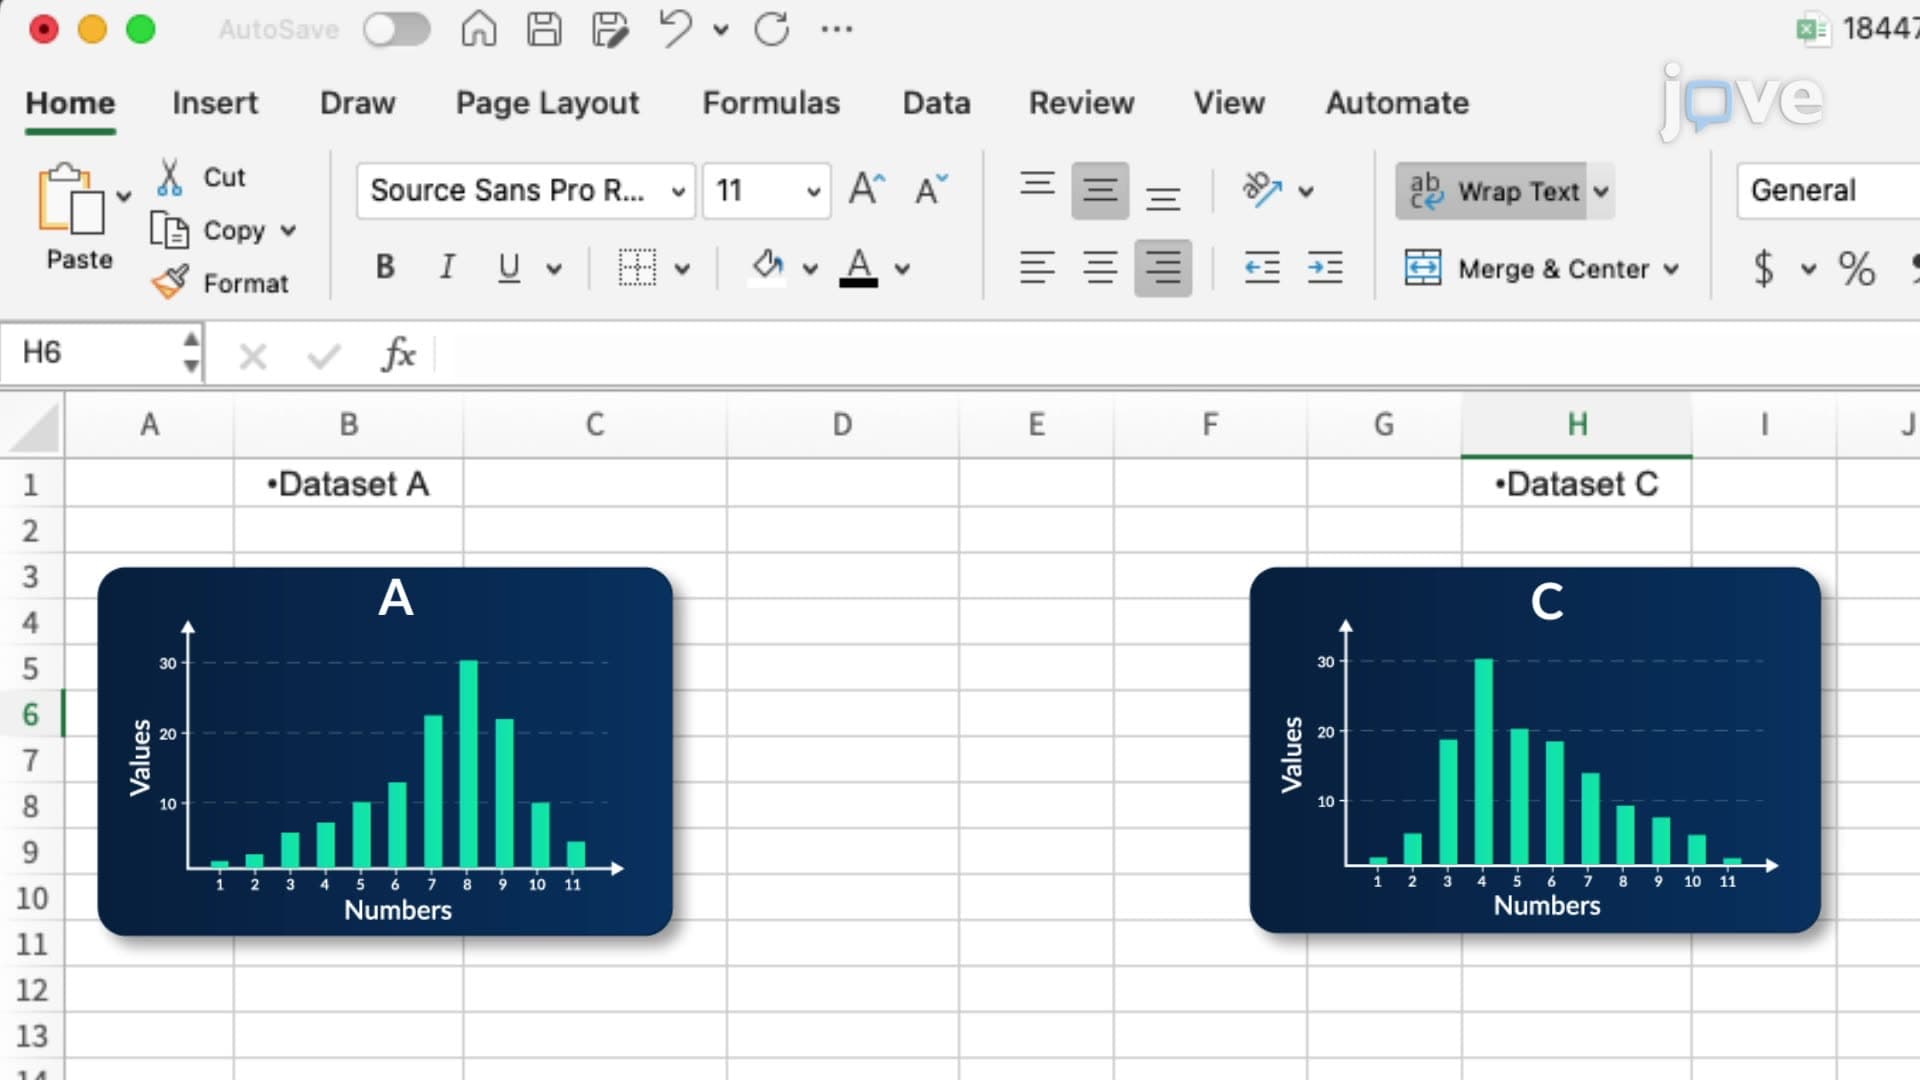
Microsoft Excel: Finding Central Tendency, Skew, and Kurtosis
Mean: The arithmetic average of all data points. It is calculated by adding all the values together and dividing by the number of values. The mean is sensitive to extreme values (outliers).
Median: The middle value when the data points are arranged in ascending or descending...
 00:57
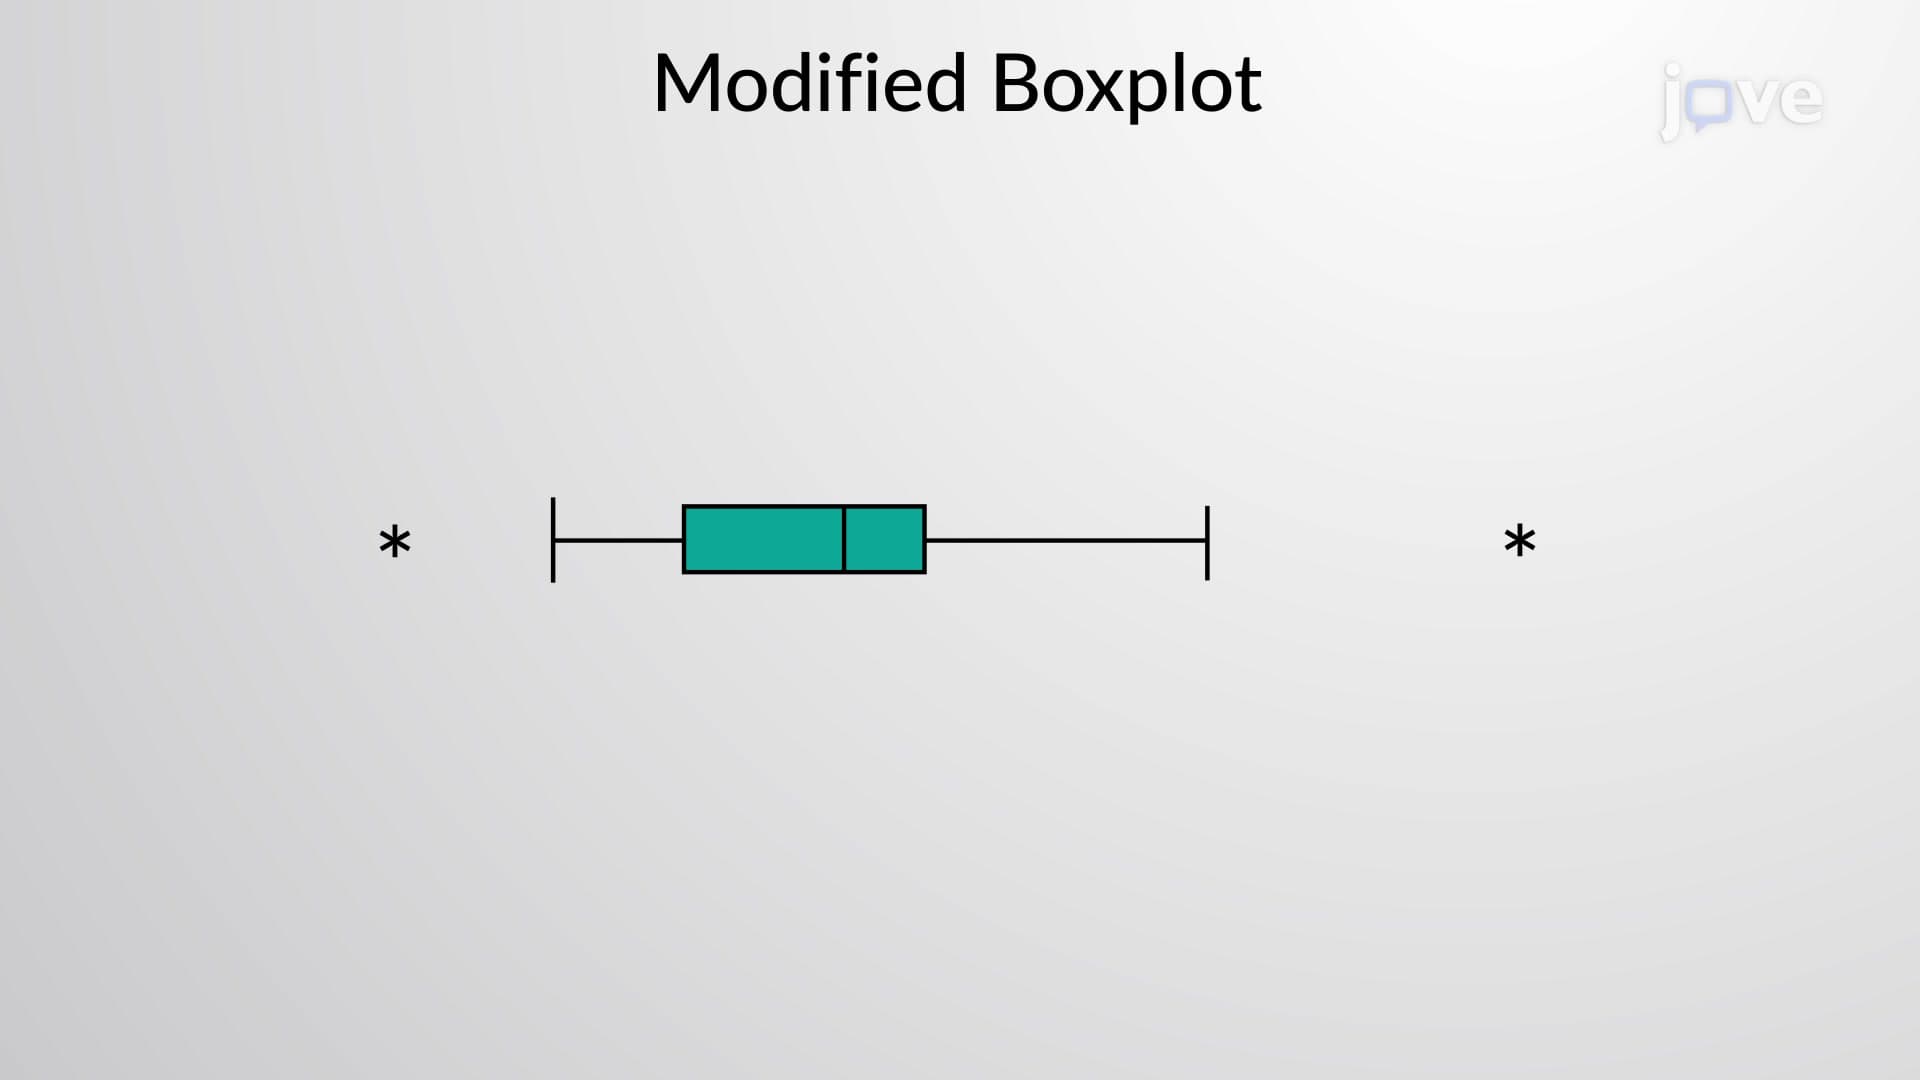
Modified Boxplots
However, the box plot does not tell the reader about outliers - values that lie far from the center of the data. We can modify the standard box and whisker plot to identify the outliers and visualize the actual spread of the data in a sample.
Initially, we calculate the adjusted...
 01:00
Detection of Gross Error: The Q Test