Related Experiment Video
Updated: May 22, 2026

Lexical Decision Task for Studying Written Word Recognition in Adults with and without Dementia or Mild Cognitive Impairment
Published on: June 25, 2019
Common TF-IDF variants arise as key components in the test statistic of a penalized likelihood-ratio test for word
Zeyad Ahmed1, Paul Sheridan1, Michael McIsaac1
1School of Mathematical and Computational Sciences, University of Prince Edward Island, 550 University Ave, Charlottetown, C1A 4P3 PE Canada.

Abstract:
TF-IDF is a classical formula that is widely used for identifying important terms within documents. We show that TF-IDF-like scores arise naturally from the test statistic of a penalized likelihood-ratio test setup capturing word burstiness (also known as word over-dispersion). In our framework, the alternative hypothesis captures word burstiness by modeling a collection of documents according to a family of beta-binomial distributions with a gamma penalty term on the precision parameter. In contrast, the null hypothesis assumes that words are binomially distributed in collection documents, a modeling approach that fails to account for word burstiness. We find that a term-weighting scheme given rise to by this test statistic performs comparably to TF-IDF on document classification tasks. This paper provides insights into TF-IDF from a statistical perspective and underscores the potential of hypothesis testing frameworks for advancing term-weighting scheme development.
Related Concept Videos
 01:19
Expected Frequencies in Goodness-of-Fit Tests
 01:04
Significance Testing: Overview
 01:14
Identifying Statistically Significant Differences: The F-Test
 01:22
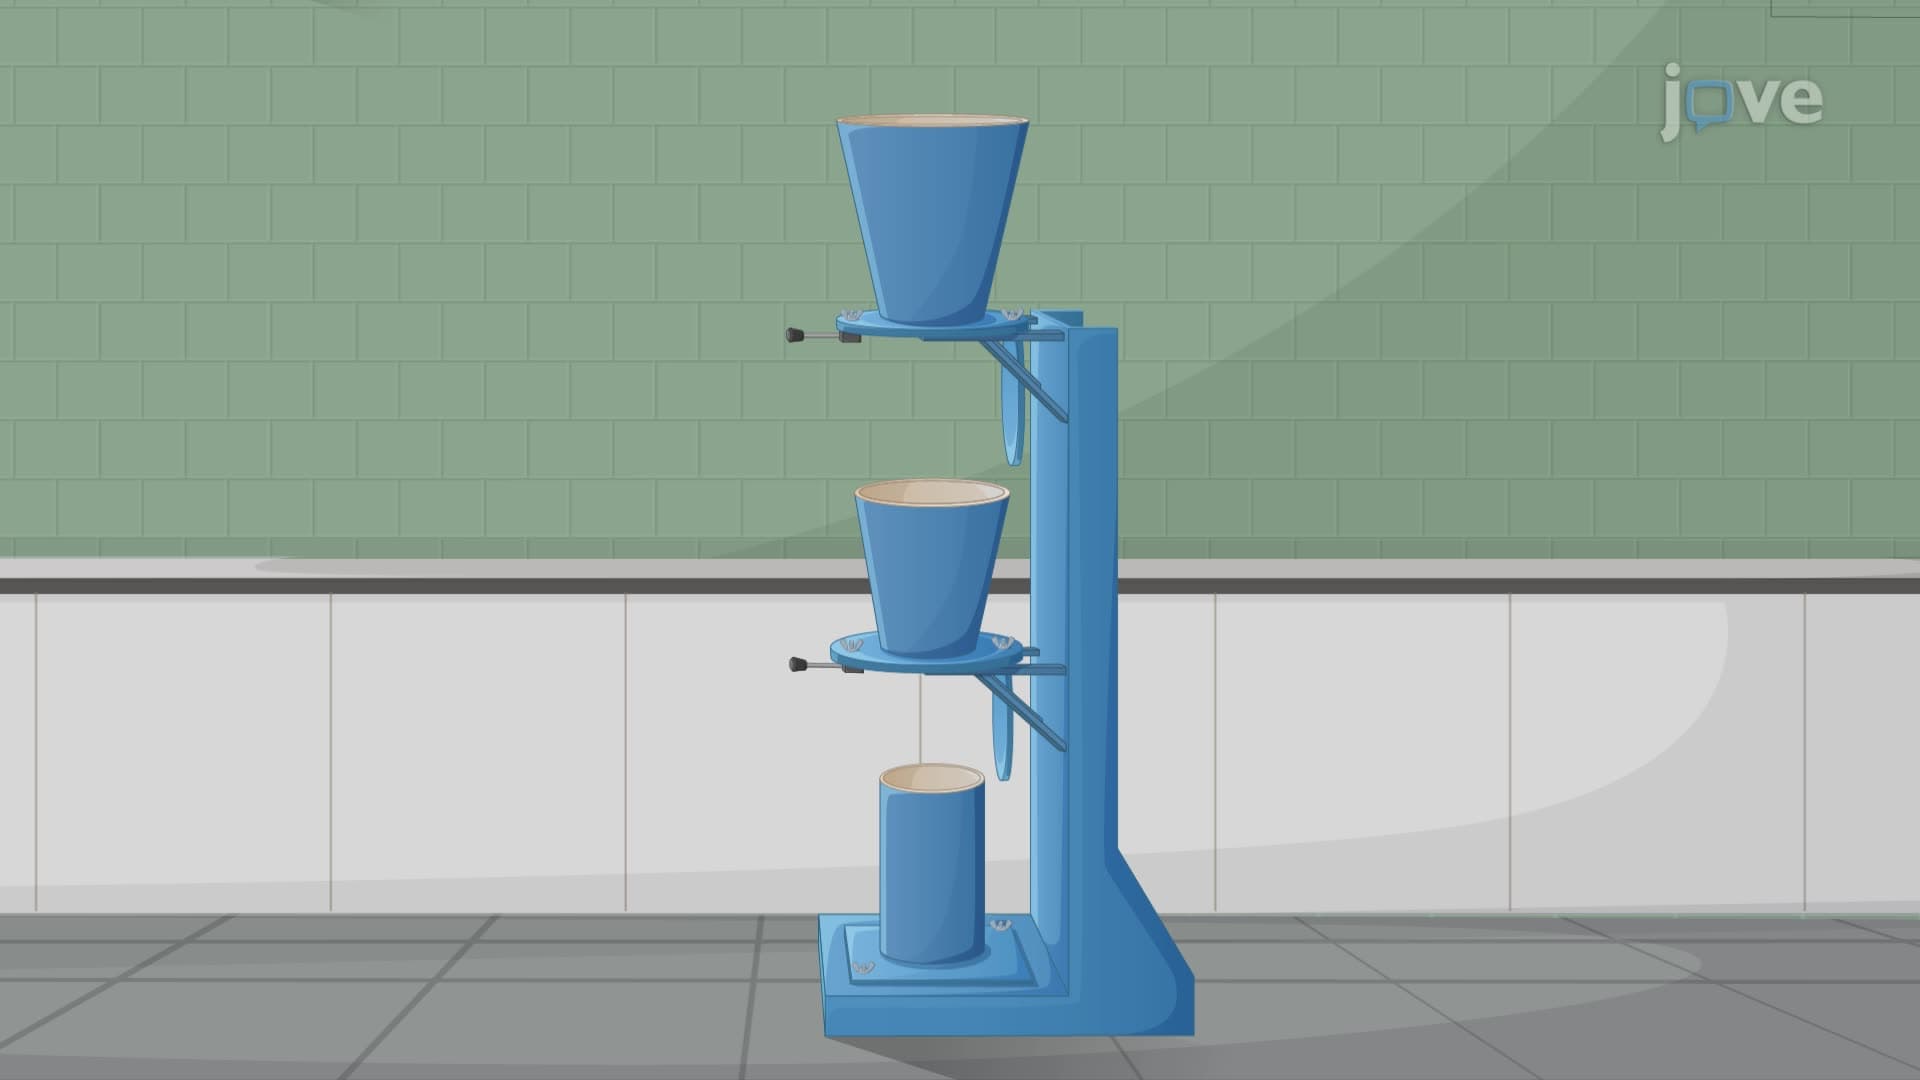
Compacting Factor test
The procedure begins by placing concrete into the upper hopper without any compaction. Once filled, the bottom door of this hopper is opened,...
 01:10
Bonferroni Test
The means of different samples are first paired in all possible combinations.
The null hypothesis of the...
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test