Related Experiment Videos
TextEconomizer: Enhancing lossy text compression with denoising transformers and entropy coding
Mahbub E Sobhani1, Anika Tasnim Rodela1, Chowdhury Mofizur Rahman2
1United International University, Department of Computer Science and Engineering, Dhaka, Bangladesh.

Abstract:
Lossy text compression reduces data size while preserving core meaning, making it well-suited for tasks like summarization, automated analysis, and digital archives where exact fidelity is less critical. Despite the dominance of transformer-based models in language modeling, the integration of context vectors and lossless entropy coding into Sequence-to-Sequence (Seq2Seq) text generation remains underexplored. A key challenge lies in identifying the most informative context vectors from the encoder output and incorporating entropy coding into the transformer framework to enhance storage efficiency while maintaining high-quality outputs, even in the presence of noisy text. Previous studies have primarily focused on near-lossless token generation, often overlooking space efficiency. In this paper, we introduce TextEconomizer, an encoder-decoder framework paired with a transformer neural network. This framework utilizes its latent representation to reduce variable-sized inputs by 50% to 80%, without prior knowledge of dataset dimensions. Our model achieves competitive compression ratios by incorporating entropy coding, while delivering near-perfect text quality, as assessed by Bilingual Evaluation Understudy (BLEU), Recall-Oriented Understudy for Gisting Evaluation (ROUGE), Metric for Evaluation of Translation with Explicit ORdering (METEOR), and semantic similarity scores. Notably, TextEconomizer operates with approximately 153 times fewer parameters than comparable models, achieving a compression ratio of 5.39 × without sacrificing semantic quality. Additionally, we evaluate our framework by implementing a Long Short-Term Memory (LSTM)-based autoencoder, commonly used in image compression, and by integrating advanced modules within the transformer architecture as alternatives to conventional techniques. Our autoencoder achieves a state-of-the-art compression ratio of 67 × with 196 times fewer parameters, while our modified transformer, LLaMAFormer, achieves a 263-fold reduction in parameters compared to ICAE while maintaining competitive text quality. The TextEconomizer framework significantly surpasses existing transformer-based models in balancing memory efficiency and high-fidelity outputs, marking a breakthrough in lossy compression with optimal space utilization.
Related Concept Videos
 01:21
Energy Losses in Transformers
There are four main reasons for energy losses in transformers.
The first cause can be the high resistance of the copper windings...
 01:18
Reducing Line Loss
With a step-up transformer at the source, the voltage is increased, thereby reducing the current in the transmission lines since power loss in...
 01:20
Downsampling
The Fourier transform of the decimated sequence reveals a combination of scaled and shifted versions of the original spectrum. This...
 01:22
Lossy Lines and Overvoltages
Attenuation
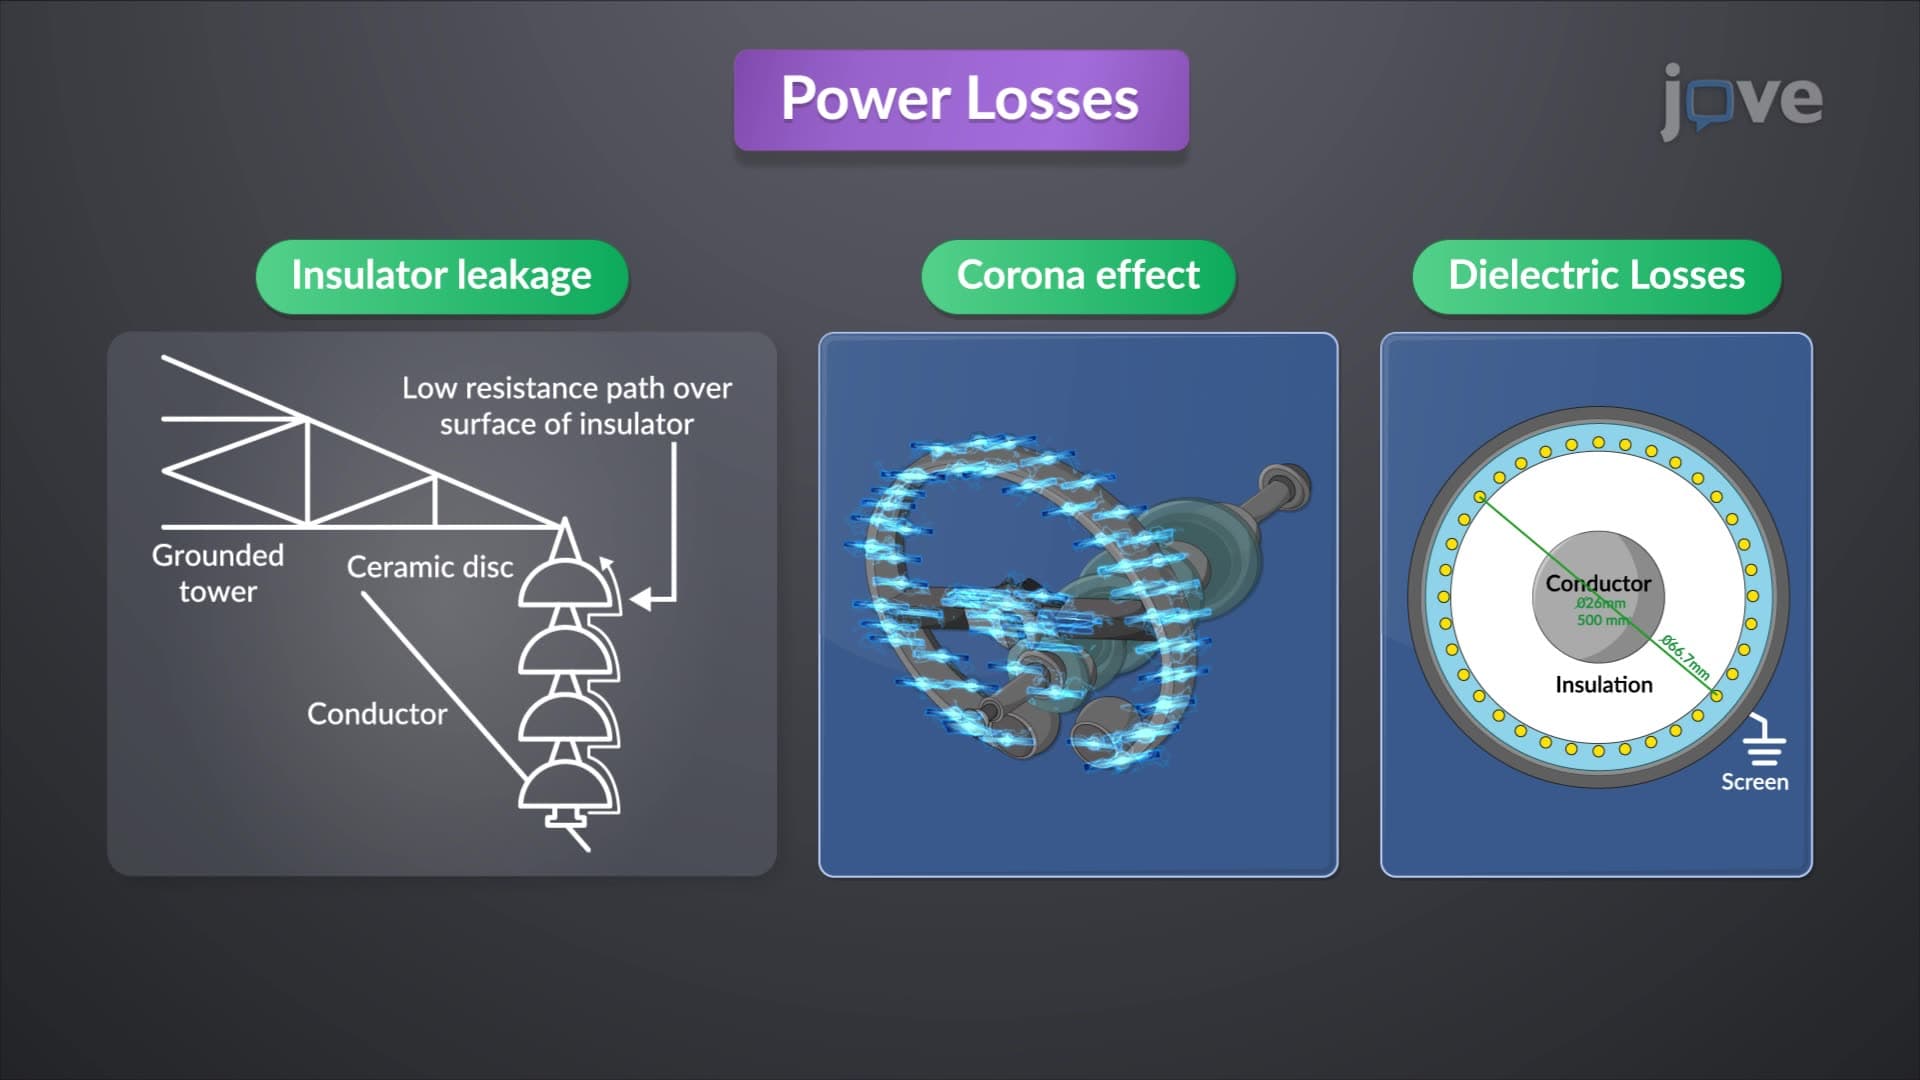
When constant series resistance and shunt conductance are present, voltage and current equations are modified. The propagation constant indicates that voltage and current waves consist of both forward and backward traveling components. These waves attenuate as they propagate, with the attenuation factor related to the resistance and conductance. In a...
 01:20
Entropy and the Second Law of Thermodynamics
The relation between entropy and disorder can be illustrated with the example of the phase change of ice to water. In ice, the molecules are located at specific sites giving a solid state, whereas, in a liquid form, these molecules are much freer to move. The molecular arrangement has therefore become more randomized. Although the change in average...
 01:26
Entropy and the Second Law of Thermodynamics