Related Experiment Video
Updated: Jun 14, 2026
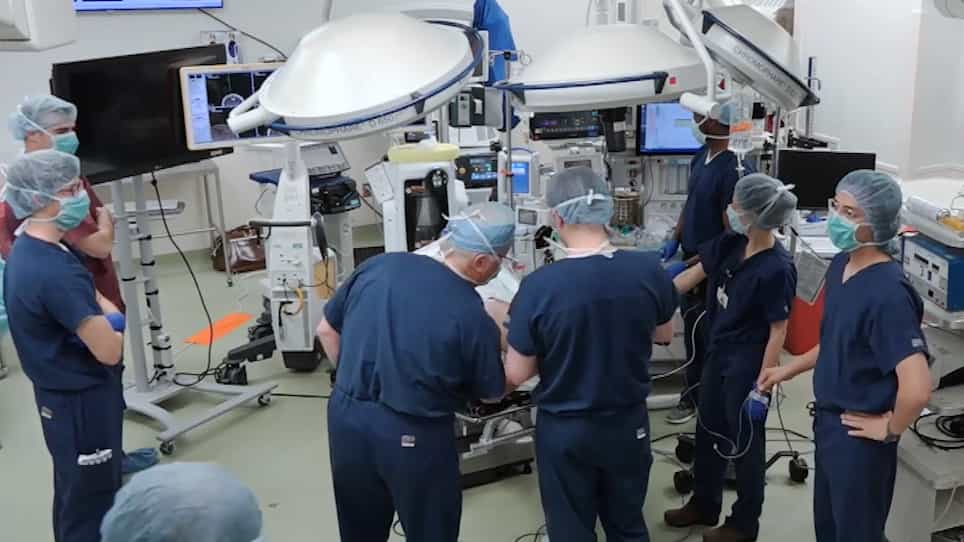
Translational Brain Mapping at the University of Rochester Medical Center: Preserving the Mind Through Personalized Brain Mapping
Published on: August 12, 2019
An exploratory study of large language models in preoperative anesthesia assessment and planning for cardiac patients
Jianfan Ping1, Yuanming Pan1, Shuhan Gu1
1Department of Anesthesiology, the First Affiliated Hospital, Zhejiang University School of Medicine, Hangzhou, Zhejiang, 310003, P.R. China.

Background:
With the rapid advancement of large language models (LLMs) in clinical applications, the potential role of LLMs in perioperative anesthesia assessment has garnered increasing research interest. This study aimed to systematically compare the performance, specifically accuracy and inter-model consistency of the three LLMs-ChatGPT, DeepSeek, and Grok-in performing preoperative anesthesia assessments and formulating anesthesia plans for cardiac patients undergoing noncardiac surgery, and to evaluate their agreement with an expert consensus panel.
Methods:
Forty-one consecutive patients with a history of severe cardiac disease, presented as standardized clinical vignettes derived from real medical records, were evaluated by the three LLMs, ChatGPT, DeepSeek, and Grok. Their outputs were compared against a structured reference standard derived from an expert consensus panel of five senior anesthesiologists. Agreement and accuracy were analyzed using Krippendorff's α and Cohen's κ coefficients, supplemented by qualitative thematic analysis.
Results:
DeepSeek achieved the highest accuracy in ASA classification (73.2%), followed by Grok (70.7%) and ChatGPT (58.5%). For the NYHA functional classification and RCRI scoring, Grok attained the highest accuracy in both tasks (75.6% for each), whereas ChatGPT exhibited the lowest accuracy (46.3%). In pulmonary risk assessment, Grok (80.5%) and DeepSeek (78.0%) outperformed ChatGPT (51.2%). Inter-model and model-expert agreement varied across the different assessment tasks, ranging from slight to substantial. All models exhibited a strong preference for recommending general anesthesia (≥ 85%) and consistently overemphasized invasive blood pressure (IBP) and central venous pressure (CVP) monitoring, while none mentioned bispectral index (BIS) monitoring.
Conclusions:
This exploratory study reveals that current LLMs exhibit suboptimal concordance with expert consensus in preoperative planning for complex cardiac cases. Although not ready for direct clinical application, their structured, rule-informed reasoning framework may serve as a supplementary checklist or second-opinion generator under expert supervision. Future multicenter validation studies incorporating diverse, high-quality datasets and standardized clinical endpoints are warranted to refine model training, improve generalizability, and substantiate clinical utility.
Related Concept Videos
 01:28
Cardiomyopathy VII: Pre and Post Operative Nursing Management
 01:24
General Anesthesia: Overview
General anesthesia induces unconsciousness in the whole body, while the others target specific areas or sensations. It is administered to minimize adverse effects, maintain...