Related Experiment Video
Updated: Jul 1, 2026


Large-scale Reconstructions and Independent, Unbiased Clustering Based on Morphological Metrics to Classify Neurons in Selective Populations
Published on: February 15, 2017
A robust neural network with random effects for subject-specific prediction of clustered count data
Hangbin Lee1, Il Do Ha2, Changha Hwang3
1Department of Information and Statistics, Chungnam National University, Daejeon, Republic of Korea.

Abstract:
There is a growing interest in subject-specific predictions using neural networks, as large-scale biomedical data often exhibit dependency due to high-cardinality categorical features, which have been largely overlooked by traditional neural network frameworks. This article proposes a novel hierarchical likelihood learning framework that captures both nonlinear overall effects and subject-specific effects by incorporating gamma random effects into Poisson neural networks. The global maximizer of the proposed objective function yields maximum likelihood estimators for fixed parameters and best unbiased predictors for random effects. The proposed framework provides a robust end-to-end algorithm for clustered biomedical count data, in the sense that the corresponding estimating equations remain unbiased even when the random-effects distribution is misspecified. To enhance learning efficiency, we introduce an adjustment procedure for the random effects and variance component. Extensive simulation studies and real data analyses demonstrate the practical effectiveness of the proposed method for clustered biomedical count data. The proposed method achieves competitive predictive performance in terms of mean squared Pearson error and mean deviance across various random-effects distributions and real-world datasets.
Related Concept Videos
 01:13
Randomized Experiments
Simple randomization
Simple...
 01:09
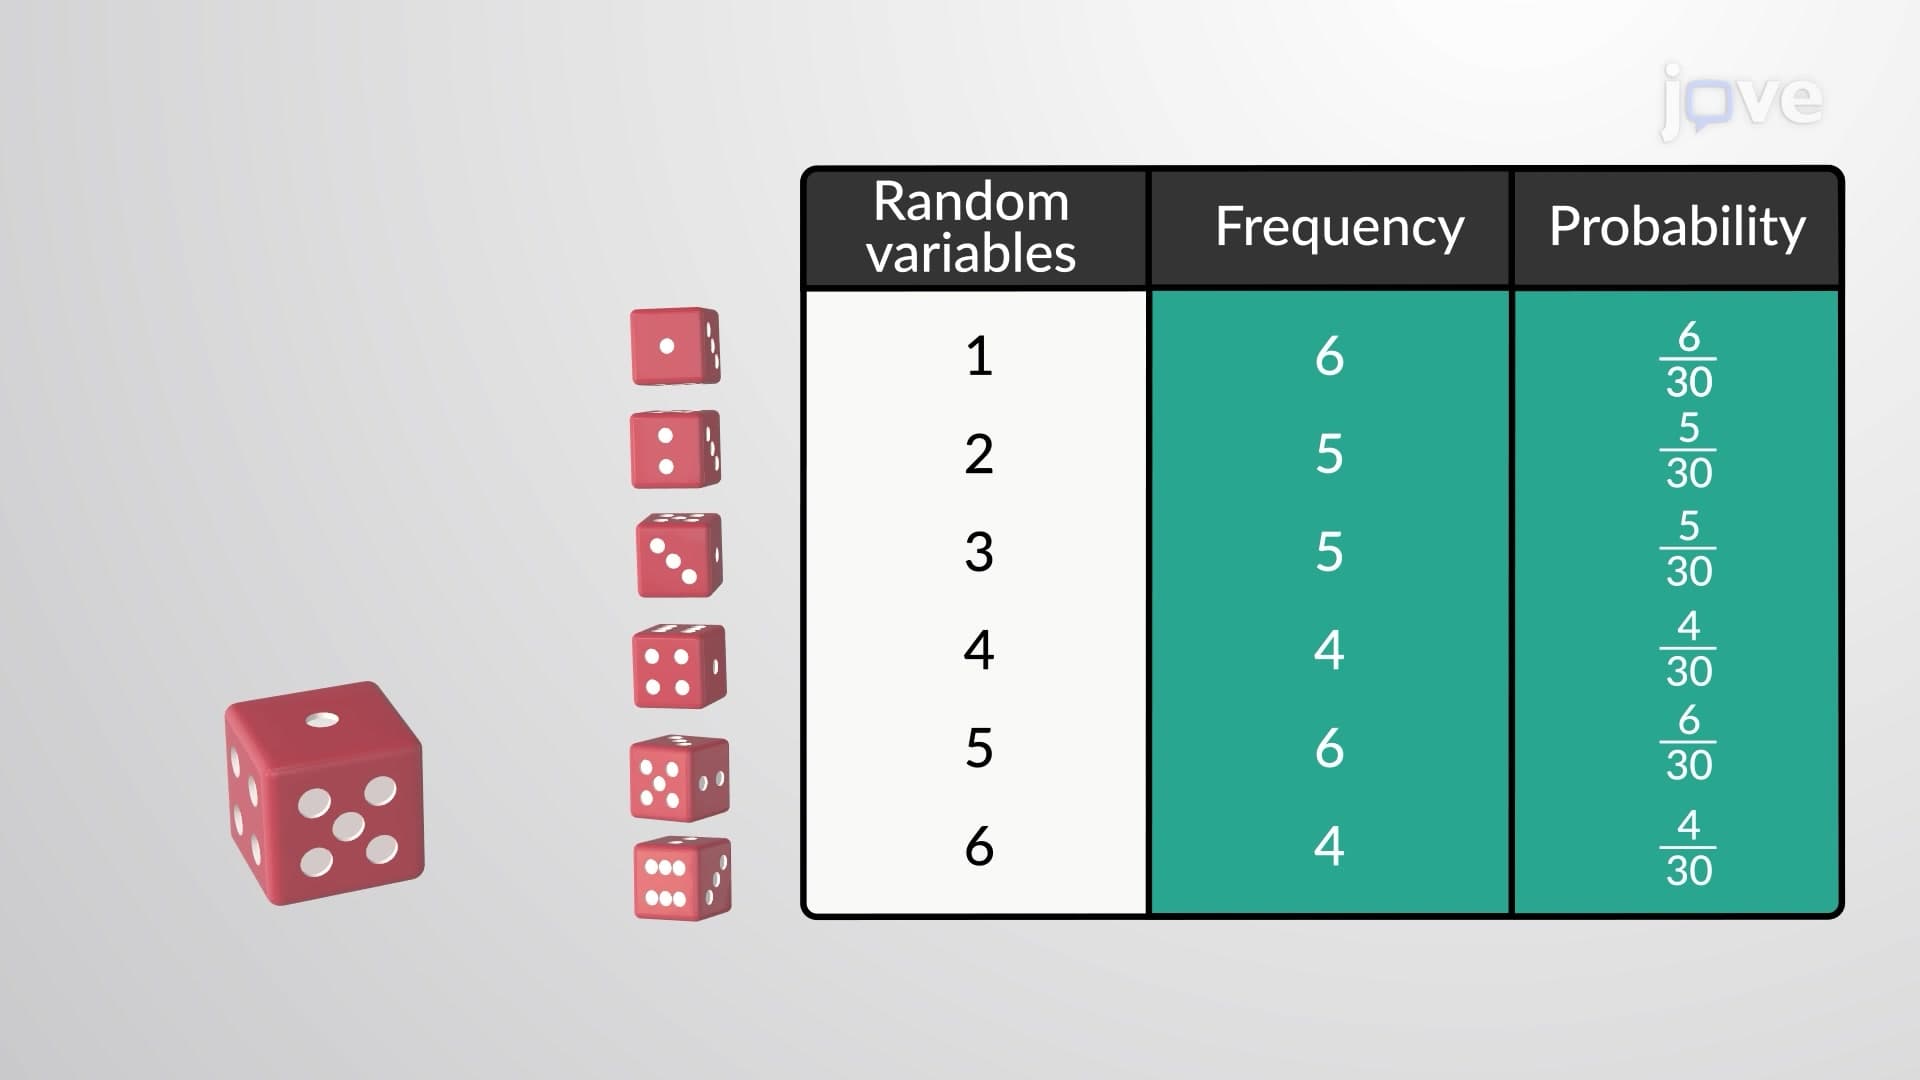
Random Variables
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
The...
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:09
Random Sampling Method