Related Experiment Video
Updated: Jul 2, 2026
10:39

Qualitative and Quantitative Validation of Tools with Rating Scales Aimed at Assessing the Quality of University Service-Learning
Published on: August 29, 2025
Analysis of Item-Level Disagreement Between Researchers and ChatGPT on the PEDro Scale for Assessing the
Juan Antonio Valera-Calero1, Germán Monclús-Díez1, Isidro Fernández-López1
1Department of Physiotherapy, Universidad Complutense de Madrid, Madrid, Spain.
Journal of Evidence-Based Medicine
|July 1, 2026

Abstract
No abstract available in PubMed .
Related Concept Videos
 01:15
Systematic Error: Methodological and Sampling Errors
In the case of systematic errors, the sources can be identified, and the errors can be subsequently minimized by addressing these sources. According to the source, systematic errors can be divided into sampling, instrumental, methodological, and personal errors.
Sampling errors originate from improper sampling methods or the wrong sample population. These errors can be minimized by refining the sampling strategy. Defective instruments or faulty calibrations are the sources of instrumental...
Sampling errors originate from improper sampling methods or the wrong sample population. These errors can be minimized by refining the sampling strategy. Defective instruments or faulty calibrations are the sources of instrumental...
 01:17
Cochran's Q Test
Cochran's Q Test is a nonparametric statistical test used to determine if there are potential differences in the outcomes of three or more related groups on a binary (yes/no) or dichotomous outcome. It is essentially an extension of the McNemar Test, which is limited to two related samples - Cochran's Q test can handle three or more related samples, making it more versatile in scenarios where subjects are measured under multiple conditions. The test statistic follows a Chi-Square distribution,...
 01:13
Accuracy and Errors in Hypothesis Testing
Hypothesis testing is a fundamental statistical tool that begins with the assumption that the null hypothesis H0 is true. During this process, two types of errors can occur: Type I and Type II. A Type I error refers to the incorrect rejection of a true null hypothesis, while a Type II error involves the failure to reject a false null hypothesis.
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5% chance...
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5% chance...
 01:09
Empirical Method to Interpret Standard Deviation
The empirical rule, also known as the three-sigma rule, allows a statistician to interpret the standard deviation in a normally distributed dataset. The rule states that 68% of the data lies within one standard deviation from the mean, 95% lies within two standard deviations from the mean, and 99.7% lies within three standard deviations from the mean. Additionally, this rule is also called the 68-95-99.7 rule.
This rule is used widely in statistics to calculate the proportion of data values...
This rule is used widely in statistics to calculate the proportion of data values...
 01:09
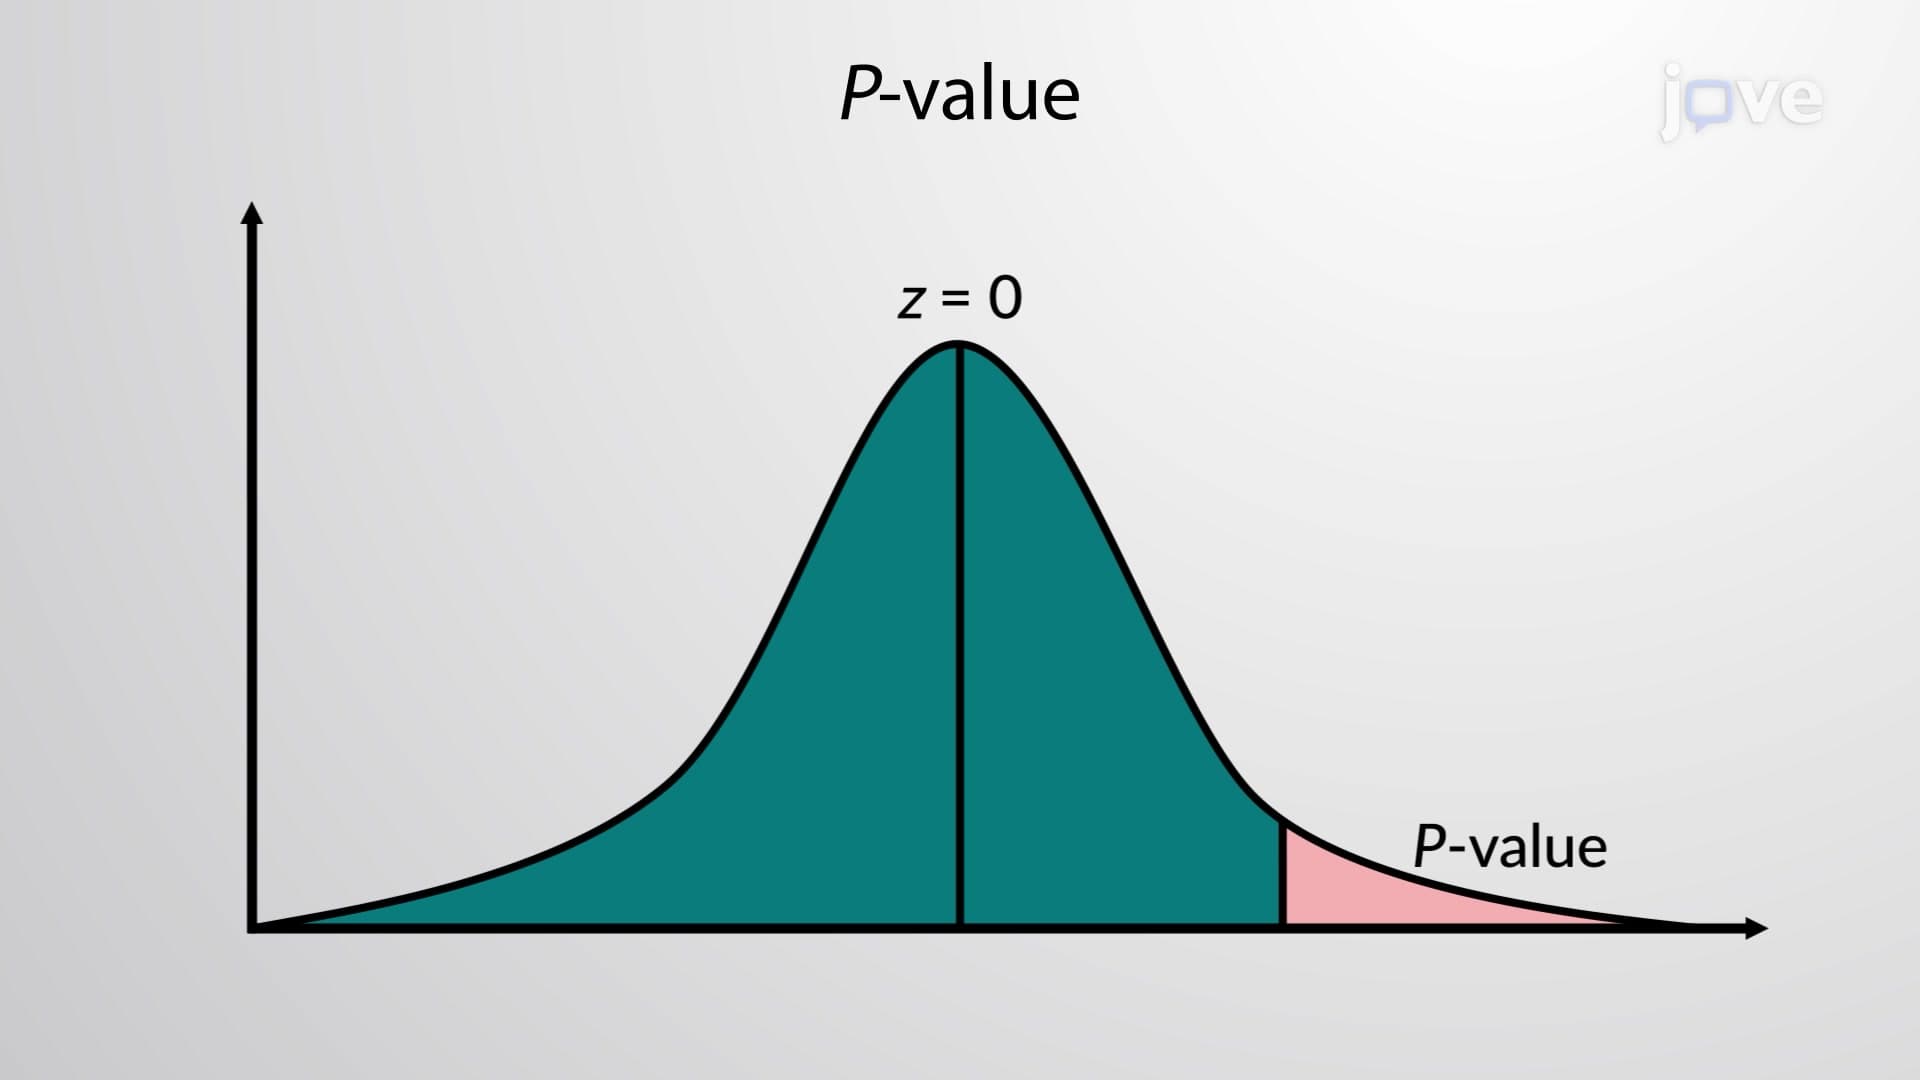
Decision Making: P-value Method
The process of hypothesis testing based on the P-value method includes calculating the P- value using the sample data and interpreting it.
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can have a...
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can have a...
 01:21
Friedman Two-way Analysis of Variance by Ranks
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures from...