Related Experiment Video
Updated: Jul 2, 2026
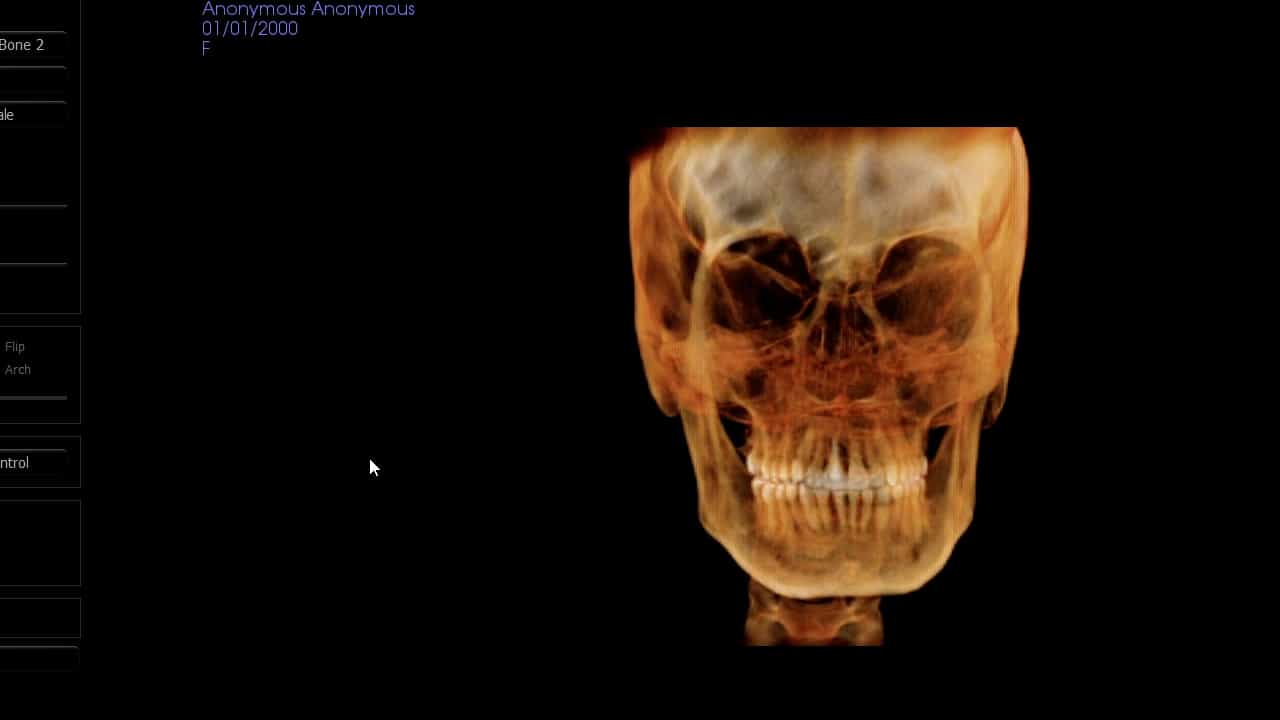

Three-Dimensional Cephalometric Landmark Annotation Demonstration on Human Cone Beam Computed Tomography Scans
Published on: September 8, 2023
Synthetic data augmentation for improving performance in deep learning models for anatomical landmark localization on
Prathiksha Padmanabha1, Kasunika Guruge1, H M K K M B Herath1
1Industry 4.0 Convergence Bionics Engineering, Pukyong National University, Busan, Republic of Korea.

Abstract:
Precise anatomical landmark localization is critical for the therapeutic efficacy of Traditional Eastern Medicine, yet manual localization methods show inter-practitioner variability exceeding 5 mm. Deep learning can automate this process, but data scarcity limits model development. MetaHuman-rendered synthetic images offer a scalable alternative, though their texture fidelity and architecture-specific training effects remain underexplored. Six landmark localization models (HRNet-W32/W48; YOLO26-pose: small/medium/large/extra-large) were trained for five anatomical landmarks on the distal upper limb under two configurations: real-only (2,963 images) and real-synthetic mixed (3,863 images). Synthetic image quality was assessed via Local Binary Pattern (LBP) chi-squared distances and Gray-Level Co-occurrence Matrix (GLCM) features. All models were evaluated on 50 held-out real images from 18 participants using localization error (mm) and mean Average Precision (mAP). Real-to-synthetic LBP chi-squared distances (0.0155 ± 0.0042) fell within natural real-image variation (0.0107 ± 0.0117), confirming sufficient texture fidelity. Mixed training reduced the mean localization error across all six models. Under subject-level clustered bootstrap analysis (n = 18 participant clusters, 10,000 iterations), statistically significant improvements were observed in YOLO26x-pose (17.8%; p = 0.002), YOLO26s-pose (14.5%; p = 0.001), and HRNet-W48 (6.3%; p = 0.020). However, because the mixed training set contains approximately 30% more images and gradient updates than the real-only set, contributions from increased training volume, optimization steps, and synthetic data content cannot be fully disentangled. Detection confidence remained stable across conditions. All models achieved sub-3.1 mm accuracy under mixed training, approaching expert-level consistency. These findings offer practical guidance for integrating MetaHuman-rendered synthetic images into deep learning pipelines for Traditional Eastern Medicine applications when real data is scarce.