Related Experiment Video
Updated: Jul 3, 2026


Selecting Multiple Biomarker Subsets with Similarly Effective Binary Classification Performances
Published on: October 11, 2018
CarakaBinary: A binary-labelled dataset from early Āyurvedic texts for the identification of compound words in
Shriganesh Devaru Bhat1,2, Premjith B2
1Department of Amrita Darshanam, Amrita School of Arts, Humanities and Commerce, Coimbatore, Amrita Vishwa Vidyapeetham, Tamil Nadu, 641112, India.

Abstract:
Charaka-Binary, the presented domain-specific Ayurvedic textual dataset in this article, is intended to support natural language processing (NLP) tasks in the Sanskrit language, particularly in analyzing compound words. Charaka-Binary includes 31,179 instances comprising 23,224 non-compound words and 7,955 compound words in Devanāgarī script along with the relevant numerical labels, including "0" indicating non-compound words and "1" denoting compound words to support future computational tasks. The dataset provides a resource for extracting compound words from Sanskrit text. We utilized the publicly accessible ancient Ayurvedic literature, Carakasaṃhitā. Among the 7 chapters of Carakasaṃhitā, we employed the first chapter along with its 30 lessons and fourth chapters' two lessons as the foundation for dataset collection. The first phase of the dataset collection was to convert 228 pages of Carakasaṃhitā into individual .png files suitable for text extraction, while the second phase included the use of the Optical Character Recognition (OCR) technique to extract the text, followed by proofreading. Then the sentence segmentation step was carried out by word-level labeling into compound and non-compound word categories. The preprocessing steps, including proofreading, segmentation, and labeling, are carried out with the help of domain experts. Caraka-Binary can be used in both computational tasks, which include training models to identify Sanskrit compound words, as well as non-computational purposes, which encompass classroom teaching on Sanskrit compound words, comprehending their types, and analyzing compound patterns.
Related Concept Videos
 02:54
Classification of Elements and Compounds
Compounds are pure substances composed of two or more elements in fixed, definite proportions. Compounds are classified as ionic or molecular (covalent) based on the bonds...
 01:31
Classification of Systems-II
 01:11
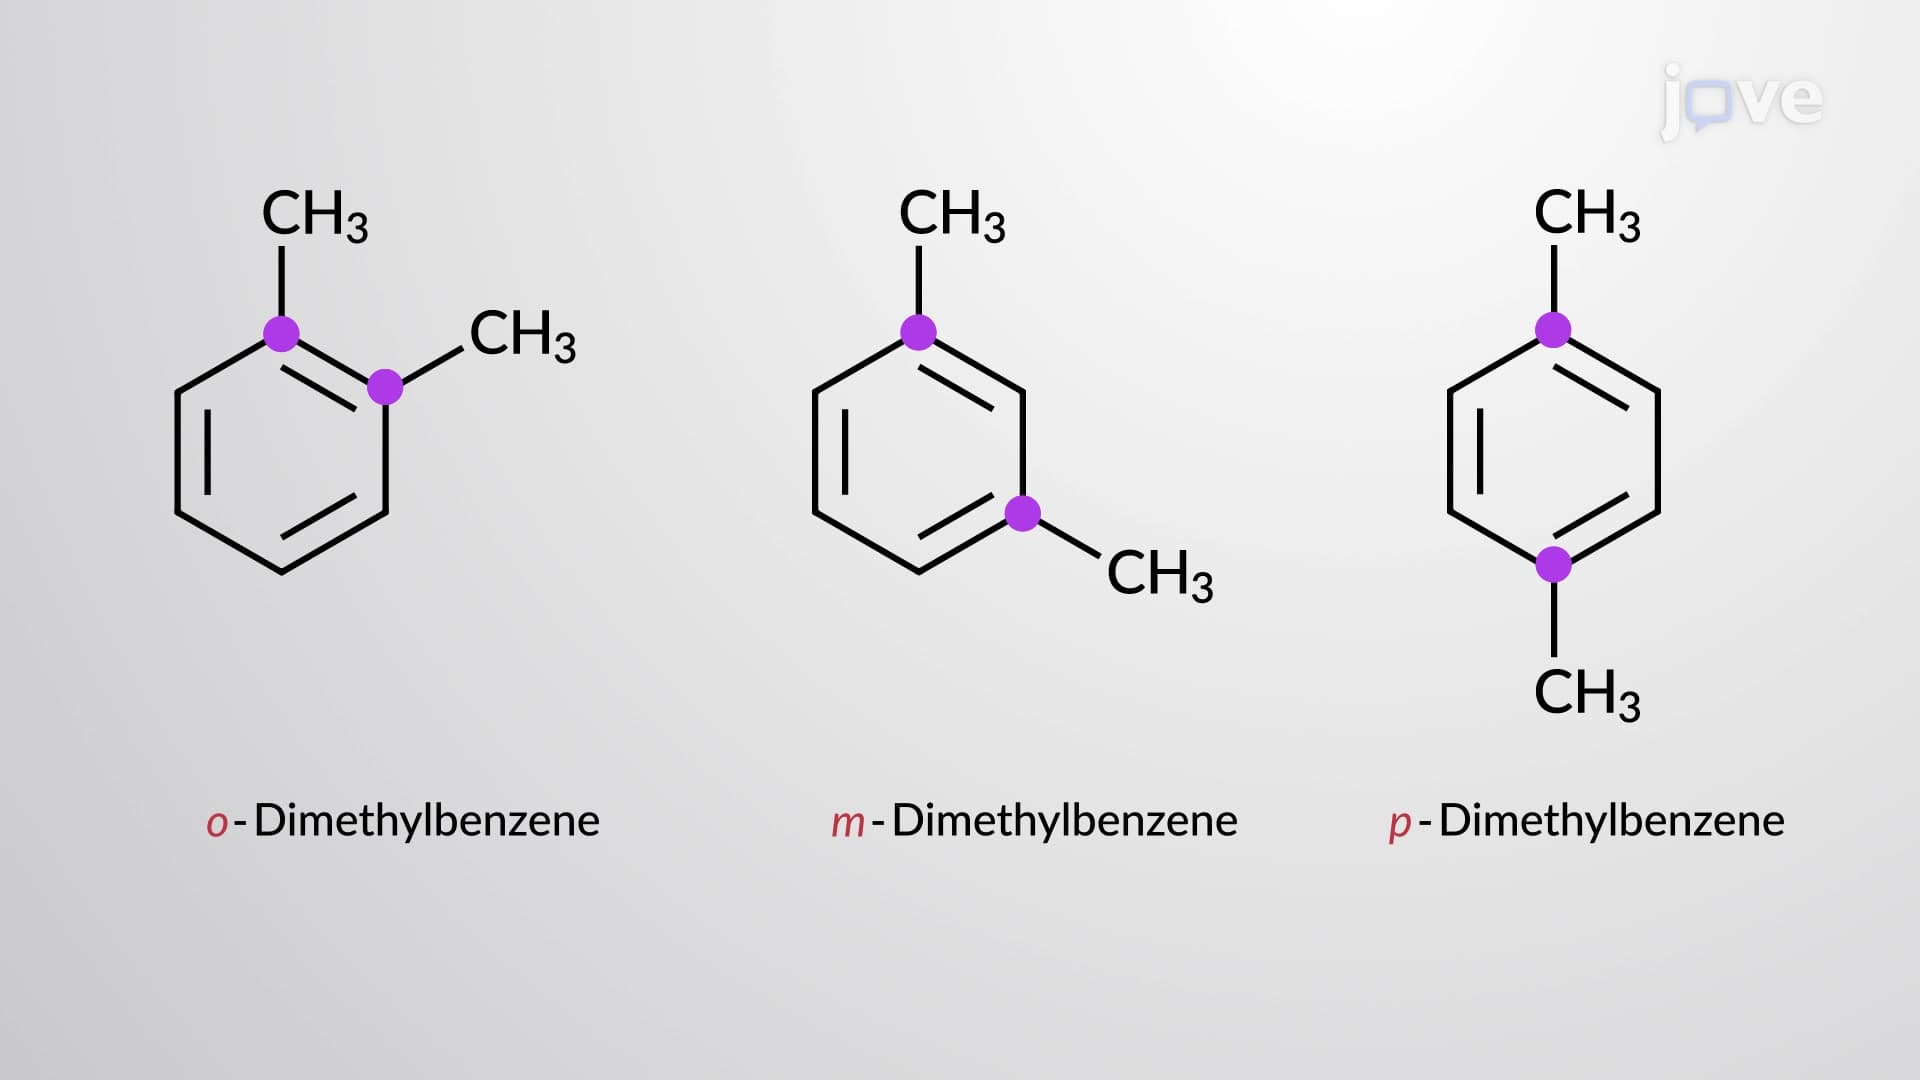
Nomenclature of Aromatic Compounds with Multiple Substituents
For disubstituted benzene derivatives, with two groups attached to the benzene ring, three constitutional isomers are possible. For example, consider dimethyl benzene, often called xylene, where the second methyl group can be substituted at the second, third, or fourth carbon. The relative position of the substituents is represented by prefixes ortho, meta, or...
 01:26
Classification of Systems-I
Homogeneity dictates that if an input x(t) is multiplied by a constant c, the output y(t) is multiplied by the same constant. Mathematically, this is expressed as:
 01:09
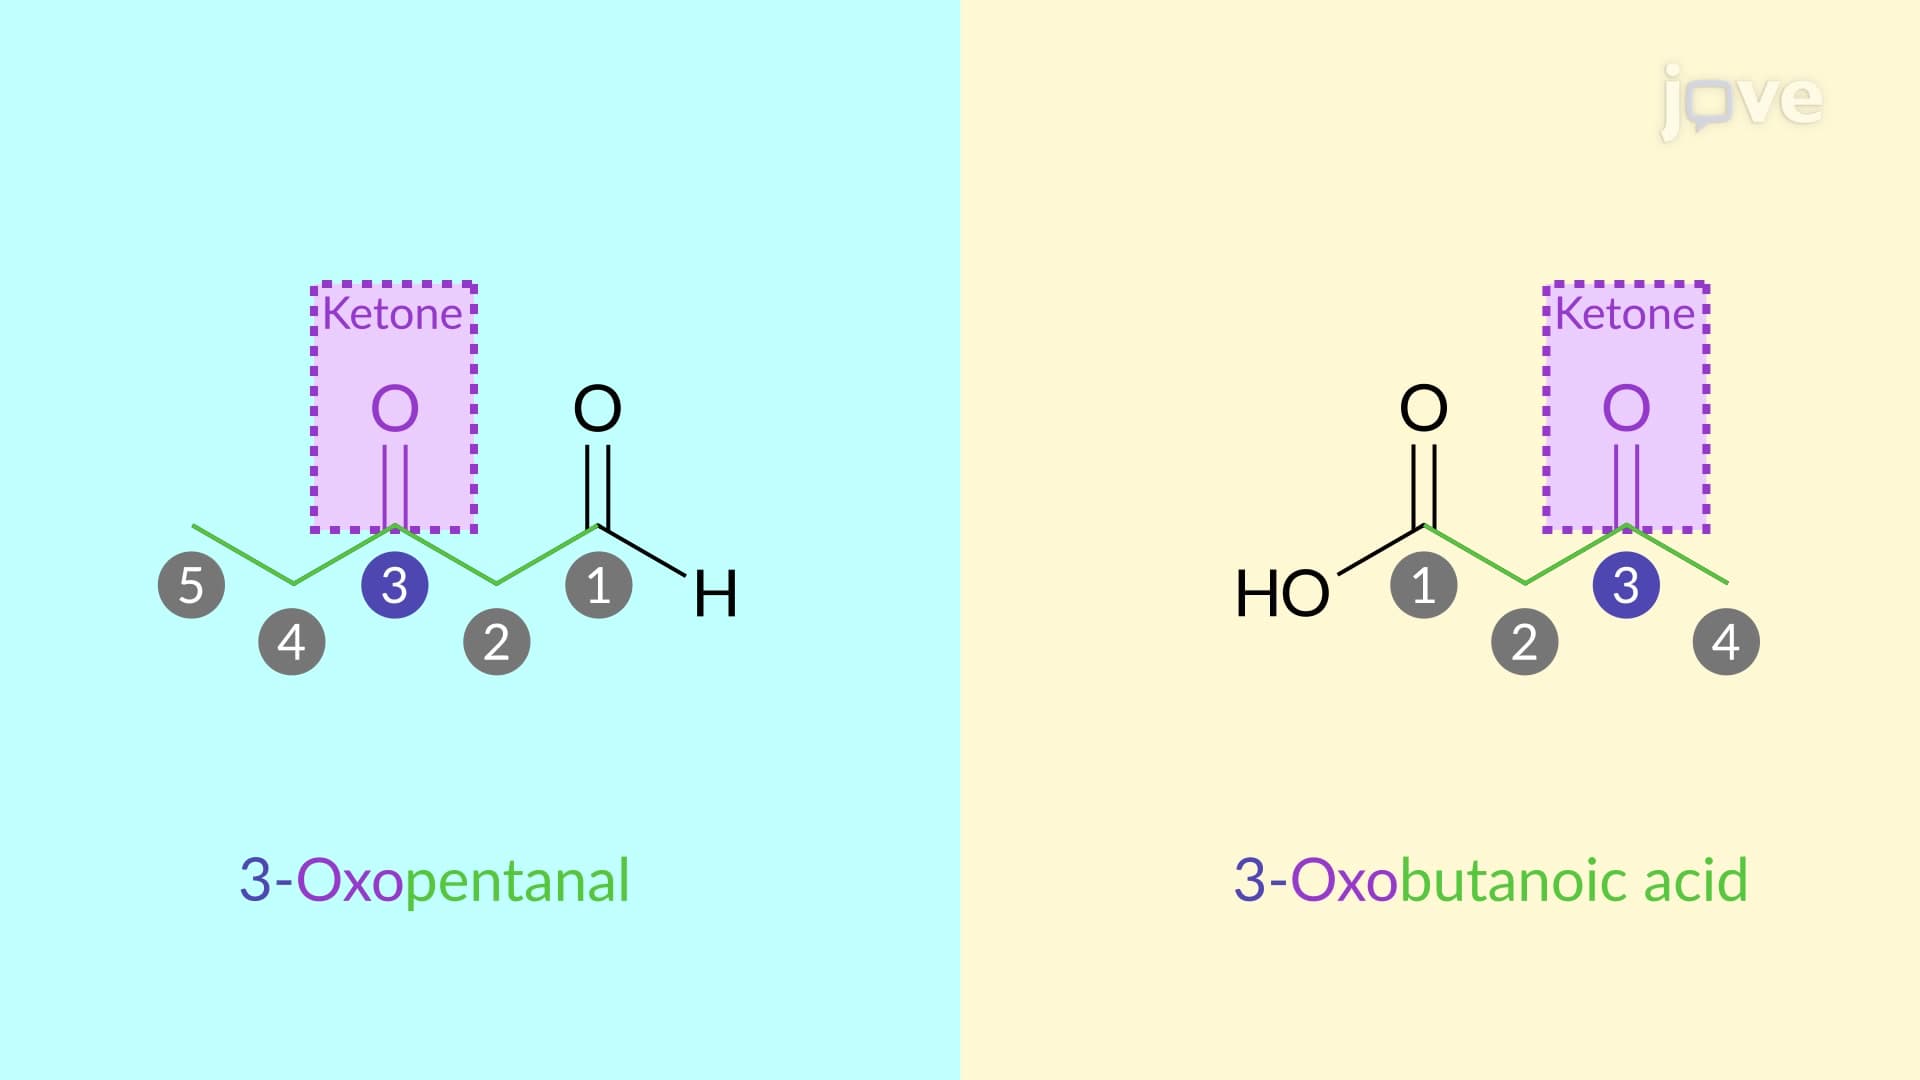
IUPAC Nomenclature of Ketones
 01:23
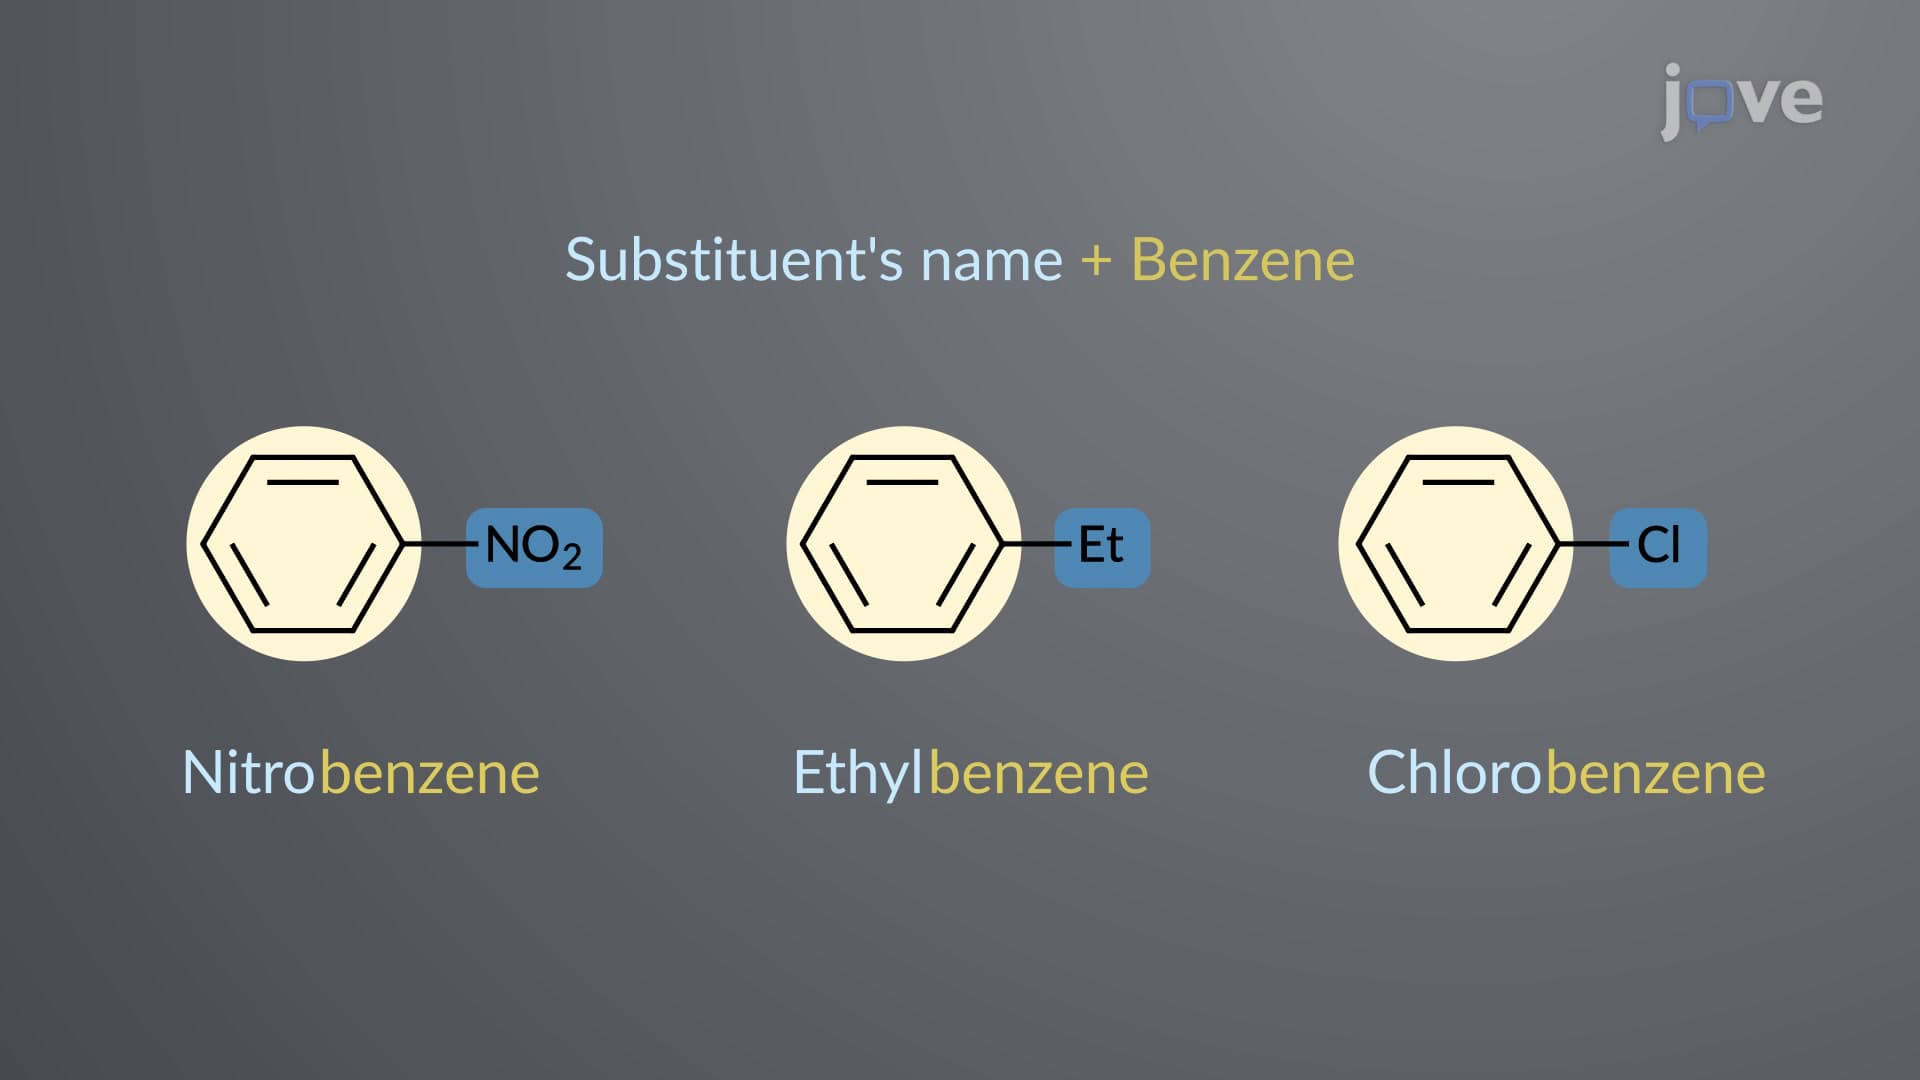
Nomenclature of Aromatic Compounds with a Single Substituent