Related Experiment Video
Updated: Jul 9, 2026
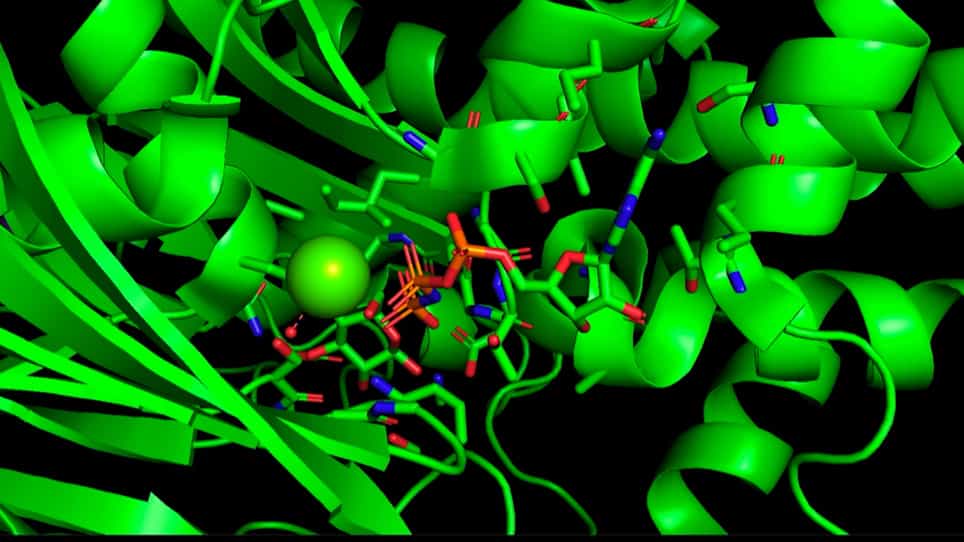

Modeling an Enzyme Active Site using Molecular Visualization Freeware
Published on: December 25, 2021
Deciphering key factors of active learning performance in biomolecular design
Yixuan Zhi1, Qixiu Du1, Han Yu1
1Ministry of Education Key Laboratory of Bioinformatics, Center for Synthetic and Systems Biology, Beijing National Research Center for Information Science and Technology, Department of Automation, Tsinghua University, Beijing 100084, China.

Motivation:
Employing machine learning (ML) to efficiently design biomolecules has become an emerging trend in genetic engineering. Active learning (AL) algorithms, as scalable approaches for ML-guided discovery, can automatically identify promising samples for function (i.e. fitness) optimization, and have therefore attracted growing interest across scientific domains. However, applying AL in genetic engineering presents several challenges. The regulatory patterns between sequence and fitness are highly complex, noisy, and sparse, making the existing evaluation of AL algorithm efficiency unreliable. Therefore, a comprehensive benchmark and thorough investigation into the key determinants of AL performance are urgently required to resolve these challenges.
Results:
We created a benchmark across multiple large-scale libraries of proteins and DNA regulatory sequences, evaluating uncertainty quantification (UQ) algorithms on metrics including calibration and accuracy, demonstrating the robustness and generality of ensemble-based algorithms. Moreover, we systematically assessed the efficiency of existing sampling strategies for fitness optimization. Our results show that no single sampling strategy is universally optimal across datasets, although greedy iterative strategies perform well in many practical scenarios. Finally, we evaluated the factors influencing optimization efficiency, and found that optimization efficiency is mainly determined by the choice of initial settings, distribution sparsity, and sequence similarity in high-fitness regions, rather than by the specific AL algorithm. Based on this, we proposed two quantifiable metrics to interpret the strategy performance and provide a practical reference for strategy selection. These findings offer valuable insights for the implementation of AL pipelines in biomolecular sequence design scenarios.
Availability And Implementation:
The source code and supporting datasets used in this work are openly available on GitHub at https://github.com/WangLabTHU/biomolecule-al-decipher and have been archived on Zenodo at https://doi.org/10.5281/zenodo.19661002.
More Related Videos
Related Concept Videos
 01:28
Structure-Activity Relationships and Drug Design
SAR studies the intricate relationship between a drug's chemical structure and biological activity. It focuses on understanding how modifications to a drug's structure can influence its...
 01:22
Biopharmaceutical Factors Influencing Drug Product Design: Overview
 01:17
Factors Affecting Activity Coefficient
The activity coefficient value for an ion is close to one when the solution has almost zero ionic strength, i.e., when the solution shows close to ideal behavior. As the ionic strength of the solution increases from 0 to 0.1 mol/L, a decrease in the...
 01:28
Biopharmaceutics and Pharmacokinetics: Overview
 02:35
Noncovalent Attractions in Biomolecules
Four types of noncovalent interactions are hydrogen bonds, van der Waals forces, ionic bonds, and hydrophobic interactions.
Hydrogen bonding results from the electrostatic attraction of a hydrogen atom covalently bonded to a strong-electronegative atom like oxygen,...
 01:13
Introduction to Mechanisms of Enzyme Catalysis