Related Experiment Video
Updated: Jul 12, 2026
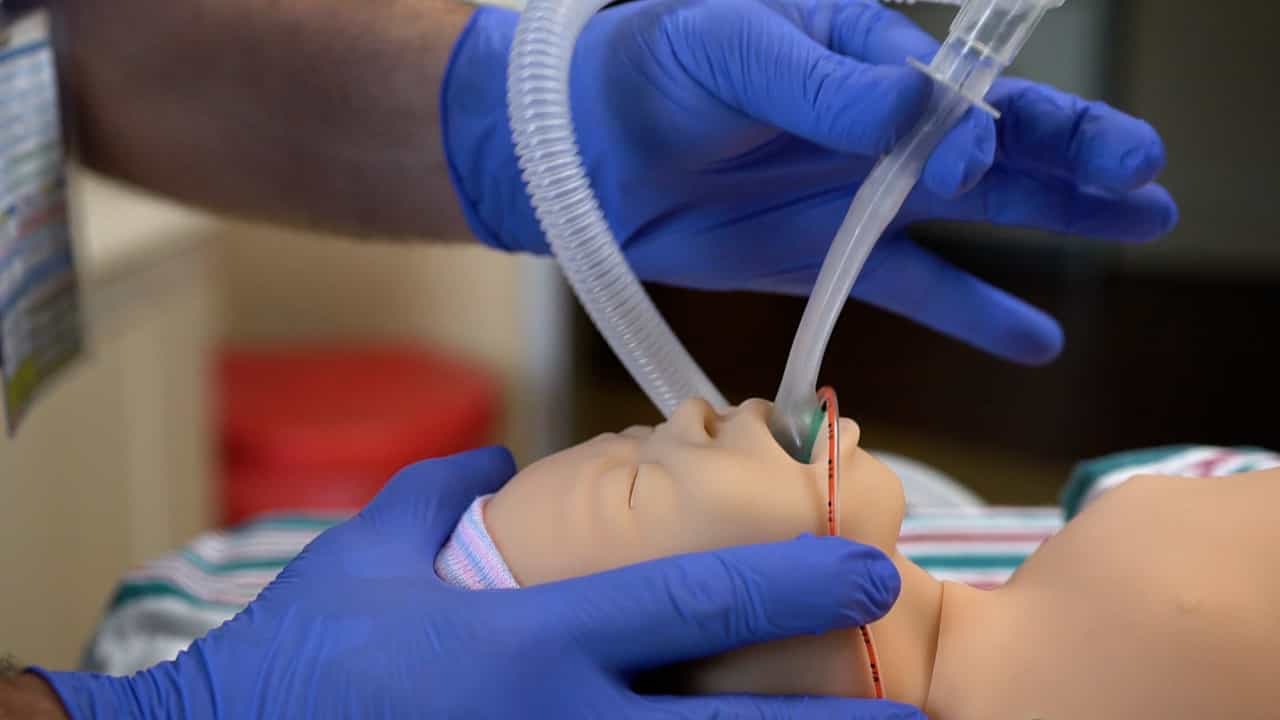

Laryngeal Mask Airway (LMA) Placement in a Neonatal Patient Simulator Using a Non-Inflatable Supraglottic Airway (SGA)
Published on: July 14, 2023
Performance of large language models in neonatal resuscitation assessments versus healthcare providers: an
Chenguang Xu1,2, Yihua Chen1, Shelley Skelding3
1NICU, The University of Hong Kong-Shenzhen Hospital, Shenzhen, China.

Background:
Artificial intelligence and large language models (LLMs) have developed rapidly in recent years and involved in medical education, in addition to clinical care. However, it remains unknown how the performance of LLMs in neonatal resuscitation compares to that of healthcare professionals (HCPs). In this exploratory study, we aimed to investigate and compare the performance of LLMs with those of HCPs on 3 sources of examination questions in the neonatal resuscitation training in Canada and China.
Methods:
In this bi-center study, we evaluated the overall accuracy, accuracy across question types, and reliability of LLMs' (ChatGPT-5 and DeepSeek-R1) responses to neonatal resuscitation questions from workshop in China, NRP® textbook (8th edition), and Kahoot quizzes in Canada. Each LLM was tested three times per question with one-week intervals in August and September, 2025. Comparisons with historical scores of HCPs in the training courses in China (2022-2024) and Canada (2022-2025) were performed.
Results:
Both LLMs performed comparably to HCPs in Chinese examinations, and showed similar accuracy in NRP® textbook questions with higher scores on multiple-choice than on short answer questions. ChatGPT achieved higher accuracy than DeepSeek and HCPs in the Kahoot quizzes. ChatGPT also had higher accuracy on scenario-based than on non-scenario-based questions in the workshop examination. High reliability of LLMs' responses was found (Fleiss' Kappa>0.89).
Conclusion:
Both ChatGPT and DeepSeek achieved accuracy comparable to that of HCPs and showed high consistency on selected neonatal resuscitation written examinations. The findings warrant further research to explore their potential integration in neonatal resuscitation training.