Related Experiment Videos
Intelligent optimization of personalized learning path based on transformer and reinforcement learning
1School of Information and Intelligent Engineering, Zhangjiajie College, Zhangjiajie, 427000, China.

Abstract:
Smart education platforms accumulate large volumes of learning resources and interaction logs. However, fixed recommendation sequences are often unable to adapt to differences in knowledge foundations, learning behaviors, and cognitive progress among learners. Existing learning path recommendation methods primarily focus on static matching and single-step ranking, while providing limited support for modeling learning state evolution and long-term path benefits. To improve learning resource recommendation accuracy, path continuity, and learning completion outcomes, a personalized learning path (PLP) optimization model integrating Transformer and Reinforcement Learning is developed. The model aims to generate learning resource sequences that align with individual cognitive processes through dynamic state awareness, sequential policy decision-making, and the incorporation of educational constraints. First, learning behavior sequences, knowledge point information, answer feedback, resource access records, and time intervals are encoded within a unified framework. A Transformer is employed to capture long-range dependencies and dynamic state features. Second, PLP generation is formulated as a continuous decision-making process, in which RL performs policy search within the candidate resource space. Finally, knowledge prerequisite relationships, difficulty progression rules, learning load boundaries, and a multi-objective reward function are incorporated into a unified optimization framework. Offline simulation experiments are conducted on three public datasets, namely EdNet, ASSISTments, and Junyi. Performance is compared with Self-Attentive Knowledge Tracing, Separable Self-Attentive Neural Knowledge Tracing Plus, Unified Knowledge Tracing (UniKT), and Time-Aware Reinforcement Learning. Experimental results indicate that Transformer and Reinforcement Learning for Learning Path (TFRL-Path) achieves a hit ratio of 0.846 on EdNet, exceeding UniKT by 0.025. On ASSISTments, the mean average precision reaches 0.737 and the completion rate reaches 0.801. On Junyi, precision reaches 0.736 and convergence epochs decrease to 38. The cross-dataset average composite score reaches 0.798 with a standard deviation of 0.028. The prerequisite satisfaction rate reaches 0.872, while the resource repetition rate decreases to 0.121. These findings suggest that closed-loop coordination among state representation, policy optimization, and educational constraints contributes to improvements in personalized learning path recommendation quality.
Related Concept Videos
 01:18
Introduction to Learning
In contrast to learned behaviors, unlearned behaviors such as crying, sexual...
 01:21
Cognitive Learning
E. C. Tolman's theory of purposive behavior emphasizes that much behavior is goal-directed. He argued that to understand behavior, we must look at the entire sequence of actions leading to a goal. For instance, high school students study hard, not just due to past reinforcement but also to achieve the goal of getting into a good college.
Tolman introduced the idea that behavior is influenced by...
 01:12
Observational Learning
 01:22
Purposive Learning
 01:26
The Ideal Transformer
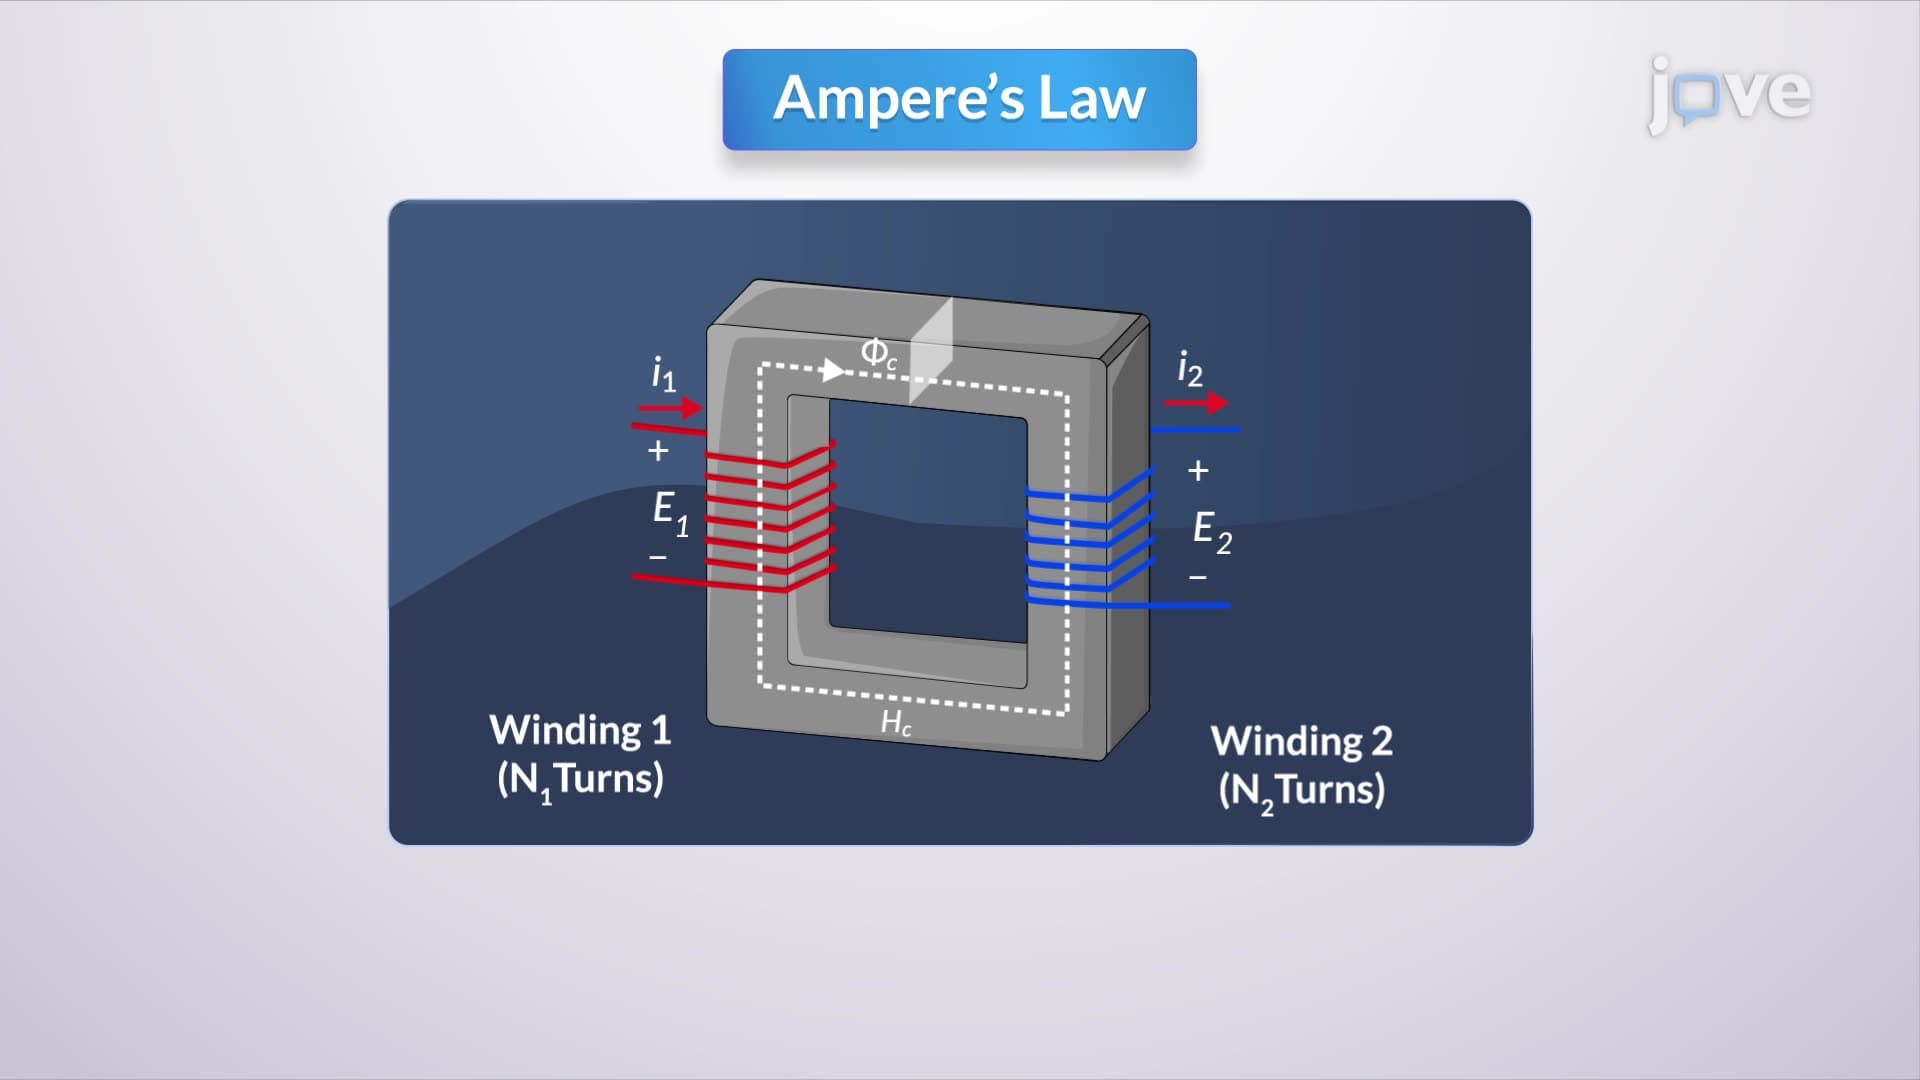
Ampere's Law forms the basis of understanding the magnetic field within the transformer. It states that the integral of the magnetic field intensity's tangential component...
 01:26
Transformers
The iron core has a substantial relative permeability. Therefore, the magnetic field lines generated due to the current in one winding are almost entirely confined within the core, such that the same magnetic flux permeates each turn of both...