Related Experiment Video
Updated: Aug 6, 2026
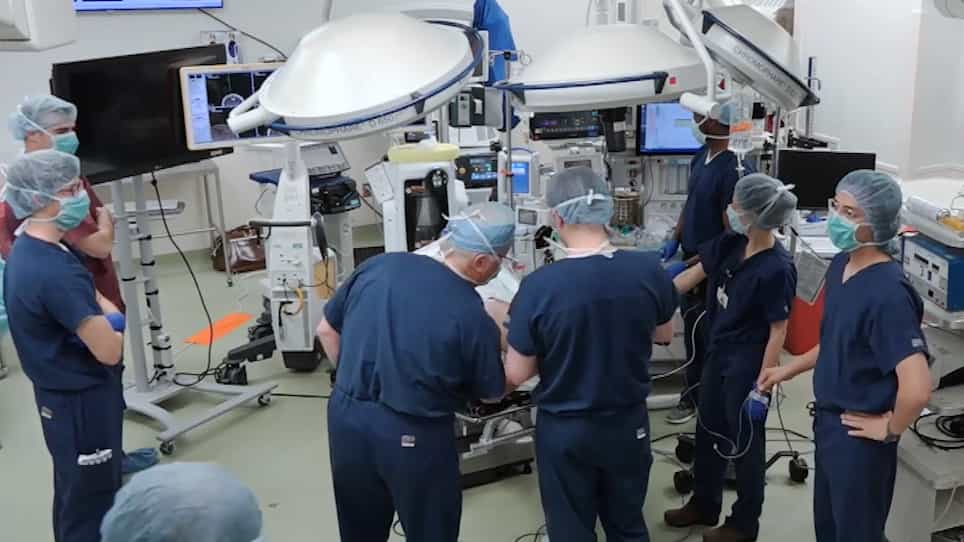

Translational Brain Mapping at the University of Rochester Medical Center: Preserving the Mind Through Personalized Brain Mapping
Published on: August 12, 2019
Patient and physician perspectives on large language model generated responses about brain aneurysm
Joon Hyeok Choi1, Marcella Ruppert-Gomez1, Liam M Shanahan1,2
1Department of Neurosurgery, Boston Children's Hospital, Harvard Medical School, 300 Longwood Ave, Boston, MA, 02115, USA.

Purpose:
Large language models (LLMs) are becoming increasingly popular in medicine and neurosurgery. Because LLMs are not trained in specific subspecialties or diagnoses, a better understanding of the implications, effectiveness, and use of LLMs by users and clinicians is necessary. To better understand LLM's effectiveness in neurosurgery and aneurysms, we compared community and physician feedback on ChatGPT 4o and Gemini 1.5 Flash responses to frequently asked questions regarding brain aneurysms.
Methods:
External surveys were made available on the Brain Aneurysm Foundation page for patients and families to complete and internal surveys were distributed and completed by physicians in the department of neurosurgery at Boston Children's Hospital.
Results:
In the community survey assessing response usefulness and helpfulness, ChatGPT and Gemini provided different response quality despite similar AI sentiment. Clarity of procedure explanation (p = 0.04), discussion of alternative procedures (p = 0.02), and discussion of procedure risks (p = 0.01) were different. The physician survey, assessing response accuracy, safety, and helpfulness, also found differences in multiple domains. Importantly, differences were found in consistency with current medical knowledge and practice guidelines (p = 0.001), omittance of key points (p < 0.001), and amount of clinically relevant detail included (p < 0.001).
Conclusion:
LLMs had variable performance across several key domains, consistent with previous research. Despite the apparent advantages of ChatGPT, physician feedback highlighted the continued need for information oversight. Interestingly, community participants consistently found LLM responses to be better than physician ones, while physicians found LLM responses to be similar or somewhat worse than the one they would have provided.

