Related Experiment Video
Updated: Aug 6, 2026
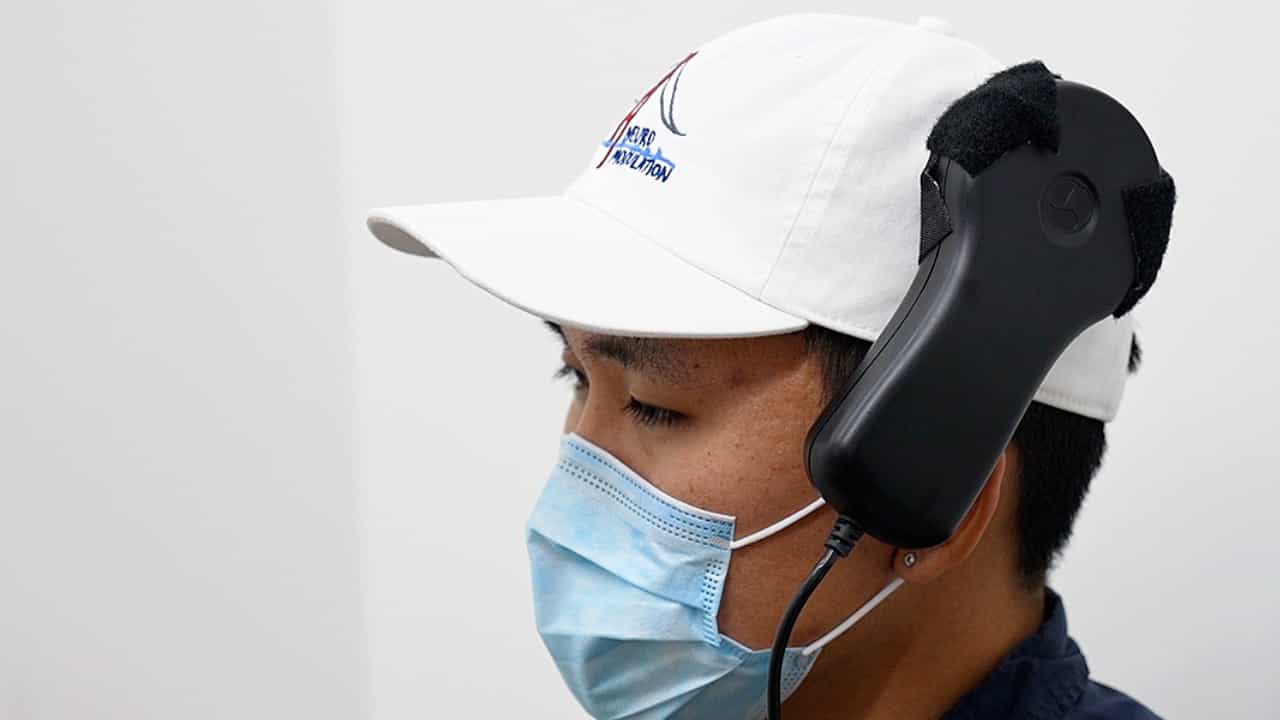

Closed-Loop Neurostimulation for Biomarker-Driven, Personalized Treatment of Major Depressive Disorder
Published on: July 7, 2023
Hierarchical Self-Supervised Representation Learning for Depression Detection from Speech

Abstract:
Speech-based depression detection (SDD) offers a non-invasive and scalable complement to conventional clinical assessment, but reliable detection remains challenging because depression-related speech markers are subtle, heterogeneous, and irregularly distributed over time. Although self-supervised learning (SSL) speech models provide informative multi-layer representations, most SSL-based SDD methods either select a single layer or collapse all layers into a weighted sum. Such strategies merge functionally different SSL layers into a single stream, limiting the model's ability to capture interactions between low-level acoustic markers and higher-level context. To address this limitation, we propose HAREN CTC, a hierarchical framework that learns two complementary SSL representation streams and connects them through semantic-conditioned cross-attention. This design enables the model to emphasize acoustic patterns that are informative under the surrounding semantic context. To address the sparse and irregular temporal distribution of depression-related markers, we further introduce an auxiliary Connectionist Temporal Classification (CTC) objective that weakly aligns temporal token representations with HuBERT-derived pseudo-token targets. Experiments on DAIC-WOZ and MODMA show that HAREN-CTC out performs strong baselines under both fixed-split bench mark and subject-level cross-validation settings, achieving Macro F1 scores of 0.81 and 0.82, respectively, in the fixed split setting and maintaining consistent gains across most metrics under cross-validation. These results suggest that modeling acoustic-semantic interactions can improve the robustness of speech-based depression assessment.