Related Experiment Video
Updated: Aug 9, 2026
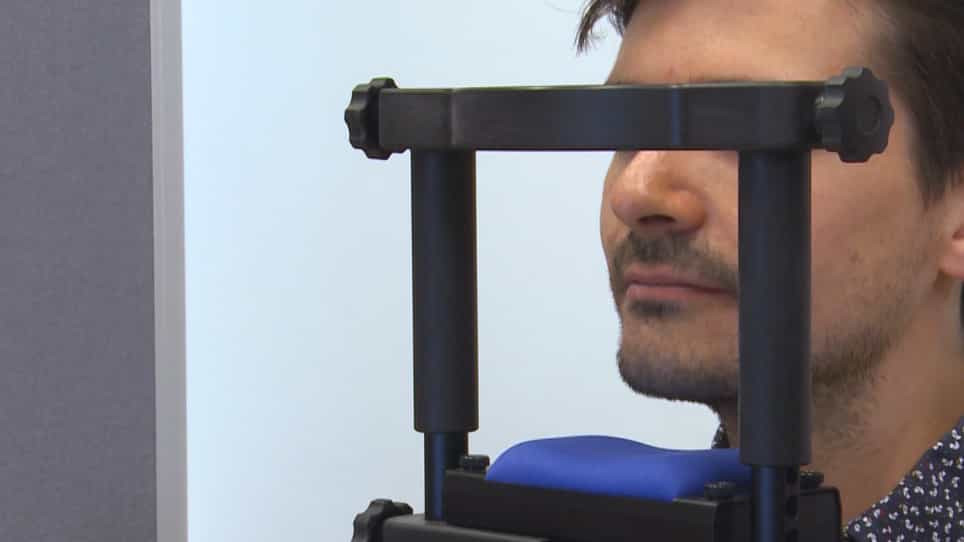

Eye Tracking During Visually Situated Language Comprehension: Flexibility and Limitations in Uncovering Visual Context Effects
Published on: November 30, 2018
Self-Chained Dynamic Context Perception to Tracking by Natural Language Specification

Abstract:
Vision-language cross-modal learning has significantly improved Tracking by Natural Language specification (TNL). Most existing TNL methods follow a Siamese-like matching paradigm, where visual search-region features and language-query features are aligned with the aid of pre-trained image-text representations. Although such representations provide strong static semantic cues, they are often less effective in explicitly modeling target-state changes described by action-related phrases in natural language queries. As a result, dynamic linguistic cues, such as verbs and motion-related descriptions, may be insufficiently emphasized during cross-modal matching. To address this issue, we propose Self-Chained Dynamic Context Perception (SeDCP), a self-chained framework for explicit dynamic query modulation and language-guided visual refinement in TNL. Specifically, SeDCP consists of two coupled chains. First, the Forward Chain performs visual-evidence-guided dynamic query modulation by injecting trajectory-aware spatiotemporal cues into the language representation, thereby enhancing phrases that describe target-state changes. Second, the Backward Chain uses the dynamically enhanced query representation to refine visual spatiotemporal features, strengthening the alignment between language cues and target-state evolution. In addition, we introduce sequence-level matching rather than isolated pairwise matching to better exploit temporal dynamics, and design a Global-Local enhanced video Transformer to capture both long-range contextual dependencies and fine-grained target details. Extensive experiments on seven standard TNL benchmarks and an additional unseen $\mathrm {LaSOT}_{\mathrm {ext}}$ benchmark demonstrate that SeDCP consistently outperforms state-of-the-art methods and generalizes well to unseen categories and video characteristics.
Related Concept Videos
 01:28
Perception
Bottom-up processing begins at the sensory level, where receptors detect external environmental stimuli. These could include the tactile sensation of...
 01:28
Automatic Processing and Automatic Social Behavior
 01:22
Chunking and Rehearsal in Sensory Memory
 01:27
Language and Cognition
 01:24
Natural and Artificial Concepts
 01:03
Inertial Frames of Reference