Related Experiment Video
Updated: Aug 14, 2026
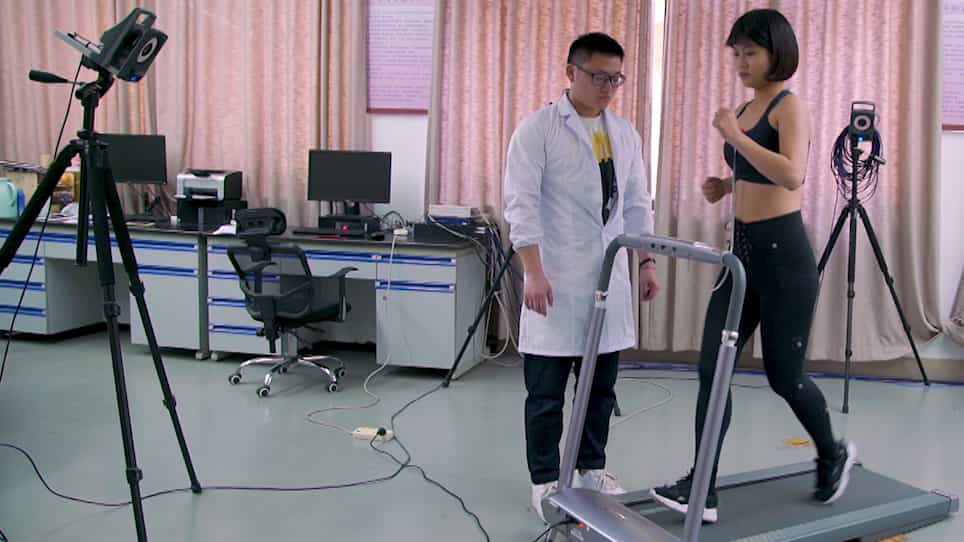

Comparative Analysis of Lower Limb Kinematics between the Initial and Terminal Phase of 5km Treadmill Running
Published on: July 17, 2020
Using Machine Learning to Explain Recreational Running Injury: An Exploratory Classification Analysis
Bradley S Neal1,2, Stella Hadjiantoni3, Allison H Gruber4
1Sports and Exercise Medicine, Queen Mary University of London, London, United Kingdom.

Context:
Running is good for overall health but has a poorly understood risk of injury. Wearable technology and machine learning (ML) offer solutions to this problem. Using ML, we aimed to determine (1) the key important factors that increase the probability of classifying a run as belonging to an injured group, (2) the best-performing ML model, and (3) the sample size required for future substantive studies.
Design:
Exploratory classification analysis.
Methods:
Heart rate/inertial measurement unit/GPS data were extracted from the wristwatches of 88 recreational runners (65 injured and 23 uninjured) during a 12-week prospective cohort. Data were extracted from each run completed by participants, and each run was considered an independent event. Variance inflation factor was used to check for collinearity, and the robust normalizer was used to scale numerical features. Seven ML models were used and validated using repeated stratified 10-fold cross validation. Accuracy, precision, and recall were used to evaluate ML model performance and SHapley Additive exPlanations to determine the relative importance of the individual factors.
Results:
The final data set had 29 numeric factors, with 4758 run instances from 80 participants. Participants completed between 6 and 148 (mean: 55.5) runs between November 2, 2022, and February 5, 2023. The 4 best-performing ML models were CatBoost, GMB, Light Gradient Boosting Machine, and GXBoost (average model performance > 0.90). CatBoost was the best-performing model, 96% correct in classifying runs from the injured groups. Critical power was the most important factor across all 4 algorithms, with higher values increasing the probability of classifying a run as belonging to the injured group.
Conclusion:
Future cohort studies using ML to explain running-related injury development should use boosting ML models, specifically CatBoost, and include critical power. We advise against interpreting these results as a causal explanation for injury development, and model performance may be overestimated due to our validation approach.