Related Experiment Videos
In situ trainable optical convolution enabled by an AWG core and gradient-based model-free optimization

Abstract:
We propose an optical tensor processing unit (OTPU) centered on an arrayed waveguide grating (AWG) and trained with a gradient-based model-free optimization (G-MFO) framework. The AWG performs parallel multiply-accumulate (MAC) operations via spectral-spatial mapping and wavelength tuning, with signed weights directly encoded using Mach-Zehnder modulators (MZMs). This architecture establishes a scalable foundation where throughput can be increased by leveraging additional wavelength channels. Algorithmically, G-MFO enables in-situ black-box optimization of the non-differentiable wavelength-encoded weights, while gradient descent updates the electronic weights to ensure reliable training under physical non-idealities. Simulations demonstrate that our co-designed system achieves 98.80% accuracy on MNIST classification with a computational precision of 7.40 bits (effective number of bits, ENOB). Simulation results further demonstrate versatile edge extraction on both handwritten digits and breast ultrasound images. This work shows that an AWG core, combined with a dedicated in-situ training algorithm, offers a scalable and training-efficient pathway for practical photonic neural network accelerators.
Related Concept Videos
 01:19
Gradient Vectors and Their Applications
 01:27
Gradient Fields
 01:25
Maximizing the Directional Derivative
 01:27
Significance of the Gradient Vector
 01:20
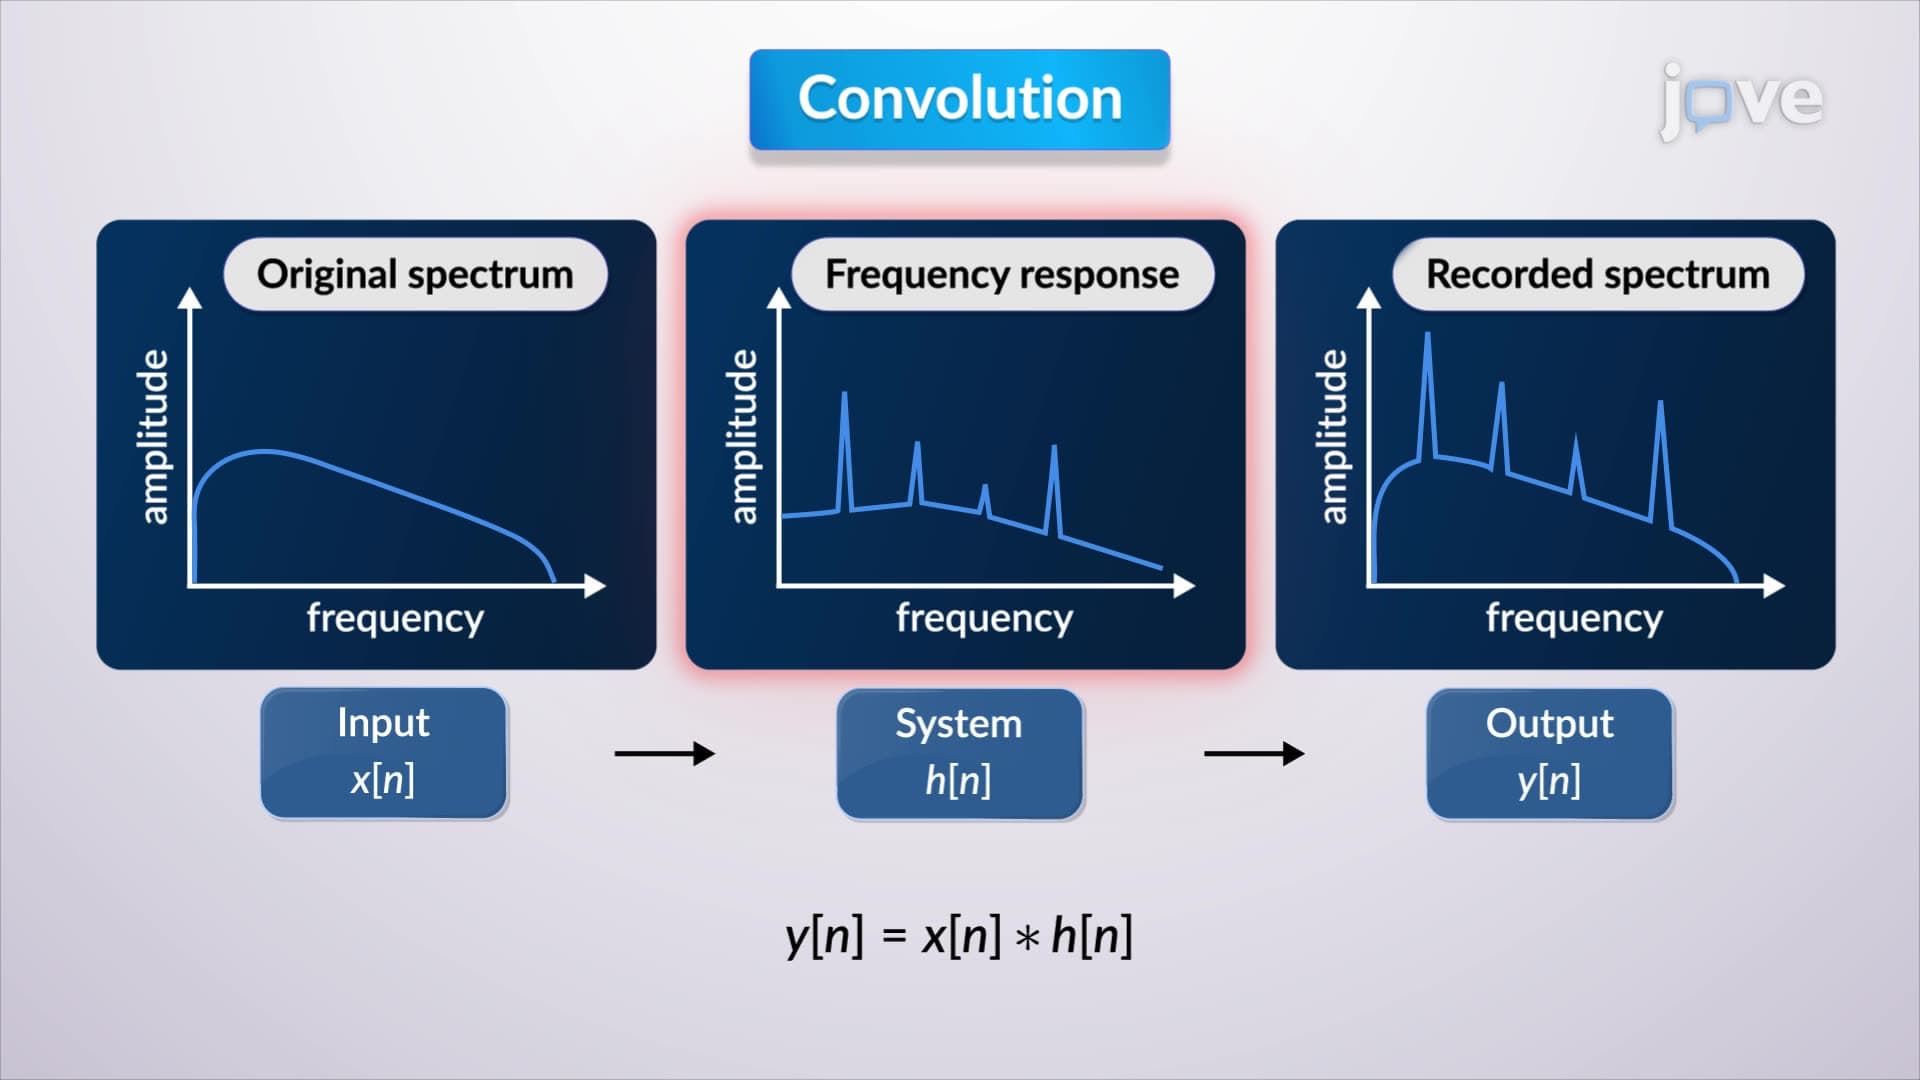
Deconvolution
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
 01:18
Reducing Line Loss
With a step-up transformer at the source, the voltage is increased, thereby reducing the current in the transmission lines since power loss in...